diff --git a/.github/workflows/_build-wheel.yaml b/.github/workflows/_build-wheel.yaml
new file mode 100644
index 0000000000..4cf5da693a
--- /dev/null
+++ b/.github/workflows/_build-wheel.yaml
@@ -0,0 +1,184 @@
+name: _build-wheel
+
+# Shared build for one wheel variant (matrixed over Python version), used by the
+# Release and Pre-Release workflows so both build identically.
+
+on:
+ workflow_call:
+ inputs:
+ runner:
+ type: string
+ required: true
+ container:
+ # x86 builds run in manylinux2_28 so the wheel's libstdc++/glibc floor
+ # stays low enough to import on RHEL/Rocky/Alma 8+. '' = bare runner.
+ type: string
+ default: ''
+ python-versions:
+ type: string
+ default: '["3.10", "3.11", "3.12", "3.13"]'
+ cuda:
+ # none | container | sbsa-12.8 | sbsa-13.0
+ type: string
+ default: none
+ cmake-args:
+ # Space-separated -D flags. No semicolons; use ep-torch-versions for those.
+ type: string
+ required: true
+ cmake-generator:
+ type: string
+ default: ''
+ ep-torch-versions:
+ type: string
+ default: ''
+ build-with-ep:
+ type: string
+ default: '0'
+ variant-flag:
+ # build_wheel.sh variant set to 1, e.g. CU13_BUILD, NON_CUDA_BUILD
+ type: string
+ default: ''
+ torch-cuda-arch-list:
+ type: string
+ default: ''
+ build-nvlink-allocator:
+ type: boolean
+ default: false
+ artifact-prefix:
+ type: string
+ required: true
+
+env:
+ SCCACHE_GHA_ENABLED: "true"
+
+jobs:
+ build:
+ runs-on: ${{ inputs.runner }}
+ container: ${{ inputs.container }}
+ permissions:
+ contents: read
+ strategy:
+ matrix:
+ python-version: ${{ fromJSON(inputs.python-versions) }}
+ env:
+ BUILD_WITH_EP: ${{ inputs.build-with-ep }}
+ TORCH_CUDA_ARCH_LIST: ${{ inputs.torch-cuda-arch-list }}
+ CMAKE_ARGS: ${{ inputs.cmake-args }}
+ CMAKE_GEN: ${{ inputs.cmake-generator }}
+ EP_TORCH_VERSIONS_INPUT: ${{ inputs.ep-torch-versions }}
+ VARIANT_FLAG: ${{ inputs.variant-flag }}
+ steps:
+ - name: Checkout source
+ uses: actions/checkout@v4
+
+ - name: Mark workspace safe for git (container runs as root)
+ if: ${{ inputs.container != '' }}
+ run: git config --global --add safe.directory '*'
+
+ - name: Set version from tag
+ run: echo "VERSION=${GITHUB_REF_NAME#v}" >> "$GITHUB_ENV"
+
+ - name: Select Python ${{ matrix.python-version }} from manylinux image
+ if: ${{ inputs.container != '' }}
+ run: |
+ PYV_NODOT=$(echo "${{ matrix.python-version }}" | tr -d '.')
+ PYBIN="/opt/python/cp${PYV_NODOT}-cp${PYV_NODOT}/bin"
+ echo "$PYBIN" >> "$GITHUB_PATH"
+ "$PYBIN/pip" install --quiet "cmake<4" setuptools wheel
+
+ - name: Set up Python ${{ matrix.python-version }}
+ if: ${{ inputs.container == '' }}
+ uses: actions/setup-python@v5
+ with:
+ python-version: ${{ matrix.python-version }}
+
+ - name: Free up disk space
+ if: ${{ inputs.container == '' }}
+ run: |
+ sudo rm -rf /usr/share/dotnet /opt/ghc /opt/hostedtoolcache/CodeQL /usr/local/lib/android
+ df -h
+
+ - name: Install CUDA Toolkit (arm64 SBSA)
+ if: ${{ startsWith(inputs.cuda, 'sbsa-') }}
+ run: |
+ ver="${{ inputs.cuda }}"; ver="${ver#sbsa-}"
+ wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/sbsa/cuda-keyring_1.1-1_all.deb
+ sudo dpkg -i cuda-keyring_1.1-1_all.deb
+ sudo apt-get update
+ sudo apt-get install -y "cuda-toolkit-${ver/./-}"
+ echo "/usr/local/cuda/bin" >> "$GITHUB_PATH"
+ /usr/local/cuda/bin/nvcc --version
+
+ - name: Run sccache-cache
+ uses: mozilla-actions/sccache-action@v0.0.9
+
+ - name: Configure sccache
+ uses: actions/github-script@v7
+ with:
+ script: |
+ core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
+ core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
+
+ - name: Configure project
+ run: |
+ SUDO=""; [ "$(id -u)" -ne 0 ] && SUDO="sudo"
+ if [ -n "$SUDO" ] && command -v apt-get >/dev/null 2>&1; then
+ $SUDO apt-get update -y || true
+ fi
+ $SUDO bash -x dependencies.sh -y
+ echo "/usr/local/go/bin" >> "$GITHUB_PATH"
+ gen=(); [ -n "$CMAKE_GEN" ] && gen=(-G "$CMAKE_GEN")
+ ep=(); [ -n "$EP_TORCH_VERSIONS_INPUT" ] && ep=(-DEP_TORCH_VERSIONS="$EP_TORCH_VERSIONS_INPUT")
+ mkdir -p build && cd build
+ # shellcheck disable=SC2086
+ cmake "${gen[@]}" .. $CMAKE_ARGS "${ep[@]}" -DPython3_EXECUTABLE="$(which python3)"
+
+ - name: Build project
+ run: |
+ for dir in /usr/local/cuda/lib64/stubs /usr/local/cuda/targets/*/lib/stubs; do
+ [ -d "$dir" ] && export LIBRARY_PATH="$dir:${LIBRARY_PATH:-}"
+ done
+ [ -d /usr/local/cuda ] && export CUDA_HOME=/usr/local/cuda
+ SUDO=""; [ "$(id -u)" -ne 0 ] && SUDO="sudo -E"
+ cd build
+ cmake --build . -j"$(nproc)"
+ $SUDO cmake --install .
+
+ - name: Build nvlink_allocator.so
+ if: ${{ inputs.build-nvlink-allocator }}
+ run: |
+ export PATH=/usr/local/nvidia/bin:/usr/local/nvidia/lib64:$PATH
+ if [ -d /usr/local/cuda/lib64/stubs ]; then
+ export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:${LD_LIBRARY_PATH:-}
+ export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:${LIBRARY_PATH:-}
+ fi
+ mkdir -p build/mooncake-transfer-engine/nvlink-allocator
+ cd mooncake-transfer-engine/nvlink-allocator
+ bash build.sh ../../build/mooncake-transfer-engine/nvlink-allocator/
+
+ - name: Run sccache stat for check
+ if: ${{ env.SCCACHE_PATH != '' }}
+ run: ${SCCACHE_PATH} --show-stats
+
+ - name: Generate Python version tag
+ id: pytag
+ run: echo "tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> "$GITHUB_OUTPUT"
+
+ - name: Build Python wheel
+ run: |
+ [ -d /usr/local/cuda ] && export CUDA_HOME=/usr/local/cuda
+ export LD_LIBRARY_PATH="${LD_LIBRARY_PATH:-}:/usr/local/lib"
+ variant=()
+ [ -n "$VARIANT_FLAG" ] && variant=("$VARIANT_FLAG=1")
+ env "${variant[@]}" \
+ PYTHON_VERSION="${{ matrix.python-version }}" \
+ OUTPUT_DIR="dist-py${{ steps.pytag.outputs.tag }}" \
+ ./scripts/build_wheel.sh
+ env:
+ VERSION: ${{ env.VERSION }}
+
+ - name: Upload Python wheel artifact
+ uses: actions/upload-artifact@v4
+ with:
+ name: ${{ inputs.artifact-prefix }}-py${{ steps.pytag.outputs.tag }}
+ path: mooncake-wheel/dist-py${{ steps.pytag.outputs.tag }}/*.whl
diff --git a/.github/workflows/_publish-wheel.yaml b/.github/workflows/_publish-wheel.yaml
new file mode 100644
index 0000000000..c5bab698dd
--- /dev/null
+++ b/.github/workflows/_publish-wheel.yaml
@@ -0,0 +1,49 @@
+name: _publish-wheel
+
+# Shared publish tail: collect this run's wheels, attach to the GitHub Release,
+# and upload to PyPI. Used by the Release workflows.
+
+on:
+ workflow_call:
+ inputs:
+ artifact-pattern:
+ type: string
+ required: true
+ secrets:
+ pypi-token:
+ required: false
+
+jobs:
+ publish:
+ runs-on: ubuntu-22.04
+ permissions:
+ contents: write
+ id-token: write
+ steps:
+ - name: Checkout source
+ uses: actions/checkout@v4
+
+ - name: Download all wheel artifacts
+ uses: actions/download-artifact@v4
+ with:
+ path: mooncake-wheel/dist-all
+ pattern: ${{ inputs.artifact-pattern }}
+
+ - name: Prepare wheels for release
+ run: |
+ mkdir -p mooncake-wheel/dist-release
+ find mooncake-wheel/dist-all -name "*.whl" -exec cp {} mooncake-wheel/dist-release/ \;
+ echo "Collected wheels for release:"
+ ls -la mooncake-wheel/dist-release/
+
+ - name: Upload wheels to GitHub Release
+ uses: softprops/action-gh-release@v1
+ with:
+ files: mooncake-wheel/dist-release/*.whl
+
+ - name: Publish package to PyPI
+ if: ${{ github.repository == 'kvcache-ai/Mooncake' }}
+ uses: pypa/gh-action-pypi-publish@release/v1
+ with:
+ packages-dir: mooncake-wheel/dist-release/
+ password: ${{ secrets.pypi-token }}
diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml
index 431dbd5895..345f31638f 100644
--- a/.github/workflows/ci.yml
+++ b/.github/workflows/ci.yml
@@ -182,6 +182,8 @@ jobs:
export CGO_LDFLAGS="-L$GITHUB_WORKSPACE/build/mooncake-store/src -L$GITHUB_WORKSPACE/build/mooncake-store/src/cachelib_memory_allocator -L$GITHUB_WORKSPACE/build/mooncake-transfer-engine/src -L$GITHUB_WORKSPACE/build/mooncake-transfer-engine/src/common/base -L$GITHUB_WORKSPACE/build/mooncake-common -L$GITHUB_WORKSPACE/build/mooncake-common/etcd -lmooncake_store -lcachelib_memory_allocator -ltransfer_engine -lbase -lasio -letcd_wrapper -lstdc++ -lnuma -lglog -lgflags -libverbs -lmlx5 -ljsoncpp -lzstd -lcurl -luring -lasan -lm -lgcov -lxxhash -lyaml-cpp"
# Link cudart if CUDA is available (needed for D2H staging in mooncake_store)
if [ -d /usr/local/cuda/lib64 ]; then export CGO_LDFLAGS="$CGO_LDFLAGS -L/usr/local/cuda/lib64 -lcudart"; fi
+ # KV events publisher (optional; linked when libzmq is installed)
+ if ldconfig -p 2>/dev/null | grep -q libzmq; then export CGO_LDFLAGS="$CGO_LDFLAGS -lzmq"; fi
ASAN_OPTIONS=detect_leaks=0:verify_asan_link_order=0 MC_METADATA_SERVER=http://127.0.0.1:8080/metadata go test -v ./tests/...
kill $MASTER_PID 2>/dev/null || true
shell: bash
@@ -228,7 +230,7 @@ jobs:
}
echo "=== Processing coverage data ==="
- lcov --remove coverage.info '/usr/*' '*/test/*' '*/third_party/*' --output-file coverage.filtered.info 2>&1 || true
+ lcov --remove coverage.info '/usr/*' '*/test/*' '*/third_party/*' '*/benchmarks/*' --output-file coverage.filtered.info 2>&1 || true
echo "=== Generating HTML report ==="
genhtml coverage.filtered.info --output-directory coverage_report 2>&1 || echo "genhtml failed, continuing..."
@@ -729,26 +731,6 @@ jobs:
sudo cmake --install .
shell: bash
- - name: Configure project with TENT
- run: |
- mkdir build-tent
- cd build-tent
- cmake -G Ninja .. -DUSE_TENT=ON -DUSE_HTTP=ON -DENABLE_SCCACHE=ON -DBUILD_UNIT_TESTS=ON -DBUILD_EXAMPLES=ON -DENABLE_DEBUG_SYMBOLS=OFF
- shell: bash
-
- - name: Build project with TENT
- run: |
- cd build-tent
- cmake --build .
- sudo cmake --install .
- shell: bash
-
- - name: Test (TENT)
- run: |
- cd build-tent
- ctest --test-dir mooncake-transfer-engine/tent/tests -j --output-on-failure
- shell: bash
-
- name: Build nvlink_allocator.so
run: |
mkdir -p build/mooncake-transfer-engine/nvlink-allocator
@@ -925,12 +907,15 @@ jobs:
runs-on: ubuntu-latest
outputs:
should-run-downstream: ${{ steps.dispatch-override.outputs.src || steps.filter.outputs.src }}
+ should-run-tent: ${{ steps.dispatch-override.outputs.tent || steps.filter.outputs.tent }}
steps:
# workflow_dispatch has no PR/push diff context — skip paths-filter and default to true
- name: Default to true for workflow_dispatch
id: dispatch-override
if: github.event_name == 'workflow_dispatch'
- run: echo "src=true" >> $GITHUB_OUTPUT
+ run: |
+ echo "src=true" >> $GITHUB_OUTPUT
+ echo "tent=true" >> $GITHUB_OUTPUT
- uses: actions/checkout@v4
if: github.event_name != 'workflow_dispatch'
with:
@@ -948,6 +933,12 @@ jobs:
- 'dependencies.sh'
- 'scripts/**'
- '.github/workflows/**'
+ tent:
+ - 'mooncake-transfer-engine/**'
+ - 'mooncake-common/**'
+ - 'CMakeLists.txt'
+ - 'dependencies.sh'
+ - '.github/workflows/ci.yml'
build-wheel-cu13:
needs: [spell-check, clang-format, check-paths]
@@ -985,6 +976,107 @@ jobs:
uses: ./.github/workflows/integration-test.yml
secrets: inherit
+ tent-ci:
+ needs: [spell-check, clang-format, check-paths]
+ if: >-
+ (needs.check-paths.outputs.should-run-tent == 'true' ||
+ github.event_name == 'workflow_dispatch') &&
+ (github.event_name == 'push' ||
+ github.event_name == 'workflow_dispatch' ||
+ github.event.action == 'opened' ||
+ contains(github.event.pull_request.labels.*.name, 'run-ci'))
+ runs-on: ubuntu-22.04
+ strategy:
+ fail-fast: false
+ matrix:
+ include:
+ - name: cuda-on
+ cmake_flags: '-DUSE_CUDA=ON -DCMAKE_EXE_LINKER_FLAGS=-L/usr/local/cuda/lib64/stubs'
+ need_cuda: true
+ - name: cuda-off
+ cmake_flags: '-DUSE_CUDA=OFF'
+ need_cuda: false
+ name: tent-ci (${{ matrix.name }})
+ env:
+ CI: "true"
+ SCCACHE_GHA_ENABLED: "true"
+
+ steps:
+ - uses: actions/checkout@v4
+ with:
+ persist-credentials: false
+
+ - name: Free up disk space
+ if: matrix.need_cuda
+ run: |
+ sudo rm -rf /usr/share/dotnet
+ sudo rm -rf /opt/ghc
+ sudo rm -rf /opt/hostedtoolcache/CodeQL
+ sudo rm -rf /usr/local/lib/android
+ df -h
+
+ - name: Install CUDA Toolkit
+ if: matrix.need_cuda
+ uses: Jimver/cuda-toolkit@v0.2.24
+ with:
+ cuda: '12.8.1'
+ linux-local-args: '["--toolkit"]'
+ method: 'network'
+ sub-packages: '["nvcc", "nvrtc-dev"]'
+
+ - name: Run sccache-cache
+ uses: mozilla-actions/sccache-action@v0.0.9
+
+ - name: Configure sccache
+ uses: actions/github-script@v7
+ with:
+ script: |
+ core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
+ core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
+
+ - name: Install dependencies
+ run: |
+ sudo apt update -y
+ sudo apt install -y ninja-build
+ sudo bash -x dependencies.sh -y
+ df -h
+ shell: bash
+
+ - name: Configure project with TENT
+ run: |
+ mkdir build-tent
+ cd build-tent
+ cmake -G Ninja .. -DUSE_TENT=ON -DUSE_HTTP=ON -DENABLE_SCCACHE=ON -DBUILD_UNIT_TESTS=ON -DBUILD_EXAMPLES=ON -DENABLE_DEBUG_SYMBOLS=OFF ${{ matrix.cmake_flags }}
+ shell: bash
+
+ - name: Build project with TENT
+ run: |
+ if [ "${{ matrix.need_cuda }}" = "true" ]; then
+ export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH
+ export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
+ fi
+ cd build-tent
+ cmake --build .
+ sudo cmake --install .
+ shell: bash
+
+ # Only run tests on the cuda-off leg. GitHub runners have no real GPU;
+ # with USE_CUDA=ON tent's cuda_probe hits the CUDA stub library at
+ # runtime and drives some dispatch paths past the fake objects the
+ # unit tests rely on, causing false failures. cuda-on still validates
+ # that every #ifdef USE_CUDA branch compiles.
+ - name: Test (TENT)
+ if: '!matrix.need_cuda'
+ run: |
+ cd build-tent
+ ctest --test-dir mooncake-transfer-engine/tent/tests -j --output-on-failure
+ shell: bash
+
+ - name: Run sccache stat for check
+ if: ${{ env.SCCACHE_PATH != '' }}
+ shell: bash
+ run: ${SCCACHE_PATH} --show-stats
+
ci-gate:
name: CI Gate
if: always()
@@ -1000,6 +1092,7 @@ jobs:
- test-wheel-ubuntu
- build-wheel-cu13
- build-wheel-efa
+ - tent-ci
- ascend-test
- integration-test
runs-on: ubuntu-latest
diff --git a/.github/workflows/integration-test.yml b/.github/workflows/integration-test.yml
index 0d976f5624..4988dc3179 100644
--- a/.github/workflows/integration-test.yml
+++ b/.github/workflows/integration-test.yml
@@ -37,7 +37,7 @@ jobs:
if curl -L -fs -o artifact.json -H "Accept: application/vnd.github+json" -H "X-GitHub-Api-Version: 2022-11-28" https://api.github.com/repos/${{ github.repository }}/actions/artifacts?per_page=100; then
artifact_id=""
if jq empty artifact.json >/dev/null 2>&1; then
- artifact_id=$(jq -r ".artifacts[] | select(.name | contains(\"py312\") ) | select(.name | contains(\"mooncake\") ) | select(.name | contains(\"cu130\") | not) | select(.workflow_run.head_sha == \"$SHA\" ) | .id" artifact.json | head -n 1)
+ artifact_id=$(jq -r ".artifacts[] | select(.name | contains(\"py312\") ) | select(.name | contains(\"mooncake\") ) | select(.name | contains(\"cu130\") ) | select(.workflow_run.head_sha == \"$SHA\" ) | .id" artifact.json | head -n 1)
else
echo "Failed to download artifact list. Retrying..."
fi
diff --git a/.github/workflows/pre-release.yaml b/.github/workflows/pre-release.yaml
index 7561c21b97..279d48876a 100644
--- a/.github/workflows/pre-release.yaml
+++ b/.github/workflows/pre-release.yaml
@@ -1,7 +1,8 @@
name: Pre-Release
-# Dry-run of the release pipelines: build wheels like Release / Release Non-CUDA /
-# Release CUDA 13, validate artifacts, but do not create a GitHub Release or publish to PyPI.
+# Dry run of the release pipelines: build wheels through the same _build-wheel.yaml
+# the Release / Release Non-CUDA / Release CUDA 13 workflows use, validate the
+# artifacts, but do not create a GitHub Release or publish to PyPI.
#
# Trigger by pushing a pre-release tag, for example:
# git tag v1.0.0-rc1 && git push origin v1.0.0-rc1
@@ -13,484 +14,75 @@ on:
- 'v*-beta*'
- 'v*-pre*'
-env:
- SCCACHE_GHA_ENABLED: "true"
-
jobs:
build-cuda:
- name: Build (CUDA 12)
- runs-on: ubuntu-22.04
- permissions:
- contents: read
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "1"
- TORCH_CUDA_ARCH_LIST: "8.0;9.0"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set version from tag
- run: echo "VERSION=${GITHUB_REF_NAME#v}" >> $GITHUB_ENV
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
- sudo rm -rf /usr/local/lib/android
- df -h
-
- - name: Install CUDA Toolkit
- uses: Jimver/cuda-toolkit@v0.2.24
- with:
- cuda: '12.8.1'
- linux-local-args: '["--toolkit"]'
- method: 'network'
- sub-packages: '["nvcc", "nvrtc-dev"]'
- non-cuda-sub-packages: '["libcusparse-dev", "libcublas-dev", "libcusolver-dev"]'
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake .. -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON -DWITH_EP=ON -DEP_TORCH_VERSIONS="2.11.0;2.12.0;2.12.1" -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- cd build
- make -j
- sudo -E make install
- shell: bash
-
- - name: Build nvlink_allocator.so
- run: |
- export PATH=/usr/local/nvidia/bin:/usr/local/nvidia/lib64:$PATH
- export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- mkdir -p build/mooncake-transfer-engine/nvlink-allocator
- cd mooncake-transfer-engine/nvlink-allocator
- bash build.sh ../../build/mooncake-transfer-engine/nvlink-allocator/
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: pre-release-cuda-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda12.8
+ cuda: container
+ build-with-ep: '1'
+ torch-cuda-arch-list: '8.0;9.0'
+ ep-torch-versions: '2.11.0;2.12.0;2.12.1'
+ build-nvlink-allocator: true
+ cmake-args: >-
+ -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON
+ -DWITH_EP=ON -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: pre-release-cuda
build-non-cuda:
- name: Build (Non-CUDA)
- runs-on: ubuntu-22.04
- permissions:
- contents: read
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "0"
- NON_CUDA_BUILD: "1"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set version from tag
- run: echo "VERSION=${GITHUB_REF_NAME#v}" >> $GITHUB_ENV
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake .. -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=OFF -DWITH_EP=OFF -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- cd build
- make -j
- sudo -E make install
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: pre-release-non-cuda-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda12.8
+ cuda: container
+ build-with-ep: '0'
+ variant-flag: NON_CUDA_BUILD
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=OFF -DWITH_EP=OFF
+ -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: pre-release-non-cuda
build-cuda13:
- name: Build (CUDA 13)
- runs-on: ubuntu-22.04
- permissions:
- contents: read
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "1"
- CU13_BUILD: "1"
- TORCH_CUDA_ARCH_LIST: "8.0;9.0"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set version from tag
- run: echo "VERSION=${GITHUB_REF_NAME#v}" >> $GITHUB_ENV
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
- sudo rm -rf /usr/local/lib/android
- df -h
-
- - name: Install CUDA Toolkit 13
- uses: Jimver/cuda-toolkit@v0.2.29
- with:
- cuda: '13.0.2'
- linux-local-args: '["--toolkit"]'
- method: 'network'
- sub-packages: '["nvcc", "nvrtc-dev"]'
- non-cuda-sub-packages: '["libcusparse-dev", "libcublas-dev", "libcusolver-dev"]'
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake .. -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON -DWITH_EP=ON -DEP_TORCH_VERSIONS="2.11.0;2.12.0;2.12.1" -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- cd build
- make -j
- sudo make install
- shell: bash
-
- - name: Build nvlink_allocator.so
- run: |
- export PATH=/usr/local/nvidia/bin:/usr/local/nvidia/lib64:$PATH
- export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- mkdir -p build/mooncake-transfer-engine/nvlink-allocator
- cd mooncake-transfer-engine/nvlink-allocator
- bash build.sh ../../build/mooncake-transfer-engine/nvlink-allocator/
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: pre-release-cuda13-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda13.0
+ cuda: container
+ build-with-ep: '1'
+ variant-flag: CU13_BUILD
+ torch-cuda-arch-list: '8.0;9.0'
+ ep-torch-versions: '2.11.0;2.12.0;2.12.1'
+ build-nvlink-allocator: true
+ cmake-args: >-
+ -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON
+ -DWITH_EP=ON -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: pre-release-cuda13
build-cuda-arm64:
- name: Build (CUDA 12, arm64)
- runs-on: ubuntu-22.04-arm
- permissions:
- contents: read
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- TORCH_CUDA_ARCH_LIST: "9.0"
- CUDA_HOME: "/usr/local/cuda"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set version from tag
- run: echo "VERSION=${GITHUB_REF_NAME#v}" >> $GITHUB_ENV
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Install CUDA Toolkit 12.8 (arm64 SBSA)
- run: |
- wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/sbsa/cuda-keyring_1.1-1_all.deb
- sudo dpkg -i cuda-keyring_1.1-1_all.deb
- sudo apt-get update
- sudo apt-get install -y cuda-toolkit-12-8
- echo "/usr/local/cuda/bin" >> $GITHUB_PATH
- /usr/local/cuda/bin/nvcc --version
- shell: bash
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake -G Ninja .. -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export CUDA_HOME=/usr/local/cuda
- for dir in /usr/local/cuda/lib64/stubs /usr/local/cuda/targets/*/lib/stubs; do
- if [ -d "$dir" ]; then
- export LIBRARY_PATH="$dir:${LIBRARY_PATH:-}"
- fi
- done
- cd build
- cmake --build .
- sudo cmake --install .
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_arm64
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export CUDA_HOME=/usr/local/cuda
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_arm64.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
- shell: bash
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: pre-release-cuda-arm64-py${{ steps.generate_tag_arm64.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_arm64.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04-arm
+ cuda: sbsa-12.8
+ cmake-generator: Ninja
+ torch-cuda-arch-list: '9.0'
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF
+ -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: pre-release-cuda-arm64
build-cuda13-arm64:
- name: Build (CUDA 13, arm64)
- runs-on: ubuntu-22.04-arm
- permissions:
- contents: read
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- CU13_BUILD: "1"
- TORCH_CUDA_ARCH_LIST: "9.0"
- CUDA_HOME: "/usr/local/cuda"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set version from tag
- run: echo "VERSION=${GITHUB_REF_NAME#v}" >> $GITHUB_ENV
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Install CUDA Toolkit 13.0 (arm64 SBSA)
- run: |
- wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/sbsa/cuda-keyring_1.1-1_all.deb
- sudo dpkg -i cuda-keyring_1.1-1_all.deb
- sudo apt-get update
- sudo apt-get install -y cuda-toolkit-13-0
- echo "/usr/local/cuda/bin" >> $GITHUB_PATH
- /usr/local/cuda/bin/nvcc --version
- shell: bash
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake -G Ninja .. -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export CUDA_HOME=/usr/local/cuda
- for dir in /usr/local/cuda/lib64/stubs /usr/local/cuda/targets/*/lib/stubs; do
- if [ -d "$dir" ]; then
- export LIBRARY_PATH="$dir:${LIBRARY_PATH:-}"
- fi
- done
- cd build
- cmake --build .
- sudo cmake --install .
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_arm64
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export CUDA_HOME=/usr/local/cuda
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_arm64.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
- shell: bash
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: pre-release-cuda13-arm64-py${{ steps.generate_tag_arm64.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_arm64.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04-arm
+ cuda: sbsa-13.0
+ cmake-generator: Ninja
+ variant-flag: CU13_BUILD
+ torch-cuda-arch-list: '9.0'
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF
+ -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: pre-release-cuda13-arm64
validate-release:
name: Validate release artifacts
diff --git a/.github/workflows/release-cuda13.yaml b/.github/workflows/release-cuda13.yaml
index 80d2f61192..929d9f9fa6 100644
--- a/.github/workflows/release-cuda13.yaml
+++ b/.github/workflows/release-cuda13.yaml
@@ -5,225 +5,45 @@ on:
tags:
- 'v*'
-env:
- SCCACHE_GHA_ENABLED: "true"
jobs:
build:
- runs-on: ubuntu-22.04
- container: pytorch/manylinux2_28-builder:cuda13.0
- permissions:
- contents: write
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "1"
- CU13_BUILD: "1"
- TORCH_CUDA_ARCH_LIST: "8.0;9.0"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Mark workspace safe for git (container runs as root)
- run: git config --global --add safe.directory '*'
-
- - name: Select Python ${{ matrix.python-version }} from manylinux image
- run: |
- PYV_NODOT=$(echo "${{ matrix.python-version }}" | tr -d '.')
- PYBIN="/opt/python/cp${PYV_NODOT}-cp${PYV_NODOT}/bin"
- echo "$PYBIN" >> "$GITHUB_PATH"
- "$PYBIN/pip" install --quiet "cmake<4" setuptools wheel
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- bash -x dependencies.sh -y
- echo "/usr/local/go/bin" >> "$GITHUB_PATH"
- mkdir build
- cd build
- cmake .. -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON -DWITH_EP=ON -DEP_TORCH_VERSIONS="2.11.0;2.12.0;2.12.1" -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release -DPython3_EXECUTABLE="$(which python3)"
- shell: bash
-
- - name: Build project
- run: |
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- cd build
- make -j
- make install
- shell: bash
-
- - name: Build nvlink_allocator.so
- run: |
- export PATH=/usr/local/nvidia/bin:/usr/local/nvidia/lib64:$PATH
- export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- mkdir -p build/mooncake-transfer-engine/nvlink-allocator
- cd mooncake-transfer-engine/nvlink-allocator
- bash build.sh ../../build/mooncake-transfer-engine/nvlink-allocator/
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- # Set LD_LIBRARY_PATH for wheel building
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: mooncake-wheel-cuda13-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda13.0
+ cuda: container
+ build-with-ep: '1'
+ variant-flag: CU13_BUILD
+ torch-cuda-arch-list: '8.0;9.0'
+ ep-torch-versions: '2.11.0;2.12.0;2.12.1'
+ build-nvlink-allocator: true
+ cmake-args: >-
+ -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON
+ -DWITH_EP=ON -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: mooncake-wheel-cuda13
build-arm64:
if: ${{ !contains(github.ref_name, '-') }}
- runs-on: ubuntu-22.04-arm
- permissions:
- contents: write
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- CU13_BUILD: "1"
- TORCH_CUDA_ARCH_LIST: "9.0"
- CUDA_HOME: "/usr/local/cuda"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Install CUDA Toolkit 13.0 (arm64 SBSA)
- run: |
- wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/sbsa/cuda-keyring_1.1-1_all.deb
- sudo dpkg -i cuda-keyring_1.1-1_all.deb
- sudo apt-get update
- sudo apt-get install -y cuda-toolkit-13-0
- echo "/usr/local/cuda/bin" >> $GITHUB_PATH
- /usr/local/cuda/bin/nvcc --version
- shell: bash
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake -G Ninja .. -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export CUDA_HOME=/usr/local/cuda
- for dir in /usr/local/cuda/lib64/stubs /usr/local/cuda/targets/*/lib/stubs; do
- if [ -d "$dir" ]; then
- export LIBRARY_PATH="$dir:${LIBRARY_PATH:-}"
- fi
- done
- cd build
- cmake --build .
- sudo cmake --install .
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export CUDA_HOME=/usr/local/cuda
- export LD_LIBRARY_PATH="${LD_LIBRARY_PATH:-}:/usr/local/lib"
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- shell: bash
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: mooncake-wheel-cuda13-arm64-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04-arm
+ cuda: sbsa-13.0
+ cmake-generator: Ninja
+ variant-flag: CU13_BUILD
+ torch-cuda-arch-list: '9.0'
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF
+ -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: mooncake-wheel-cuda13-arm64
publish-release:
if: ${{ !contains(github.ref_name, '-') }}
needs: [build, build-arm64]
- runs-on: ubuntu-22.04
permissions:
contents: write
id-token: write
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Download all wheel artifacts
- uses: actions/download-artifact@v4
- with:
- path: mooncake-wheel/dist-all
- pattern: mooncake-wheel-cuda13*
-
- - name: Prepare wheels for release
- run: |
- # Move all wheels to a single directory
- mkdir -p mooncake-wheel/dist-release
- find mooncake-wheel/dist-all -name "*.whl" -exec cp {} mooncake-wheel/dist-release/ \;
- ls -la mooncake-wheel/dist-release/
- # List all collected wheels
- echo "Collected wheels for release:"
- ls -la mooncake-wheel/dist-release/
-
- - name: Upload wheels to GitHub Release
- uses: softprops/action-gh-release@v1
- with:
- files: mooncake-wheel/dist-release/*.whl
-
- - name: Publish package to PyPI
- if: github.repository == 'kvcache-ai/Mooncake'
- uses: pypa/gh-action-pypi-publish@release/v1
- with:
- packages-dir: mooncake-wheel/dist-release/
- password: ${{ secrets.PYPI_CU13_API_TOKEN }}
+ uses: ./.github/workflows/_publish-wheel.yaml
+ with:
+ artifact-pattern: 'mooncake-wheel-cuda13*'
+ secrets:
+ pypi-token: ${{ secrets.PYPI_CU13_API_TOKEN }}
diff --git a/.github/workflows/release-non-cuda.yaml b/.github/workflows/release-non-cuda.yaml
index 1852717366..a3838b7937 100644
--- a/.github/workflows/release-non-cuda.yaml
+++ b/.github/workflows/release-non-cuda.yaml
@@ -5,120 +5,30 @@ on:
tags:
- 'v*'
-env:
- SCCACHE_GHA_ENABLED: "true"
jobs:
+ # manylinux2_28 for the toolchain only (USE_CUDA=OFF); keeps the glibc floor
+ # aligned with the CUDA wheels.
build:
- runs-on: ubuntu-22.04
- permissions:
- contents: write
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "0"
- NON_CUDA_BUILD: "1"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake .. -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=OFF -DWITH_EP=OFF -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- cd build
- make -j
- sudo make install
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- # Set LD_LIBRARY_PATH for wheel building
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: mooncake-wheel-non-cuda-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda12.8
+ cuda: container
+ build-with-ep: '0'
+ variant-flag: NON_CUDA_BUILD
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=OFF -DWITH_EP=OFF
+ -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: mooncake-wheel-non-cuda
publish-release:
if: ${{ !contains(github.ref_name, '-') }}
needs: build
- runs-on: ubuntu-22.04
permissions:
contents: write
id-token: write
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Download all wheel artifacts
- uses: actions/download-artifact@v4
- with:
- path: mooncake-wheel/dist-all
- pattern: mooncake-wheel-non-cuda-py*
-
- - name: Prepare wheels for release
- run: |
- # Move all wheels to a single directory
- mkdir -p mooncake-wheel/dist-release
- find mooncake-wheel/dist-all -name "*.whl" -exec cp {} mooncake-wheel/dist-release/ \;
- ls -la mooncake-wheel/dist-release/
- # List all collected wheels
- echo "Collected wheels for release:"
- ls -la mooncake-wheel/dist-release/
-
- - name: Upload wheels to GitHub Release
- uses: softprops/action-gh-release@v1
- with:
- files: mooncake-wheel/dist-release/*.whl
-
- - name: Publish package to PyPI
- if: github.repository == 'kvcache-ai/Mooncake'
- uses: pypa/gh-action-pypi-publish@release/v1
- with:
- packages-dir: mooncake-wheel/dist-release/
- password: ${{ secrets.PYPI_API_TOKEN }}
+ uses: ./.github/workflows/_publish-wheel.yaml
+ with:
+ artifact-pattern: 'mooncake-wheel-non-cuda*'
+ secrets:
+ pypi-token: ${{ secrets.PYPI_API_TOKEN }}
diff --git a/.github/workflows/release.yaml b/.github/workflows/release.yaml
index d0da9e5552..007e4a5c72 100644
--- a/.github/workflows/release.yaml
+++ b/.github/workflows/release.yaml
@@ -5,223 +5,44 @@ on:
tags:
- 'v*'
-env:
- SCCACHE_GHA_ENABLED: "true"
jobs:
+ # Skip semver pre-release tags (e.g. v1.0.0-rc1); those are handled by pre-release.yaml.
build:
- # Skip semver pre-release tags (e.g. v1.0.0-rc1); those are handled by pre-release.yaml.
if: ${{ !contains(github.ref_name, '-') }}
- runs-on: ubuntu-22.04
- container: pytorch/manylinux2_28-builder:cuda12.8
- permissions:
- contents: write
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- BUILD_WITH_EP: "1"
- TORCH_CUDA_ARCH_LIST: "8.0;9.0"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Mark workspace safe for git (container runs as root)
- run: git config --global --add safe.directory '*'
-
- - name: Select Python ${{ matrix.python-version }} from manylinux image
- run: |
- PYV_NODOT=$(echo "${{ matrix.python-version }}" | tr -d '.')
- PYBIN="/opt/python/cp${PYV_NODOT}-cp${PYV_NODOT}/bin"
- echo "$PYBIN" >> "$GITHUB_PATH"
- "$PYBIN/pip" install --quiet "cmake<4" setuptools wheel
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- bash -x dependencies.sh -y
- echo "/usr/local/go/bin" >> "$GITHUB_PATH"
- mkdir build
- cd build
- cmake .. -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON -DWITH_EP=ON -DEP_TORCH_VERSIONS="2.11.0;2.12.0;2.12.1" -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release -DPython3_EXECUTABLE="$(which python3)"
- shell: bash
-
- - name: Build project
- run: |
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- cd build
- make -j
- make install
- shell: bash
-
- - name: Build nvlink_allocator.so
- run: |
- export PATH=/usr/local/nvidia/bin:/usr/local/nvidia/lib64:$PATH
- export LD_LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LD_LIBRARY_PATH
- export LIBRARY_PATH=/usr/local/cuda/lib64/stubs:$LIBRARY_PATH
- mkdir -p build/mooncake-transfer-engine/nvlink-allocator
- cd mooncake-transfer-engine/nvlink-allocator
- bash build.sh ../../build/mooncake-transfer-engine/nvlink-allocator/
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- # Set LD_LIBRARY_PATH for wheel building
- export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- env:
- VERSION: ${{ env.VERSION }}
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: mooncake-wheel-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04
+ container: pytorch/manylinux2_28-builder:cuda12.8
+ cuda: container
+ build-with-ep: '1'
+ torch-cuda-arch-list: '8.0;9.0'
+ ep-torch-versions: '2.11.0;2.12.0;2.12.1'
+ build-nvlink-allocator: true
+ cmake-args: >-
+ -DBUILD_UNIT_TESTS=OFF -DUSE_HTTP=ON -DUSE_ETCD=ON -DUSE_CUDA=ON
+ -DWITH_EP=ON -DSTORE_USE_ETCD=ON -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: mooncake-wheel
build-arm64:
if: ${{ !contains(github.ref_name, '-') }}
- runs-on: ubuntu-22.04-arm
- permissions:
- contents: write
- strategy:
- matrix:
- python-version: ['3.10', '3.11', '3.12', '3.13']
- env:
- TORCH_CUDA_ARCH_LIST: "9.0"
- CUDA_HOME: "/usr/local/cuda"
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Set up Python ${{ matrix.python-version }}
- uses: actions/setup-python@v5
- with:
- python-version: ${{ matrix.python-version }}
-
- - name: Free up disk space
- run: |
- sudo rm -rf /usr/share/dotnet
- sudo rm -rf /opt/ghc
- sudo rm -rf /opt/hostedtoolcache/CodeQL
-
- - name: Install CUDA Toolkit 12.8 (arm64 SBSA)
- run: |
- wget https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2204/sbsa/cuda-keyring_1.1-1_all.deb
- sudo dpkg -i cuda-keyring_1.1-1_all.deb
- sudo apt-get update
- sudo apt-get install -y cuda-toolkit-12-8
- echo "/usr/local/cuda/bin" >> $GITHUB_PATH
- /usr/local/cuda/bin/nvcc --version
- shell: bash
-
- - name: Run sccache-cache
- uses: mozilla-actions/sccache-action@v0.0.9
-
- - name: Configure sccache
- uses: actions/github-script@v7
- with:
- script: |
- core.exportVariable('ACTIONS_RESULTS_URL', process.env.ACTIONS_RESULTS_URL || '');
- core.exportVariable('ACTIONS_RUNTIME_TOKEN', process.env.ACTIONS_RUNTIME_TOKEN || '');
-
- - name: Configure project
- run: |
- sudo apt update -y
- sudo bash -x dependencies.sh -y
- mkdir build
- cd build
- cmake -G Ninja .. -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
- shell: bash
-
- - name: Build project
- run: |
- export CUDA_HOME=/usr/local/cuda
- for dir in /usr/local/cuda/lib64/stubs /usr/local/cuda/targets/*/lib/stubs; do
- if [ -d "$dir" ]; then
- export LIBRARY_PATH="$dir:${LIBRARY_PATH:-}"
- fi
- done
- cd build
- cmake --build .
- sudo cmake --install .
- shell: bash
-
- - name: Run sccache stat for check
- if: ${{ env.SCCACHE_PATH != '' }}
- shell: bash
- run: ${SCCACHE_PATH} --show-stats
-
- - name: Generate Python version tag
- id: generate_tag_release
- run: |
- echo "python_version_tag=$(echo ${{ matrix.python-version }} | tr -d '.')" >> $GITHUB_OUTPUT
- shell: bash
-
- - name: Build Python wheel
- run: |
- export CUDA_HOME=/usr/local/cuda
- export LD_LIBRARY_PATH="${LD_LIBRARY_PATH:-}:/usr/local/lib"
- PYTHON_VERSION=${{ matrix.python-version }} OUTPUT_DIR=dist-py${{ steps.generate_tag_release.outputs.python_version_tag }} ./scripts/build_wheel.sh
- shell: bash
-
- - name: Upload Python wheel artifact
- uses: actions/upload-artifact@v4
- with:
- name: mooncake-wheel-arm64-py${{ steps.generate_tag_release.outputs.python_version_tag }}
- path: mooncake-wheel/dist-py${{ steps.generate_tag_release.outputs.python_version_tag }}/*.whl
+ uses: ./.github/workflows/_build-wheel.yaml
+ with:
+ runner: ubuntu-22.04-arm
+ cuda: sbsa-12.8
+ cmake-generator: Ninja
+ torch-cuda-arch-list: '9.0'
+ cmake-args: >-
+ -DUSE_HTTP=ON -DUSE_CUDA=ON -DUSE_MNNVL=ON -DWITH_EP=OFF
+ -DWITH_STORE_RUST=OFF -DENABLE_SCCACHE=ON -DCMAKE_BUILD_TYPE=Release
+ artifact-prefix: mooncake-wheel-arm64
publish-release:
needs: [build, build-arm64]
- runs-on: ubuntu-22.04
permissions:
contents: write
id-token: write
- steps:
- - name: Checkout source
- uses: actions/checkout@v4
-
- - name: Download all wheel artifacts
- uses: actions/download-artifact@v4
- with:
- path: mooncake-wheel/dist-all
-
- - name: Prepare wheels for release
- run: |
- # Move all wheels to a single directory
- mkdir -p mooncake-wheel/dist-release
- find mooncake-wheel/dist-all -name "*.whl" -exec cp {} mooncake-wheel/dist-release/ \;
- ls -la mooncake-wheel/dist-release/
- # List all collected wheels
- echo "Collected wheels for release:"
- ls -la mooncake-wheel/dist-release/
-
- - name: Upload wheels to GitHub Release
- uses: softprops/action-gh-release@v1
- with:
- files: mooncake-wheel/dist-release/*.whl
-
- - name: Publish package to PyPI
- if: github.repository == 'kvcache-ai/Mooncake'
- uses: pypa/gh-action-pypi-publish@release/v1
- with:
- packages-dir: mooncake-wheel/dist-release/
- password: ${{ secrets.PYPI_API_TOKEN }}
+ uses: ./.github/workflows/_publish-wheel.yaml
+ with:
+ artifact-pattern: 'mooncake-wheel*'
+ secrets:
+ pypi-token: ${{ secrets.PYPI_API_TOKEN }}
diff --git a/.gitignore b/.gitignore
index 4a3ec467a5..35a253a732 100644
--- a/.gitignore
+++ b/.gitignore
@@ -198,9 +198,6 @@ mooncake-wheel/mooncake/allocator_ascend_npu.py
mooncake-wheel/mooncake/mooncake_master
mooncake-wheel/mooncake/transfer_engine_bench
-# Claude Code Memory
-CLAUDE.md
-
# CodeQL
_codeql_detected_source_root
diff --git a/.pre-commit-config.yaml b/.pre-commit-config.yaml
index 3fefbf6af2..d6df05b60d 100644
--- a/.pre-commit-config.yaml
+++ b/.pre-commit-config.yaml
@@ -47,7 +47,7 @@ repos:
hooks:
- id: codespell
exclude: '^(extern/|FAST25-release/)'
- args: ['--ignore-words-list=te,mooncake,KVCache,cann']
+ args: ['--ignore-words-list=te,mooncake,KVCache,cann,hsa']
- repo: https://github.com/pre-commit/mirrors-clang-format
rev: v20.1.8
diff --git a/.typos.toml b/.typos.toml
index 320972c8fa..4843e506f2 100644
--- a/.typos.toml
+++ b/.typos.toml
@@ -1,5 +1,5 @@
[default]
-extend-ignore-words = ["CANN", "ASO", "fre", "wqs", "hsa"]
+extend-ignore-words = ["CANN", "ASO", "fre", "wqs", "hsa", "ue"]
[default.extend-words]
CANN = "CANN"
@@ -9,9 +9,13 @@ wqs = "wqs"
# AMD HSA runtime symbol prefix (hsa_*, hsaRes, hsaErr, etc.) — used by the
# ROCm dmabuf MR registration path.
hsa = "hsa"
+Optin = "Optin"
HPE = "HPE"
[files]
extend-exclude = [
"mooncake-transfer-engine/tent/include/tent/thirdparty/nlohmann/json.h",
+ # DeepEP-derived elastic kernel headers keep upstream identifiers such as
+ # `ue8m0x4`; exclude the imported header block from spelling checks.
+ "mooncake-ep/include/elastic/*",
]
diff --git a/AGENTS.md b/AGENTS.md
new file mode 100644
index 0000000000..f7332c2d0a
--- /dev/null
+++ b/AGENTS.md
@@ -0,0 +1,25 @@
+# AGENTS.md
+
+## `docs/` Directory Changes
+
+- Before modifying files under `docs/`, read `docs/AGENTS.md`.
+
+## Pull Request Guidelines
+
+- Follow `CONTRIBUTING.md` for PR title prefixes, RFC expectations, and
+ contribution workflow.
+- Before opening a PR for nontrivial work, check whether an existing issue or
+ open PR already covers the same change. If the work overlaps, explain the
+ difference instead of duplicating it.
+- Do not open low-value busywork PRs for isolated typo, style, or mechanical
+ changes unless they are part of a substantive requested change.
+- Use `.github/pull_request_template.md` when preparing a PR, and fill in the
+ relevant sections for description, module, type of change, testing,
+ checklist, and AI assistance disclosure.
+- For AI-assisted changes, make sure the human submitter has reviewed every
+ changed line and can defend the change end-to-end.
+- Run pre-commit locally on the files touched by the change before handoff when
+ the toolchain is available. If broader hooks or `pre-commit run --all-files`
+ rewrite unrelated files, do not include those unrelated edits in the PR.
+- Keep PRs lean: review `git diff` before staging, and include only changes
+ required for the requested task.
diff --git a/CLAUDE.md b/CLAUDE.md
new file mode 100644
index 0000000000..43c994c2d3
--- /dev/null
+++ b/CLAUDE.md
@@ -0,0 +1 @@
+@AGENTS.md
diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md
index 5ce88ac0f3..4116d4bf02 100644
--- a/CONTRIBUTING.md
+++ b/CONTRIBUTING.md
@@ -16,7 +16,8 @@ Thank you for your interest in contributing to Mooncake! Our community warmly we
### PR Title and Classification
-Use a prefixed PR title to indicate the type of changes. Please use one of the following:
+Use a prefixed PR title to indicate the type or module affected by the changes.
+Prefer one of the following documented prefixes:
- ``[Bugfix]`` for bug fixes.
- ``[CI/Build]`` for build or continuous integration improvements.
@@ -28,6 +29,11 @@ Use a prefixed PR title to indicate the type of changes. Please use one of the f
- ``[Misc]`` for PRs that do not fit the above categories. Please use this
sparingly.
+The project history also contains common aliases and module prefixes. Use these
+when they better match the change scope: ``[Bug fix]``, ``[Build]``, ``[CI]``,
+``[Docs]``, ``[EP]``, ``[Feature]``, ``[MUSA]``, ``[PG]``, ``[TE]``,
+``[TENT]``, and ``[Wheel]``.
+
### RFC Discussion
For major architectural changes (>500 LOC excluding tests), we would expect a GitHub issue (RFC) discussing the technical design and justification.
diff --git a/README.md b/README.md
index b08dbfee34..d52af0e4fa 100644
--- a/README.md
+++ b/README.md
@@ -32,10 +32,11 @@ Under real workloads, Mooncake’s innovative architecture enables Kimi to handl
🔄 Updates
+- **Jul 2, 2026**: [DSpark](https://x.com/mgoin_/status/2072785822231728363) scales fully online training on a GB300 NVL72 system with Speculators and Mooncake: 9 vLLM nodes serve the GLM 5.2 FP8 verifier through Mooncake RDMA Store to 6 FSDP training nodes (DP=24), achieving 125k prefill tokens/s and 1.5 steps/s.
- **May 7, 2026**: 🚀 [vLLM officially features Mooncake Store](https://vllm.ai/blog/mooncake-store) — a deep dive into how Mooncake's distributed KVCache engine supercharges vLLM inference with high-throughput, memory-efficient, cross-instance KV cache sharing!
- **Apr 29, 2026**: SGLang introduces [RDMA-based P2P weight transfer for large-scale distributed RL](https://lmsys.org/blog/2026-04-29-p2p-update/) using Mooncake TransferEngine, achieving 7x faster weight updates for the 1T-parameter Kimi-K2 model (53s → 7.2s) with zero-copy RDMA transfer across thousands of GPUs.
- **Mar 19, 2026**: [TorchSpec: Speculative Decoding Training at Scale](https://pytorch.org/blog/torchspec-speculative-decoding-training-at-scale) is [open sourced](https://github.com/torchspec-project/TorchSpec), using Mooncake to decouple inference and training via efficient hidden states management.
-- **Mar 5, 2026**: [LightX2V](https://github.com/ModelTC/LightX2V/pull/893) now supports disaggregated deployment based on Mooncake, enabling encoder/transformer service decoupling with Mooncake Transfer Engine for high-performance cross-device and cross-machine data transfer.
+- **Mar 5, 2026**: [LightX2V](https://github.com/ModelTC/LightX2V/pull/893) now supports disaggregated deployment based on Mooncake, enabling encoder/transformer service decoupling with Mooncake Transfer Engine for high-performance cross-device and cross-machine data transfer. Details in [blog](https://light-ai.top/LightX2V-BLOG/posts/Disaggregation/).
- **Feb 25, 2026**: [SGLang](https://github.com/sgl-project/sglang) merged [Encoder Global Cache Manager](https://github.com/sgl-project/sglang/pull/16137), introducing a Mooncake-powered global multimodal embedding cache that enables cross-instance sharing of ViT embeddings to avoid redundant GPU computation.
diff --git a/benchmarks/storage_benchmark/storage_benchmark.py b/benchmarks/storage_benchmark/storage_benchmark.py
deleted file mode 100644
index 689bc98e99..0000000000
--- a/benchmarks/storage_benchmark/storage_benchmark.py
+++ /dev/null
@@ -1,956 +0,0 @@
-#!/usr/bin/env python3
-# SPDX-License-Identifier: Apache-2.0
-
-"""
-Mooncake KVCache Storage Benchmark Tool
-"""
-
-import argparse
-import json
-import time
-import os
-import statistics
-import random
-import errno
-from pathlib import Path
-from typing import Dict, List, Optional
-from dataclasses import dataclass
-
-# ============================================================================
-# Constants
-# ============================================================================
-
-BLOCK_SIZE_TOKENS = 512 # Number of tokens per block
-DEFAULT_BYTES_PER_TOKEN = 2048 # 7B model FP16 (2KB per token)
-BLOCK_SIZE_BYTES = BLOCK_SIZE_TOKENS * DEFAULT_BYTES_PER_TOKEN # 1MB per block
-MIN_LATENCY_MS = 0.001 # Minimum latency in milliseconds (1 microsecond)
-
-# Model KVCache sizes (bytes per token, based on LMCache calculator)
-# Source: https://lmcache.ai/kv_cache_calculator.html
-MODEL_BYTES_PER_TOKEN = {
- "llama-3.1-405b": 327680,
- "qwen3-32b": 81920,
- "deepseek-v3": 1748992,
- "glm-4.6": 157013,
- "default": DEFAULT_BYTES_PER_TOKEN,
-}
-
-# ============================================================================
-# Data Structures
-# ============================================================================
-
-@dataclass
-class KVCacheRequest:
- """KVCache request
-
- Attributes:
- timestamp: Request timestamp in milliseconds
- hash_ids: List of block IDs (each ID corresponds to a 512-token block)
- input_length: Input token count
- output_length: Output token count
- """
- timestamp: float
- hash_ids: List[int]
- input_length: int
- output_length: int
-
-# ============================================================================
-# Storage Layer: Offset Allocator
-# ============================================================================
-
-class OffsetAllocatorStorage:
- """High-performance block storage based on Offset Allocator
-
- Architecture:
- -----------
- 1. Single large file stores all blocks (avoids file explosion)
- 2. Uses offset to manage file space (similar to Mooncake's OffsetAllocator)
- 3. hash_id -> offset mapping stored in memory (fast lookup)
-
- Block Organization:
- -----------
- Each block corresponds to 512 tokens, fixed size 1MB:
- - hash_id[0] -> block_0 (tokens [0...511]) -> offset 0
- - hash_id[1] -> block_1 (tokens [512...1023]) -> offset 1
- - hash_id[i] -> block_i (tokens [i*512...(i+1)*512-1]) -> offset i
-
- Performance Advantages:
- -----------
- - Only one file, no file explosion
- - Offset reuse, reduces memory allocation
- - pread/pwrite, thread-safe, no seek needed
- - Keep fd open, reduces open/close overhead
- - Metadata in memory, O(1) lookup
-
- Attributes:
- storage_dir: Storage directory path
- block_size_bytes: Block size in bytes
- max_blocks: Maximum number of blocks
- hash_id_to_offset: hash_id -> offset mapping
- free_offsets: List of reusable offsets
- next_offset: Next allocatable offset
- """
-
- def __init__(self, storage_dir: str, bytes_per_token: int = DEFAULT_BYTES_PER_TOKEN,
- max_blocks: int = 100000, block_size_tokens: int = 512,
- fsync_mode: str = 'batch', fsync_batch_size: int = 100):
- """Initialize Offset Allocator storage
-
- Args:
- storage_dir: Storage directory path
- bytes_per_token: Bytes per token
- max_blocks: Maximum number of blocks (determines file size)
- block_size_tokens: Number of tokens per block
- fsync_mode: When to fsync ('batch', 'always', 'end', 'none')
- fsync_batch_size: Number of writes between fsync in batch mode
- """
- self.storage_dir = Path(storage_dir)
- self.bytes_per_token = bytes_per_token
- self.block_size_tokens = block_size_tokens
- self.block_size_bytes = self.block_size_tokens * self.bytes_per_token
- self.max_blocks = max_blocks
-
- # Fsync configuration
- self.fsync_mode = fsync_mode
- self.fsync_batch_size = fsync_batch_size
- self.pending_sync_count = 0
-
- # Create storage directory
- self.storage_dir.mkdir(parents=True, exist_ok=True)
-
- # Single large file
- self.storage_file = self.storage_dir / "kvcache_storage.bin"
- self.file_size = self.max_blocks * self.block_size_bytes
-
- # Initialize storage file
- if not self.storage_file.exists():
- self._init_storage_file()
-
- # hash_id -> offset mapping (metadata, in memory)
- self.hash_id_to_offset: Dict[int, int] = {}
-
- # Offset allocator (free list)
- self.free_offsets: List[int] = []
- self.next_offset = 0
-
- # File descriptor (keep open, avoid repeated open/close)
- self.fd = None
-
- # Pre-allocated data buffer with pattern to avoid SSD compression artifacts
- # Using a repeating pattern that looks like realistic data (not all zeros)
- # Pattern: 64-byte repeated sequence mixed with some variation
- pattern = bytes([(i & 0xFF) for i in range(256)]) # 0-255 byte pattern
- pattern_repeats = (self.block_size_bytes // len(pattern)) + 1
- self._data_buffer = (pattern * pattern_repeats)[:self.block_size_bytes]
-
- # Statistics
- self.stats = {
- 'read_count': 0,
- 'write_count': 0,
- 'read_bytes': 0,
- 'write_bytes': 0,
- 'read_latencies_ms': [],
- 'write_latencies_ms': [],
- 'sync_count': 0, # Number of fsync operations performed
- }
-
- # ========================================================================
- # Internal Methods
- # ========================================================================
-
- def _init_storage_file(self):
- """Initialize storage file (pre-allocate space)
-
- Create sparse file to avoid actual disk space usage until data is written
- """
- with open(self.storage_file, 'wb') as f:
- f.seek(self.file_size - 1)
- f.write(b'\0')
- f.flush()
- os.fsync(f.fileno())
-
- def _get_fd(self):
- """Get file descriptor (lazy open)
-
- Returns:
- int: File descriptor
- """
- if self.fd is None:
- # Use O_RDWR | O_CREAT, no O_DIRECT (Python compatibility)
- self.fd = os.open(self.storage_file, os.O_RDWR | os.O_CREAT)
- return self.fd
-
- def _allocate_offset(self) -> int:
- """Allocate a new offset
-
- Prioritize reusing freed offsets, otherwise allocate new offset
-
- Returns:
- int: Allocated offset
- """
- if self.free_offsets:
- return self.free_offsets.pop()
- offset = self.next_offset
- self.next_offset += 1
- return offset
-
- def _free_offset(self, offset: int):
- """Free offset for reuse
-
- Args:
- offset: Offset to free
- """
- self.free_offsets.append(offset)
-
- # ========================================================================
- # Public Interface
- # ========================================================================
-
- def block_exists(self, hash_id: int) -> bool:
- """Check if block exists
-
- Args:
- hash_id: Unique block identifier
-
- Returns:
- bool: Whether block exists
- """
- return hash_id in self.hash_id_to_offset
-
- def read_block(self, hash_id: int) -> float:
- """Read block using pread
-
- Args:
- hash_id: Unique block identifier
-
- Returns:
- float: Read latency in milliseconds, or 0 if block doesn't exist
- """
- if hash_id not in self.hash_id_to_offset:
- return 0.0 # Block doesn't exist, no latency to measure
-
- offset = self.hash_id_to_offset[hash_id]
- file_offset = offset * self.block_size_bytes
-
- start = time.perf_counter()
-
- try:
- fd = self._get_fd()
- data = os.pread(fd, self.block_size_bytes, file_offset)
- latency_ms = (time.perf_counter() - start) * 1000.0
-
- self.stats['read_count'] += 1
- self.stats['read_bytes'] += len(data)
- self.stats['read_latencies_ms'].append(latency_ms)
- return latency_ms
- except OSError as e:
- print(f"Error reading block {hash_id} at offset {file_offset}: {e}")
- return 0.0 # Error case, don't pollute stats
-
- def write_block(self, hash_id: int) -> float:
- """Write block using pwrite
-
- Args:
- hash_id: Unique block identifier
-
- Returns:
- float: Write latency in milliseconds
- """
- # Allocate offset
- offset = self._allocate_offset()
- file_offset = offset * self.block_size_bytes
-
- # Use pre-allocated buffer (much faster than os.urandom)
- data = self._data_buffer
-
- start = time.perf_counter()
-
- try:
- fd = self._get_fd()
- written = os.pwrite(fd, data, file_offset)
-
- write_done = time.perf_counter()
-
- # Conditional fsync based on mode
- if self.fsync_mode == 'always':
- # Include fsync in latency measurement
- os.fsync(fd)
- self.stats['sync_count'] += 1
- self.pending_sync_count = 0
- latency_ms = (time.perf_counter() - start) * 1000.0
- # Evict from page cache AFTER fsync to ensure reads measure actual SSD performance
- os.posix_fadvise(fd, file_offset, self.block_size_bytes, os.POSIX_FADV_DONTNEED)
- elif self.fsync_mode == 'batch':
- # For batch mode, only measure write time (fsync is deferred)
- self.pending_sync_count += 1
- if self.pending_sync_count >= self.fsync_batch_size:
- os.fsync(fd)
- self.stats['sync_count'] += 1
- self.pending_sync_count = 0
- latency_ms = (write_done - start) * 1000.0 # Only write time
- # Evict from page cache after each write
- os.posix_fadvise(fd, file_offset, self.block_size_bytes, os.POSIX_FADV_DONTNEED)
- elif self.fsync_mode == 'none':
- latency_ms = (write_done - start) * 1000.0
- # Evict from page cache even when not syncing
- os.posix_fadvise(fd, file_offset, self.block_size_bytes, os.POSIX_FADV_DONTNEED)
- else: # 'end' mode
- latency_ms = (write_done - start) * 1000.0
- # Evict from page cache (fsync will happen at the end)
- os.posix_fadvise(fd, file_offset, self.block_size_bytes, os.POSIX_FADV_DONTNEED)
-
- # Update mapping
- self.hash_id_to_offset[hash_id] = offset
-
- self.stats['write_count'] += 1
- self.stats['write_bytes'] += written
- self.stats['write_latencies_ms'].append(latency_ms)
- return latency_ms
- except OSError as e:
- if e.errno == errno.ENOSPC:
- print(f"Error: Disk full when writing block {hash_id} at offset {file_offset}")
- else:
- print(f"Error writing block {hash_id} at offset {file_offset}: {e}")
- return 0.0 # Error case, don't pollute stats
-
- def __enter__(self):
- """Context manager entry"""
- return self
-
- def __exit__(self, exc_type, exc_val, exc_tb):
- """Context manager exit - ensures cleanup"""
- # Perform final fsync before closing for 'end' and 'batch' modes
- self._finalize_sync()
- self.close(force_sync=False) # Already synced above
- return False
-
- def _finalize_sync(self):
- """Perform final fsync before closing (for 'end' mode and pending batch writes)"""
- if self.fd is not None:
- if self.fsync_mode == 'end':
- try:
- os.fsync(self.fd)
- self.stats['sync_count'] += 1
- except OSError:
- pass
- elif self.fsync_mode == 'batch' and self.pending_sync_count > 0:
- # Flush remaining pending writes
- try:
- os.fsync(self.fd)
- self.stats['sync_count'] += 1
- self.pending_sync_count = 0
- except OSError:
- pass
-
- def close(self, force_sync: bool = True):
- """Close file
-
- Args:
- force_sync: Whether to force fsync before closing
- """
- # For backward compatibility with non-context-manager usage
- if force_sync:
- self._finalize_sync()
-
- if self.fd is not None:
- os.close(self.fd)
- self.fd = None
-
- def get_stats(self) -> Dict:
- """Get statistics
-
- Returns:
- Dict: Dictionary containing read/write statistics
- """
- def calc_stats(latencies):
- """Calculate latency statistics"""
- if not latencies:
- return {'avg_ms': 0, 'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
- return {
- 'avg_ms': statistics.mean(latencies),
- **calc_percentiles(latencies),
- }
-
- return {
- 'read': {
- 'count': self.stats['read_count'],
- 'mb': self.stats['read_bytes'] / 1024 / 1024,
- **calc_stats(self.stats['read_latencies_ms'])
- },
- 'write': {
- 'count': self.stats['write_count'],
- 'mb': self.stats['write_bytes'] / 1024 / 1024,
- **calc_stats(self.stats['write_latencies_ms'])
- },
- 'sync_count': self.stats['sync_count'],
- 'total_blocks': len(self.hash_id_to_offset),
- 'free_blocks': len(self.free_offsets),
- }
-
-
-# ============================================================================
-# Benchmark Layer
-# ============================================================================
-
-class StorageBenchmark:
- """KVCache storage benchmark
-
- Based on Mooncake OffsetAllocator + vLLM PagedAttention implementation:
-
- Example:
- -----
- Request A: [1, 2, 4]
- -> hash_id 1 -> not exist, write block_1 (offset=0, 1MB)
- -> hash_id 2 -> not exist, write block_2 (offset=1, 1MB)
- -> hash_id 4 -> not exist, write block_4 (offset=2, 1MB)
-
- Request B: [1, 2, 4, 6]
- -> hash_id 1 -> exists, read block_1 (offset=0) ✓ prefix reuse
- -> hash_id 2 -> exists, read block_2 (offset=1) ✓ prefix reuse
- -> hash_id 4 -> exists, read block_4 (offset=2) ✓ prefix reuse
- -> hash_id 6 -> not exist, write block_6 (offset=3, 1MB)
-
- Performance Advantages:
- ---------
- - Single file operation, no file explosion
- - Offset reuse, reduces memory allocation
- - pread/pwrite, thread-safe
- """
-
- def __init__(self, storage_dir: str, bytes_per_token: int = DEFAULT_BYTES_PER_TOKEN,
- max_blocks: int = 100000, block_size_tokens: int = 512,
- fsync_mode: str = 'batch', fsync_batch_size: int = 100):
- """Initialize benchmark
-
- Args:
- storage_dir: Storage directory
- bytes_per_token: Bytes per token
- max_blocks: Maximum number of blocks
- block_size_tokens: Number of tokens per block
- fsync_mode: When to fsync ('batch', 'always', 'end', 'none')
- fsync_batch_size: Number of writes between fsync in batch mode
- """
- self.storage = OffsetAllocatorStorage(
- storage_dir, bytes_per_token, max_blocks,
- block_size_tokens, fsync_mode, fsync_batch_size
- )
- self.bytes_per_token = bytes_per_token
- self.block_size_tokens = block_size_tokens
-
- # Statistics
- self.stats = {
- 'total_requests': 0,
- 'total_blocks': 0,
- 'read_blocks': 0,
- 'write_blocks': 0,
- 'prefix_hit_blocks': 0, # Number of prefix hit blocks
- 'request_latencies_ms': [],
- }
-
- def process_request(self, req: KVCacheRequest) -> float:
- """Process a KVCache request
-
- Based on vLLM's prefix caching mechanism:
- - Each hash_id corresponds to an independent block
- - Prefix reuse achieved through hash_id matching
-
- Args:
- req: KVCache request
-
- Returns:
- float: Request latency in milliseconds
- """
- self.stats['total_requests'] += 1
- self.stats['total_blocks'] += len(req.hash_ids)
-
- start_time = time.perf_counter()
- total_latency = 0.0
-
- # Process each hash_id (in order)
- for hash_id in req.hash_ids:
- if self.storage.block_exists(hash_id):
- # Block exists, read (reuse cached block)
- total_latency += self.storage.read_block(hash_id)
- self.stats['read_blocks'] += 1
- self.stats['prefix_hit_blocks'] += 1 # Count all cache hits as prefix reuse
- else:
- # Block doesn't exist, write (new block)
- total_latency += self.storage.write_block(hash_id)
- self.stats['write_blocks'] += 1
-
- latency_ms = total_latency if total_latency > 0 else MIN_LATENCY_MS
- self.stats['request_latencies_ms'].append(latency_ms)
-
- return latency_ms
-
- def get_stats(self) -> Dict:
- """Get statistics
-
- Returns:
- Dict: Statistics dictionary
- """
- storage_stats = self.storage.get_stats()
-
- request_latencies = self.stats['request_latencies_ms']
-
- if request_latencies:
- latency_stats = {
- 'avg_ms': statistics.mean(request_latencies),
- **calc_percentiles(request_latencies),
- }
- else:
- latency_stats = {'avg_ms': 0, 'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
-
- total_blocks = self.stats['total_blocks']
- read_blocks = self.stats['read_blocks']
- write_blocks = self.stats['write_blocks']
-
- return {
- 'total_requests': self.stats['total_requests'],
- 'total_blocks': total_blocks,
- 'read_blocks': read_blocks,
- 'write_blocks': write_blocks,
- 'prefix_hit_blocks': self.stats['prefix_hit_blocks'],
- 'block_hit_rate': read_blocks / total_blocks if total_blocks > 0 else 0,
- 'write_ratio': write_blocks / total_blocks if total_blocks > 0 else 0,
- 'tokens_per_block': self.block_size_tokens, # Configurable block size in tokens
- 'latency': latency_stats,
- 'storage': storage_stats,
- }
-
- def __enter__(self):
- """Context manager entry"""
- return self
-
- def __exit__(self, exc_type, exc_val, exc_tb):
- """Context manager exit - ensures cleanup"""
- self.close()
- return False
-
- def close(self, force_sync: bool = True):
- """Close storage
-
- Args:
- force_sync: Whether to force final sync before closing
- """
- self.storage.close(force_sync=force_sync)
-
-
-# ============================================================================
-# Utility Functions
-# ============================================================================
-
-def calc_percentiles(data: List[float]) -> Dict[str, float]:
- """Calculate latency percentiles
-
- Uses linear interpolation for accurate percentile calculation.
- This is more accurate than statistics.quantiles() for small datasets.
-
- Args:
- data: List of latency values in milliseconds
-
- Returns:
- Dict containing p50, p95, p99 percentiles
- """
- if not data:
- return {'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
-
- # Sort data for percentile calculation
- sorted_data = sorted(data)
- n = len(sorted_data)
-
- def get_percentile(p: float) -> float:
- """Get percentile using linear interpolation
-
- Args:
- p: Percentile (0-100)
-
- Returns:
- Value at percentile
- """
- index = (n - 1) * p / 100
- lower = int(index)
- upper = min(lower + 1, n - 1)
-
- if lower == upper:
- return sorted_data[lower]
-
- # Linear interpolation
- weight = index - lower
- return sorted_data[lower] * (1 - weight) + sorted_data[upper] * weight
-
- return {
- 'p50_ms': get_percentile(50),
- 'p95_ms': get_percentile(95),
- 'p99_ms': get_percentile(99),
- }
-
-
-# ============================================================================
-# Trace Loader
-# ============================================================================
-
-class TraceLoader:
- """Load KVCache trace"""
-
- def __init__(self, trace_path: str):
- """Initialize trace loader
-
- Args:
- trace_path: Trace file path
- """
- self.trace_path = trace_path
- self.requests = []
- self._load_trace()
-
- def _load_trace(self):
- """Load trace file with error handling"""
- line_num = 0
- try:
- with open(self.trace_path, 'r') as f:
- for line in f:
- line_num += 1
- line = line.strip()
- if not line:
- continue
- try:
- req = json.loads(line)
- # Validate required fields
- if not all(k in req for k in ['timestamp', 'hash_ids', 'input_length', 'output_length']):
- print(f"Warning: Line {line_num} missing required fields, skipping")
- continue
- if not isinstance(req['hash_ids'], list):
- print(f"Warning: Line {line_num} has invalid hash_ids (not a list), skipping")
- continue
- self.requests.append(KVCacheRequest(
- timestamp=float(req['timestamp']),
- hash_ids=req['hash_ids'],
- input_length=int(req['input_length']),
- output_length=int(req['output_length'])
- ))
- except (json.JSONDecodeError, ValueError, KeyError) as e:
- print(f"Warning: Line {line_num} has invalid format: {e}, skipping")
- continue
- except FileNotFoundError:
- raise FileNotFoundError(f"Trace file not found: {self.trace_path}")
- except OSError as e:
- raise OSError(f"Error reading trace file {self.trace_path}: {e}")
-
- def get_requests(self) -> List[KVCacheRequest]:
- """Get request list
-
- Returns:
- List[KVCacheRequest]: Request list
- """
- return self.requests
-
-
-# ============================================================================
-# Benchmark Runner
-# ============================================================================
-
-def run_benchmark(trace_path: str, storage_dir: str, bytes_per_token: int = DEFAULT_BYTES_PER_TOKEN,
- max_requests: Optional[int] = None, max_blocks: int = 100000,
- replay_timestamps: bool = False, time_scale: float = 1.0,
- block_size_tokens: int = 512,
- fsync_mode: str = 'batch', fsync_batch_size: int = 100) -> Dict:
- """Run benchmark
-
- Args:
- trace_path: Trace file path
- storage_dir: Storage directory
- bytes_per_token: Bytes per token
- max_requests: Maximum number of requests (None = all)
- max_blocks: Maximum number of blocks
- replay_timestamps: Whether to replay timestamps from trace (simulate realistic timing)
- time_scale: Time scaling factor (1.0=real-time, 0.1=10x speed, 10.0=0.1x speed)
- block_size_tokens: Number of tokens per block
- fsync_mode: When to fsync ('batch', 'always', 'end', 'none')
- fsync_batch_size: Number of writes between fsync in batch mode
-
- Returns:
- Dict: Benchmark results
- """
- block_size_bytes = block_size_tokens * bytes_per_token
-
- print(f"\n{'='*80}")
- print(f"Running: {Path(trace_path).name}")
- print(f"Architecture: Offset Allocator (Mooncake style)")
- print(f"Block size: {block_size_tokens} tokens/block ({block_size_bytes:,} bytes)")
- print(f"Storage: Single large file with offset-based block management")
- print(f"Bytes per token: {bytes_per_token}")
- print(f"Max blocks: {max_blocks}")
- print(f"Fsync mode: {fsync_mode}" + (f" (batch_size={fsync_batch_size})" if fsync_mode == 'batch' else ''))
- print(f"Timestamp replay: {'Enabled' if replay_timestamps else 'Disabled'}")
- if replay_timestamps:
- scale_desc = 'real-time' if time_scale == 1.0 else f'{1/time_scale:.1f}x speed' if time_scale < 1.0 else f'{time_scale}x slower'
- print(f"Time scale: {time_scale}x ({scale_desc})")
- print(f"{'='*80}")
-
- # Load trace
- loader = TraceLoader(trace_path)
- requests = loader.get_requests()
-
- if max_requests:
- requests = requests[:max_requests]
-
- print(f"Loaded {len(requests)} requests")
-
- # Show timestamp range
- if replay_timestamps and requests:
- timestamps = [req.timestamp for req in requests]
- time_span_ms = max(timestamps) - min(timestamps)
- print(f"Timestamp range: {min(timestamps):.1f} - {max(timestamps):.1f} ms (span: {time_span_ms:.1f} ms)")
-
- # Create benchmark instance with context manager for cleanup
- with StorageBenchmark(
- storage_dir, bytes_per_token, max_blocks,
- block_size_tokens, fsync_mode, fsync_batch_size
- ) as benchmark:
-
- # Run benchmark
- start_time = time.perf_counter()
- total_io_time = 0.0 # Actual I/O time (excluding sleep)
- last_timestamp = None
- base_time = time.time() # Use wall time for replay synchronization
-
- for i, req in enumerate(requests):
- # Replay by timestamps
- sleep_time = 0.0
- if replay_timestamps and last_timestamp is not None:
- # Calculate time interval from previous request
- delta_ms = req.timestamp - last_timestamp
- sleep_time = delta_ms / 1000.0 / time_scale # Apply time scaling
-
- if sleep_time > 0:
- time.sleep(sleep_time)
-
- # Process request (measure I/O time)
- req_start = time.perf_counter()
- benchmark.process_request(req)
- req_io_time = time.perf_counter() - req_start
- total_io_time += req_io_time
-
- # Record current request timestamp
- last_timestamp = req.timestamp
-
- # Progress output
- if (i + 1) % 100 == 0:
- if replay_timestamps:
- elapsed_wall_time = time.time() - base_time
- simulated_time = (req.timestamp - requests[0].timestamp) / 1000.0 / time_scale
- print(f" Processed {i + 1}/{len(requests)}... (wall: {elapsed_wall_time:.1f}s, simulated: {simulated_time:.1f}s, io: {total_io_time:.1f}s)")
- else:
- print(f" Processed {i + 1}/{len(requests)}...")
-
- elapsed = time.perf_counter() - start_time
-
- # Perform final sync to include it in stats
- benchmark.storage._finalize_sync()
-
- # Get statistics (context manager will handle cleanup)
- stats = benchmark.get_stats()
-
- # Calculate actual I/O time (excluding sleep)
- io_time = total_io_time if replay_timestamps else elapsed
-
- return {
- 'trace_file': Path(trace_path).name,
- 'total_requests': len(requests),
- 'simulation_time_s': elapsed,
- 'io_time_s': io_time, # Actual I/O time
- 'wall_time_s': elapsed, # Wall time (including sleep)
- 'requests_per_second': len(requests) / io_time if io_time > 0 else 0, # Based on I/O time
- 'timestamp_replay_enabled': replay_timestamps,
- 'time_scale': time_scale,
- 'bytes_per_token': bytes_per_token,
- 'block_size_tokens': block_size_tokens,
- 'fsync_mode': fsync_mode,
- **stats,
- }
-
-
-# ============================================================================
-# Result Output
-# ============================================================================
-
-def print_results(results: List[Dict]):
- """Print benchmark results
-
- Args:
- results: List of benchmark results
- """
- for i, r in enumerate(results, 1):
- print(f"\n{'='*80}")
- print(f" [{i}/{len(results)}] {r['trace_file']}")
- print(f"{'='*80}")
-
- print(f"\n[Performance Overview]")
- print(f" Total Requests: {r['total_requests']:,}")
- print(f" Queries Per Second (QPS): {r['requests_per_second']:.2f}")
- print(f" Cache Hit Rate: {r['block_hit_rate']:.2%}")
- print(f" Write Ratio: {r['write_ratio']:.2%}")
- print(f" Total Blocks: {r['total_blocks']:,}")
- print(f" Read Blocks: {r['read_blocks']:,}")
- print(f" Write Blocks: {r['write_blocks']:,}")
- print(f" Prefix Hits: {r['prefix_hit_blocks']:,}")
-
- print(f"\n[Latency Analysis]")
- req_lat = r['latency']
- print(f" Request Latency (End-to-End): Avg={req_lat['avg_ms']:.2f}ms, P50={req_lat['p50_ms']:.2f}ms, P95={req_lat['p95_ms']:.2f}ms, P99={req_lat['p99_ms']:.2f}ms")
- read_lat = r['storage']['read']
- write_lat = r['storage']['write']
- print(f" Single I/O Operation (Per Block):")
- print(f" Read: Avg={read_lat.get('avg_ms', 0):.3f}ms, P50={read_lat.get('p50_ms', 0):.3f}ms, P95={read_lat.get('p95_ms', 0):.3f}ms, P99={read_lat.get('p99_ms', 0):.3f}ms")
- print(f" Write: Avg={write_lat.get('avg_ms', 0):.3f}ms, P50={write_lat.get('p50_ms', 0):.3f}ms, P95={write_lat.get('p95_ms', 0):.3f}ms, P99={write_lat.get('p99_ms', 0):.3f}ms")
-
- print(f"\n[I/O & Bandwidth]")
- print(f" Total Read I/O: {r['storage']['read']['mb']:>10.1f} MB ({r['storage']['read']['count']:,} ops)")
- print(f" Total Write I/O: {r['storage']['write']['mb']:>10.1f} MB ({r['storage']['write']['count']:,} ops)")
- io_time = r['io_time_s']
- bandwidth = (r['storage']['read']['mb'] + r['storage']['write']['mb']) / io_time
- print(f" Effective Bandwidth: {bandwidth:>10.1f} MB/s")
-
- print(f"\n[Storage Details]")
- print(f" Blocks in Use: {r['storage']['total_blocks']:>10,}")
- print(f" Free Blocks: {r['storage']['free_blocks']:>10,}")
- print(f" Tokens per Block: {r['tokens_per_block']:>10,}")
- print(f" Block Size: {r['tokens_per_block'] * r.get('bytes_per_token', 2048) / 1024 / 1024:>10.2f} MB")
- if 'sync_count' in r['storage']:
- print(f" Fsync Operations: {r['storage']['sync_count']:>10,}")
-
- print(f"\n[Execution Time]")
- if r.get('timestamp_replay_enabled'):
- print(f" Wall Time (Total): {r['wall_time_s']:>10.2f} s")
- print(f" I/O Time (Actual): {r['io_time_s']:>10.2f} s")
- print(f" Sleep Time (Replay): {r['wall_time_s'] - r['io_time_s']:>10.2f} s")
- else:
- print(f" Total Execution Time: {r['wall_time_s']:>10.2f} s")
-
- print(f"\n{'='*80}\n")
-
-
-# ============================================================================
-# Main Program
-# ============================================================================
-
-def main():
- """Main entry point"""
- parser = argparse.ArgumentParser(
- description='Mooncake KVCache Storage Benchmark',
- formatter_class=argparse.RawDescriptionHelpFormatter,
- epilog="""
-Examples:
- # Quick test (100 requests)
- python storage_benchmark.py --scenario=toolagent --max-requests=100
-
- # Test with large model preset (Llama-3.1-405B)
- python storage_benchmark.py --scenario=toolagent --model=llama-3.1-405b --max-requests=100
-
- # Test with Deepseek V3 (extra large model)
- python storage_benchmark.py --scenario=toolagent --model=deepseek-v3 --max-requests=100
-
- # Realistic replay (with timestamps, 10x speed)
- python storage_benchmark.py --scenario=toolagent --max-requests=1000 \\
- --replay-timestamps --time-scale=0.1
-
- # All scenarios with custom bytes_per_token
- python storage_benchmark.py --scenario=all --bytes-per-token=512
-
- # Test with different block sizes and fsync modes
- python storage_benchmark.py --scenario=toolagent --block-size-tokens=256 --fsync-mode=always
-
- # Test with custom fsync batch size
- python storage_benchmark.py --scenario=toolagent --fsync-mode=batch --fsync-batch-size=50
-
-Performance Tuning:
- --fsync-mode=batch (default): Balance between performance and safety
- --fsync-mode=always: Safest but slowest, measures full persistence cost
- --fsync-mode=end: Fastest, only measures write I/O (not persistence)
- --fsync-mode=none: Testing only, no durability guarantees
-
-Available model presets:
- llama-3.1-405b, qwen3-32b, deepseek-v3, glm-4.6, default
-
-For more information: tools/STORAGE_BENCHMARK_README.md
- """
- )
-
- parser.add_argument('--trace-dir', type=str, default='../../FAST25-release/traces',
- help='Trace files directory')
- parser.add_argument('--scenario', type=str, choices=['conversation', 'synthetic', 'toolagent', 'all'],
- default='toolagent', help='Test scenario')
- parser.add_argument('--storage-dir', type=str, default='/tmp/mooncake_bench',
- help='Storage directory')
- parser.add_argument('--model', type=str, choices=list(MODEL_BYTES_PER_TOKEN.keys()),
- default='default',
- help=f'Model preset (overrides --bytes-per-token). Available: {", ".join(MODEL_BYTES_PER_TOKEN.keys())}')
- parser.add_argument('--bytes-per-token', type=int, default=DEFAULT_BYTES_PER_TOKEN,
- help='Bytes per token (default %d, overridden by --model if specified)' % DEFAULT_BYTES_PER_TOKEN)
- parser.add_argument('--max-requests', type=int, default=None,
- help='Maximum number of requests (default: unlimited)')
- parser.add_argument('--max-blocks', type=int, default=100000,
- help='Maximum number of blocks in storage file (determines file size)')
- parser.add_argument('--replay-timestamps', action='store_true',
- help='Enable timestamp replay (simulate realistic request timing)')
- parser.add_argument('--time-scale', type=float, default=1.0,
- help='Time scaling factor (1.0=real-time, 0.1=10x speed, 10.0=0.1x speed)')
- parser.add_argument('--block-size-tokens', type=int, default=512,
- help='Number of tokens per block (default: 512)')
- parser.add_argument('--fsync-mode', type=str, choices=['batch', 'always', 'end', 'none'],
- default='batch',
- help='When to fsync: batch=every N writes (default), always=after each write, end=only at close, none=never')
- parser.add_argument('--fsync-batch-size', type=int, default=100,
- help='Number of writes between fsync in batch mode (default: 100)')
-
- args = parser.parse_args()
-
- # Print benchmark header
- print(f"\n{'='*80}")
- print(f"{'Mooncake KVCache Storage Benchmark':^80}")
- print(f"{'='*80}")
-
- # Determine bytes_per_token (model preset takes precedence)
- bytes_per_token = MODEL_BYTES_PER_TOKEN.get(args.model, args.bytes_per_token)
- if args.model != 'default':
- print(f"Using model preset: {args.model} ({bytes_per_token} bytes/token, ~{bytes_per_token/1024:.1f} KB/token)")
- else:
- print(f"Using custom bytes_per_token: {bytes_per_token}")
-
- # Determine test scenarios
- scenarios = ['conversation', 'synthetic', 'toolagent'] if args.scenario == 'all' else [args.scenario]
- trace_files = {
- 'conversation': 'conversation_trace.jsonl',
- 'synthetic': 'synthetic_trace.jsonl',
- 'toolagent': 'toolagent_trace.jsonl'
- }
-
- # Run benchmarks
- results = []
-
- for scenario in scenarios:
- trace_path = Path(args.trace_dir) / trace_files[scenario]
- if trace_path.exists():
- result = run_benchmark(
- str(trace_path),
- str(Path(args.storage_dir) / scenario),
- bytes_per_token,
- args.max_requests,
- args.max_blocks,
- args.replay_timestamps,
- args.time_scale,
- args.block_size_tokens,
- args.fsync_mode,
- args.fsync_batch_size
- )
- results.append(result)
- else:
- print(f"Warning: Trace file not found: {trace_path}")
-
- # Print results
- if results:
- print_results(results)
-
-
-if __name__ == '__main__':
- main()
diff --git a/benchmarks/storage_benchmark_v1/benchmark.py b/benchmarks/storage_benchmark_v1/benchmark.py
index 3f5ba5ed38..68557d0aab 100644
--- a/benchmarks/storage_benchmark_v1/benchmark.py
+++ b/benchmarks/storage_benchmark_v1/benchmark.py
@@ -11,6 +11,8 @@
import time
import statistics
import signal
+from contextlib import ExitStack
+from concurrent.futures import ThreadPoolExecutor, as_completed
from dataclasses import dataclass
from pathlib import Path
from typing import Iterator, List, Dict, Any
@@ -103,7 +105,8 @@ def __init__(self, storage_dir: str, model_config: dict,
'read_pages': 0,
'write_pages': 0,
'page_hits': 0,
- 'request_latencies_ms': [],
+ 'request_io_latencies_ms': [],
+ 'request_wall_latencies_ms': [],
}
def process_request(self, req: KVCacheRequest) -> float:
@@ -118,13 +121,14 @@ def process_request(self, req: KVCacheRequest) -> float:
self.stats['total_requests'] += 1
self.stats['total_tokens'] += req.input_length + req.output_length
- total_latency = 0.0
+ request_start = time.perf_counter()
+ io_latency_ms = 0.0
# Process each access requirement from layout
for access in self.layout.get_operations(req):
if self.storage.exists(access.page_id):
# Page exists, perform READ
- total_latency += self.storage.read(
+ io_latency_ms += self.storage.read(
access.page_id,
offset_in_page=access.offset_in_page,
length=access.length
@@ -133,39 +137,23 @@ def process_request(self, req: KVCacheRequest) -> float:
self.stats['page_hits'] += 1
else:
# Page doesn't exist, perform WRITE
- total_latency += self.storage.write(
+ io_latency_ms += self.storage.write(
access.page_id,
offset_in_page=access.offset_in_page,
length=access.length
)
self.stats['write_pages'] += 1
- latency_ms = total_latency if total_latency > 0 else 0.0
- if latency_ms > 0:
- self.stats['request_latencies_ms'].append(latency_ms)
- return latency_ms
+ wall_latency_ms = (time.perf_counter() - request_start) * 1000.0
+ self.stats['request_io_latencies_ms'].append(io_latency_ms)
+ self.stats['request_wall_latencies_ms'].append(wall_latency_ms)
+ return io_latency_ms
def get_stats(self) -> Dict:
"""Get statistics"""
storage_stats = self.storage.get_stats()
- request_latencies = self.stats['request_latencies_ms']
-
- if request_latencies:
- sorted_latencies = sorted(request_latencies)
- n = len(sorted_latencies)
-
- def get_percentile(p: float) -> float:
- idx = int(n * p)
- return sorted_latencies[idx] if idx < n else sorted_latencies[-1]
-
- latency_stats = {
- 'avg_ms': statistics.mean(request_latencies),
- 'p50_ms': sorted_latencies[n // 2],
- 'p95_ms': get_percentile(0.95),
- 'p99_ms': get_percentile(0.99),
- }
- else:
- latency_stats = {'avg_ms': 0, 'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
+ request_io_latencies = self.stats['request_io_latencies_ms']
+ request_wall_latencies = self.stats['request_wall_latencies_ms']
total_pages = self.stats['read_pages'] + self.stats['write_pages']
@@ -178,7 +166,8 @@ def get_percentile(p: float) -> float:
'page_hits': self.stats['page_hits'],
'page_hit_rate': self.stats['read_pages'] / total_pages if total_pages > 0 else 0,
'write_ratio': self.stats['write_pages'] / total_pages if total_pages > 0 else 0,
- 'latency': latency_stats,
+ 'request_io_latency': latency_stats(request_io_latencies),
+ 'request_wall_latency': latency_stats(request_wall_latencies),
'storage': storage_stats,
}
@@ -205,10 +194,228 @@ def get_max_page_id(requests: List[KVCacheRequest]) -> int:
return max_id
+def parse_csv_floats(value: str) -> List[float]:
+ return [float(item.strip()) for item in value.split(',') if item.strip()]
+
+
+def wait_for_replay_time(req: KVCacheRequest, base_timestamp: float,
+ start_time: float, replay_scale: float):
+ if replay_scale <= 0 or req.timestamp == 0:
+ return
+ target_time = (start_time +
+ max(0.0, req.timestamp - base_timestamp) /
+ (1000.0 * replay_scale))
+ delay = target_time - time.perf_counter()
+ if delay > 0:
+ time.sleep(delay)
+
+
+def latency_stats(values: List[float]) -> Dict[str, float]:
+ if not values:
+ return {'avg_ms': 0, 'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
+
+ sorted_values = sorted(values)
+
+ def get_percentile(p: float) -> float:
+ if len(sorted_values) == 1:
+ return sorted_values[0]
+ rank = (len(sorted_values) - 1) * p
+ lower = int(rank)
+ upper = min(lower + 1, len(sorted_values) - 1)
+ weight = rank - lower
+ return (sorted_values[lower] * (1.0 - weight) +
+ sorted_values[upper] * weight)
+
+ return {
+ 'avg_ms': statistics.mean(values),
+ 'p50_ms': get_percentile(0.50),
+ 'p95_ms': get_percentile(0.95),
+ 'p99_ms': get_percentile(0.99),
+ }
+
+
+def snapshot_thread_stats(benchmark: StorageBenchmark) -> Dict[str, Any]:
+ storage = benchmark.storage
+ total_pages = benchmark.stats['read_pages'] + benchmark.stats['write_pages']
+ return {
+ 'total_requests': benchmark.stats['total_requests'],
+ 'total_tokens': benchmark.stats['total_tokens'],
+ 'read_pages': benchmark.stats['read_pages'],
+ 'write_pages': benchmark.stats['write_pages'],
+ 'page_hits': benchmark.stats['page_hits'],
+ 'request_io_latencies_ms': list(
+ benchmark.stats['request_io_latencies_ms']
+ ),
+ 'request_wall_latencies_ms': list(
+ benchmark.stats['request_wall_latencies_ms']
+ ),
+ 'read_bytes': storage.stats['read_bytes'],
+ 'write_bytes': storage.stats['write_bytes'],
+ 'read_time_s': storage.stats['read_time_s'],
+ 'write_time_s': storage.stats['write_time_s'],
+ 'read_latencies_ms': list(storage.stats['read_latencies_ms']),
+ 'write_latencies_ms': list(storage.stats['write_latencies_ms']),
+ 'sync_count': storage.stats['sync_count'],
+ 'max_pages': storage.max_pages,
+ 'written_pages': len(storage._written_pages),
+ 'total_pages': total_pages,
+ }
+
+
+def aggregate_thread_stats(thread_stats: List[Dict[str, Any]]) -> Dict:
+ total_requests = sum(s['total_requests'] for s in thread_stats)
+ total_tokens = sum(s['total_tokens'] for s in thread_stats)
+ read_pages = sum(s['read_pages'] for s in thread_stats)
+ write_pages = sum(s['write_pages'] for s in thread_stats)
+ page_hits = sum(s['page_hits'] for s in thread_stats)
+ total_pages = read_pages + write_pages
+
+ request_io_latencies = []
+ request_wall_latencies = []
+ read_latencies = []
+ write_latencies = []
+ for stats in thread_stats:
+ request_io_latencies.extend(stats['request_io_latencies_ms'])
+ request_wall_latencies.extend(stats['request_wall_latencies_ms'])
+ read_latencies.extend(stats['read_latencies_ms'])
+ write_latencies.extend(stats['write_latencies_ms'])
+
+ read_bytes = sum(s['read_bytes'] for s in thread_stats)
+ write_bytes = sum(s['write_bytes'] for s in thread_stats)
+ read_time = sum(s['read_time_s'] for s in thread_stats)
+ write_time = sum(s['write_time_s'] for s in thread_stats)
+
+ return {
+ 'total_requests': total_requests,
+ 'total_tokens': total_tokens,
+ 'total_pages': total_pages,
+ 'read_pages': read_pages,
+ 'write_pages': write_pages,
+ 'page_hits': page_hits,
+ 'page_hit_rate': read_pages / total_pages if total_pages > 0 else 0,
+ 'write_ratio': write_pages / total_pages if total_pages > 0 else 0,
+ 'request_io_latency': latency_stats(request_io_latencies),
+ 'request_wall_latency': latency_stats(request_wall_latencies),
+ 'storage': {
+ 'read': {
+ 'count': read_pages,
+ 'mb': read_bytes / 1024 / 1024,
+ 'time_s': read_time,
+ **latency_stats(read_latencies),
+ },
+ 'write': {
+ 'count': write_pages,
+ 'mb': write_bytes / 1024 / 1024,
+ 'time_s': write_time,
+ **latency_stats(write_latencies),
+ },
+ 'sync_count': sum(s['sync_count'] for s in thread_stats),
+ 'max_pages': sum(s['max_pages'] for s in thread_stats),
+ 'written_pages': sum(s['written_pages'] for s in thread_stats),
+ 'page_hits': page_hits,
+ 'page_misses': write_pages,
+ },
+ }
+
+
+def print_progress(done: int, total: int, start_time: float,
+ stats: Dict, req: KVCacheRequest = None,
+ suffix: str = ""):
+ elapsed = time.perf_counter() - start_time
+ qps = done / elapsed if elapsed > 0 else 0
+ storage = stats.get('storage', {})
+ read_stats = storage.get('read', {})
+ write_stats = storage.get('write', {})
+ read_time = read_stats.get('time_s', 0)
+ write_time = write_stats.get('time_s', 0)
+ read_mbps = read_stats.get('mb', 0) / read_time if read_time > 0 else 0
+ write_mbps = write_stats.get('mb', 0) / write_time if write_time > 0 else 0
+
+ if req is None:
+ req_info = ""
+ else:
+ req_info = (f" ids={len(req.hash_ids):3d} "
+ f"tokens={req.input_length + req.output_length:6d} |")
+
+ print(f" [{done:5d}/{total}]{req_info} QPS={qps:7.2f} | "
+ f"R={stats['read_pages']:6d} "
+ f"({read_stats.get('avg_ms', 0):6.2f}ms, {read_mbps:6.1f}MB/s) | "
+ f"W={stats['write_pages']:6d} "
+ f"({write_stats.get('avg_ms', 0):6.2f}ms, {write_mbps:6.1f}MB/s)"
+ f"{suffix}")
+
+
+def should_print_progress(done: int, total: int, progress_interval: int) -> bool:
+ if done >= total:
+ return True
+ return progress_interval > 0 and done % progress_interval == 0
+
+
+def run_single_thread(benchmark: StorageBenchmark,
+ requests: List[KVCacheRequest],
+ replay_scale: float,
+ progress_interval: int) -> Dict[str, Any]:
+ start_time = time.perf_counter()
+ base_timestamp = requests[0].timestamp if requests else 0
+ completed = 0
+
+ for req in requests:
+ wait_for_replay_time(req, base_timestamp, start_time, replay_scale)
+ benchmark.process_request(req)
+ completed += 1
+ if should_print_progress(completed, len(requests), progress_interval):
+ print_progress(completed, len(requests), start_time,
+ benchmark.get_stats(), req)
+
+ return {
+ 'completed': completed,
+ 'elapsed': time.perf_counter() - start_time,
+ 'stats': benchmark.get_stats(),
+ }
+
+
+def run_multi_thread(benchmarks: List[StorageBenchmark],
+ requests: List[KVCacheRequest],
+ replay_scale: float) -> Dict[str, Any]:
+ start_time = time.perf_counter()
+ base_timestamp = requests[0].timestamp if requests else 0
+ total_requests = len(requests) * len(benchmarks)
+ completed = 0
+
+ def run_worker(thread_id: int):
+ benchmark = benchmarks[thread_id]
+ for req in requests:
+ wait_for_replay_time(req, base_timestamp, start_time, replay_scale)
+ benchmark.process_request(req)
+ return snapshot_thread_stats(benchmark)
+
+ thread_stats = []
+ with ThreadPoolExecutor(max_workers=len(benchmarks)) as executor:
+ futures = [
+ executor.submit(run_worker, thread_id)
+ for thread_id in range(len(benchmarks))
+ ]
+ for future in as_completed(futures):
+ worker_stats = future.result()
+ thread_stats.append(worker_stats)
+ completed += worker_stats['total_requests']
+ print_progress(completed, total_requests, start_time,
+ aggregate_thread_stats(thread_stats),
+ suffix=" | completed worker")
+
+ return {
+ 'completed': completed,
+ 'elapsed': time.perf_counter() - start_time,
+ 'stats': aggregate_thread_stats(thread_stats),
+ }
+
+
def run_benchmark(trace_path: str, storage_dir: str, model_config: dict,
max_requests: int = None, max_pages: int = None,
page_size_tokens: int = 512,
- fsync_mode: str = 'none', fsync_batch_size: int = 100) -> Dict:
+ fsync_mode: str = 'none', fsync_batch_size: int = 100,
+ threads: int = 1, replay_scale: float = 0.0,
+ progress_interval: int = 100) -> Dict:
"""Run benchmark
Args:
@@ -220,6 +427,9 @@ def run_benchmark(trace_path: str, storage_dir: str, model_config: dict,
page_size_tokens: Tokens per page
fsync_mode: When to fsync
fsync_batch_size: Number of writes between fsync
+ threads: Benchmark client worker threads
+ replay_scale: Timestamp replay multiplier; 0 runs unpaced
+ progress_interval: Print progress every N requests; 0 disables progress
Returns:
Benchmark results dictionary
@@ -229,6 +439,8 @@ def run_benchmark(trace_path: str, storage_dir: str, model_config: dict,
print(f"Model: {model_config['name']}")
print(f"Layers: {model_config['num_layers']}")
print(f"Page size: {page_size_tokens} tokens")
+ print(f"Threads: {threads}")
+ print(f"Fast-forward: {replay_scale:g}x" if replay_scale > 0 else "Fast-forward: unpaced")
print(f"{'='*80}")
# Load trace
@@ -266,7 +478,11 @@ def run_benchmark(trace_path: str, storage_dir: str, model_config: dict,
print(f" Pages needed (trace): {max_pages_needed:,}")
print(f" Trace storage size: {trace_size_gb:.2f} GB")
print(f" Max pages configured: {max_pages:,}")
+ if threads > 1:
+ print(f" Max pages across threads: {max_pages * threads:,}")
print(f" Max storage available: {max_size_gb:.2f} GB")
+ if threads > 1:
+ print(f" Max storage across threads: {max_size_gb * threads:.2f} GB")
if max_pages_needed > max_pages:
shortfall = max_pages_needed - max_pages
@@ -279,65 +495,69 @@ def run_benchmark(trace_path: str, storage_dir: str, model_config: dict,
surplus_pct = (surplus / max_pages) * 100 if max_pages > 0 else 0
print(f" ✓ Direct mapping: all {max_pages_needed:,} logical pages uniquely mapped")
- # Run benchmark
- with StorageBenchmark(
- storage_dir=storage_dir,
- model_config=model_config,
- page_size_tokens=page_size_tokens,
- max_pages=max_pages,
- fsync_mode=fsync_mode,
- fsync_batch_size=fsync_batch_size
- ) as benchmark:
- start_time = time.perf_counter()
- try:
- for i, req in enumerate(requests):
- benchmark.process_request(req)
- # Print progress for each request
- elapsed = time.perf_counter() - start_time
- qps = (i + 1) / elapsed if elapsed > 0 else 0
- stats = benchmark.get_stats()
- storage = stats.get('storage', {})
- read_latency = storage.get('read', {}).get('avg_ms', 0)
- write_latency = storage.get('write', {}).get('avg_ms', 0)
- read_mb = storage.get('read', {}).get('mb', 0)
- write_mb = storage.get('write', {}).get('mb', 0)
- read_time = storage.get('read', {}).get('time_s', 0)
- write_time = storage.get('write', {}).get('time_s', 0)
- read_mbps = read_mb / read_time if read_time > 0 else 0
- write_mbps = write_mb / write_time if write_time > 0 else 0
- print(f" [{i+1:5d}/{len(requests)}] ids={len(req.hash_ids):3d} "
- f"tokens={req.input_length+req.output_length:6d} | "
- f"QPS={qps:7.2f} | "
- f"R={stats['read_pages']:6d} ({read_latency:6.2f}ms, {read_mbps:6.1f}MB/s) | "
- f"W={stats['write_pages']:6d} ({write_latency:6.2f}ms, {write_mbps:6.1f}MB/s)")
- except KeyboardInterrupt:
- print(f"\n\n{'='*80}")
- print(f"Interrupted! Showing partial results:")
- print(f"{'='*80}")
- elapsed = time.perf_counter() - start_time
- stats = benchmark.get_stats()
- print_results([{
- 'trace_file': Path(trace_path).name,
- 'total_requests': i + 1,
- 'io_time_s': elapsed,
- 'requests_per_second': (i + 1) / elapsed if elapsed > 0 else 0,
- 'model': model_config['name'],
- 'fsync_mode': fsync_mode,
- **stats,
- }])
- sys.exit(0)
-
- elapsed = time.perf_counter() - start_time
- stats = benchmark.get_stats()
+ try:
+ if threads <= 1:
+ with StorageBenchmark(
+ storage_dir=storage_dir,
+ model_config=model_config,
+ page_size_tokens=page_size_tokens,
+ max_pages=max_pages,
+ fsync_mode=fsync_mode,
+ fsync_batch_size=fsync_batch_size
+ ) as benchmark:
+ result = run_single_thread(benchmark, requests, replay_scale,
+ progress_interval)
+ else:
+ with ExitStack() as stack:
+ benchmarks = [
+ stack.enter_context(StorageBenchmark(
+ storage_dir=str(Path(storage_dir) / f"thread_{thread_id}"),
+ model_config=model_config,
+ page_size_tokens=page_size_tokens,
+ max_pages=max_pages,
+ fsync_mode=fsync_mode,
+ fsync_batch_size=fsync_batch_size
+ ))
+ for thread_id in range(threads)
+ ]
+ result = run_multi_thread(benchmarks, requests, replay_scale)
+ except KeyboardInterrupt:
+ print(f"\n\n{'='*80}")
+ print(f"Interrupted! Showing partial results:")
+ print(f"{'='*80}")
+ result = result if 'result' in locals() else {
+ 'completed': 0,
+ 'elapsed': 0,
+ 'stats': {},
+ }
+ print_results([{
+ 'trace_file': Path(trace_path).name,
+ 'total_requests': result['completed'],
+ 'io_time_s': result['elapsed'],
+ 'requests_per_second': (
+ result['completed'] / result['elapsed']
+ if result['elapsed'] > 0 else 0
+ ),
+ 'model': model_config['name'],
+ 'fsync_mode': fsync_mode,
+ 'threads': threads,
+ 'replay_scale': replay_scale,
+ **result['stats'],
+ }])
+ sys.exit(0)
return {
'trace_file': Path(trace_path).name,
- 'total_requests': len(requests),
- 'io_time_s': elapsed,
- 'requests_per_second': len(requests) / elapsed if elapsed > 0 else 0,
+ 'total_requests': result['completed'],
+ 'io_time_s': result['elapsed'],
+ 'requests_per_second': (
+ result['completed'] / result['elapsed'] if result['elapsed'] > 0 else 0
+ ),
'model': model_config['name'],
'fsync_mode': fsync_mode,
- **stats,
+ 'threads': threads,
+ 'replay_scale': replay_scale,
+ **result['stats'],
}
@@ -350,6 +570,8 @@ def format_storage_stats(stats: Dict, title: str = "Storage"):
storage = stats.get('storage', {})
read_stats = storage.get('read', {})
write_stats = storage.get('write', {})
+ request_wall = stats.get('request_wall_latency', {})
+ request_io = stats.get('request_io_latency', {})
output = []
output.append(f"\n[{title}]")
@@ -357,12 +579,28 @@ def format_storage_stats(stats: Dict, title: str = "Storage"):
# General info
output.append(f"\n[General]")
output.append(f" Model: {stats.get('model', 'N/A')}")
+ output.append(f" Threads: {stats.get('threads', 1)}")
+ replay_scale = stats.get('replay_scale', 0)
+ output.append(f" Fast-forward: {f'{replay_scale:g}x' if replay_scale else 'unpaced'}")
output.append(f" Requests: {stats.get('total_requests', 0):,}")
output.append(f" Tokens: {stats.get('total_tokens', 0):,}")
output.append(f" Total I/O Time: {stats.get('io_time_s', 0):.3f} s")
output.append(f" QPS: {stats.get('requests_per_second', 0):.2f}")
output.append(f" Hit Rate: {stats.get('page_hit_rate', 0):.2%}")
+ # Request Stats
+ output.append(f"\n[Request Wall Latency]")
+ output.append(f" Avg: {request_wall.get('avg_ms', 0):.3f} ms")
+ output.append(f" P50: {request_wall.get('p50_ms', 0):.3f} ms")
+ output.append(f" P95: {request_wall.get('p95_ms', 0):.3f} ms")
+ output.append(f" P99: {request_wall.get('p99_ms', 0):.3f} ms")
+
+ output.append(f"\n[Request Storage I/O Latency]")
+ output.append(f" Avg: {request_io.get('avg_ms', 0):.3f} ms")
+ output.append(f" P50: {request_io.get('p50_ms', 0):.3f} ms")
+ output.append(f" P95: {request_io.get('p95_ms', 0):.3f} ms")
+ output.append(f" P99: {request_io.get('p99_ms', 0):.3f} ms")
+
# Read Stats
output.append(f"\n[Read Operations]")
output.append(f" Count: {read_stats.get('count', 0):,}")
@@ -438,8 +676,18 @@ def main():
default='none', help='When to fsync')
parser.add_argument('--fsync-batch-size', type=int, default=100,
help='Number of writes between fsync')
+ parser.add_argument('--threads', type=int, default=1,
+ help='Number of benchmark client worker threads')
+ parser.add_argument('--replay-scales', type=str, default='0',
+ help='Comma-separated trace fast-forward speeds; 0 means unpaced')
+ parser.add_argument('--progress-interval', type=int, default=100,
+ help='Print progress every N requests; 0 disables per-request progress')
args = parser.parse_args()
+ if args.threads < 1:
+ parser.error('--threads must be at least 1')
+ if args.progress_interval < 0:
+ parser.error('--progress-interval must be non-negative')
print(f"\n{'='*80}")
print(f"{'Mooncake KVCache Storage Benchmark':^80}")
@@ -447,6 +695,11 @@ def main():
model_config = get_model_config(args.model)
print(f"Model: {args.model} ({model_config['num_layers']} layers)")
+ replay_scales = parse_csv_floats(args.replay_scales)
+ if not replay_scales:
+ parser.error('--replay-scales must include at least one value')
+ if any(scale < 0 for scale in replay_scales):
+ parser.error('--replay-scales values must be non-negative')
# Determine scenarios
scenarios = ['conversation', 'synthetic', 'toolagent'] if args.scenario == 'all' else [args.scenario]
@@ -458,20 +711,28 @@ def main():
# Run benchmarks
results = []
+ use_scale_subdirs = len(replay_scales) > 1 or replay_scales[0] != 0
for scenario in scenarios:
trace_path = Path(args.trace_dir) / trace_files[scenario]
if trace_path.exists():
- result = run_benchmark(
- str(trace_path),
- str(Path(args.storage_dir) / scenario),
- model_config,
- args.max_requests,
- args.max_pages,
- args.page_size_tokens,
- args.fsync_mode,
- args.fsync_batch_size
- )
- results.append(result)
+ for replay_scale in replay_scales:
+ run_dir = Path(args.storage_dir) / scenario
+ if use_scale_subdirs:
+ run_dir = run_dir / f"replay_{replay_scale:g}x"
+ result = run_benchmark(
+ str(trace_path),
+ str(run_dir),
+ model_config,
+ args.max_requests,
+ args.max_pages,
+ args.page_size_tokens,
+ args.fsync_mode,
+ args.fsync_batch_size,
+ args.threads,
+ replay_scale,
+ args.progress_interval
+ )
+ results.append(result)
else:
print(f"Warning: Trace file not found: {trace_path}")
diff --git a/benchmarks/storage_benchmark_v1/doc/README.md b/benchmarks/storage_benchmark_v1/doc/README.md
index fa490aadff..8b53be660a 100644
--- a/benchmarks/storage_benchmark_v1/doc/README.md
+++ b/benchmarks/storage_benchmark_v1/doc/README.md
@@ -28,12 +28,47 @@ python benchmark.py --scenario conversation \
| `--max-pages` | `2000` | Maximum number of pages (creates modulo mapping if trace is larger) |
| `--fsync-mode` | `none` | When to fsync: `none`, `batch`, `always`, or `end` |
| `--fsync-batch-size` | `100` | Number of writes between fsync in batch mode |
+| `--threads` | `1` | Number of benchmark client worker threads |
+| `--replay-scales` | `0` | Comma-separated trace fast-forward speeds; `0` means unpaced |
+| `--progress-interval` | `100` | Print progress every N requests; `0` disables per-request progress |
+
+### Replay Scale
+
+Use `--replay-scales` to run the same trace at different fast-forward speeds:
+
+```bash
+python benchmark.py --scenario toolagent \
+ --trace-dir /path/to/Mooncake/FAST25-release/traces \
+ --storage-dir /path/to/test/drive \
+ --replay-scales 1,2,4,8
+```
+
+For example, `2` means 2x fast-forward and `8` means 8x fast-forward. `0`
+preserves the old unpaced behavior.
+
+### Client Threads
+
+Use `--threads` to add benchmark client worker threads:
+
+```bash
+python benchmark.py --scenario toolagent \
+ --trace-dir /path/to/Mooncake/FAST25-release/traces \
+ --storage-dir /path/to/test/drive \
+ --threads 4
+```
+
+With `--threads > 1`, each benchmark client thread uses an independent storage
+file under `thread_N/data.bin`, similar to running multiple clients at the same
+time. Final results aggregate the per-thread counters and latency samples. For
+strict single-client trace-order read/write and hit-rate accounting, use
+`--threads 1`.
## Output Format
### Progress Output
-During execution, each request displays real-time statistics:
+During execution, progress is printed every `--progress-interval` requests and
+at the end of the run:
```
[ 10/12031] ids= 35 tokens= 18060 | QPS= 2.45 | R= 36 ( 22.01ms, 2435.2MB/s) | W= 963 ( 19.35ms, 2770.1MB/s)
@@ -56,12 +91,26 @@ Fields:
[General]
Model: glm5
+ Threads: 1
+ Fast-forward: unpaced
Requests: 12031
Tokens: 123456789
Total I/O Time: 245.123 s
QPS: 49.07
Hit Rate: 3.25%
+[Request Wall Latency]
+ Avg: 20.912 ms
+ P50: 19.654 ms
+ P95: 28.123 ms
+ P99: 34.987 ms
+
+[Request Storage I/O Latency]
+ Avg: 20.312 ms
+ P50: 18.987 ms
+ P95: 27.456 ms
+ P99: 33.210 ms
+
[Read Operations]
Count: 390
Data Volume: 20919.62 MB
@@ -90,6 +139,28 @@ Fields:
Sync Count: 0
```
+`Request Wall Latency` measures the benchmark client's wall-clock time spent
+processing a request after replay pacing. `Request Storage I/O Latency` is the
+sum of the request's page read/write latencies. Read/write operation latency is
+reported per page operation. Percentile values use linear interpolation.
+
+## Measurement Notes
+
+- The default `--fsync-mode none` measures page-cache-backed write behavior. It
+ does not represent durable write latency. Use `--fsync-mode always`, `batch`,
+ or `end` when persistence cost is part of the benchmark target.
+- `pread`/`pwrite` latency is measured from user space, so it can include page
+ cache effects, OS scheduling, and Python benchmark-client overhead. Treat the
+ reported latency as an observed storage-path latency, not raw device service
+ time.
+- With `--threads > 1`, each thread replays the full trace as an independent
+ benchmark client with its own storage file. This is a multi-client drive test,
+ not parallel execution of one trace stream.
+- For publication-quality numbers, use a fixed machine and storage device,
+ clear or isolate benchmark storage directories between runs, disable
+ per-request progress output with `--progress-interval 0`, and run multiple
+ trials before reporting stable statistics.
+
## Modulo Mapping
When the trace requires more pages than `--max-pages`, modulo mapping is enabled:
diff --git a/benchmarks/storage_benchmark_v1/storage/disk.py b/benchmarks/storage_benchmark_v1/storage/disk.py
index 286ff7510f..64089a6b44 100644
--- a/benchmarks/storage_benchmark_v1/storage/disk.py
+++ b/benchmarks/storage_benchmark_v1/storage/disk.py
@@ -18,11 +18,16 @@ def calc_percentiles(data):
return {'avg_ms': 0, 'p50_ms': 0, 'p95_ms': 0, 'p99_ms': 0}
import statistics
sorted_data = sorted(data)
- n = len(sorted_data)
+
def get_percentile(p):
- idx = int(n * p / 100)
- if idx >= n: idx = n - 1
- return sorted_data[idx]
+ if len(sorted_data) == 1:
+ return sorted_data[0]
+ rank = (len(sorted_data) - 1) * (p / 100)
+ lower = int(rank)
+ upper = min(lower + 1, len(sorted_data) - 1)
+ weight = rank - lower
+ return sorted_data[lower] * (1.0 - weight) + sorted_data[upper] * weight
+
return {
'avg_ms': statistics.mean(data),
'p50_ms': get_percentile(50),
diff --git a/dependencies.sh b/dependencies.sh
index bbbd82aa32..955d0494c0 100755
--- a/dependencies.sh
+++ b/dependencies.sh
@@ -175,6 +175,7 @@ if [ "$OS" = "ubuntu" ] || [ "$OS" = "debian" ]; then
liburing-dev \
libjemalloc-dev \
libmsgpack-dev \
+ libzmq3-dev \
libzstd-dev \
libasio-dev \
libxxhash-dev \
diff --git a/docs/AGENTS.md b/docs/AGENTS.md
new file mode 100644
index 0000000000..debb165ca2
--- /dev/null
+++ b/docs/AGENTS.md
@@ -0,0 +1,90 @@
+# AGENTS.md - Mooncake Documentation
+
+This file gives coding agents the repo-local rules for modifying files under
+`docs/`. Keep `README.md` as the human-facing quickstart. Use this file for
+agent workflow, verification, and maintenance guidance.
+
+## Scope
+
+- Applies to changes under `docs/`, especially `docs/source/`.
+- Prefer small, reviewable documentation changes.
+- Do not rewrite unrelated pages, generated files, or formatting-only content.
+- Preserve existing documentation structure unless the user asks for a broader
+ reorganization.
+
+## Build and Preview
+
+Run documentation commands from the `docs` directory:
+
+```
+cd docs
+```
+
+Install dependencies with `uv` when needed. The requirements file is
+`docs/requirements-docs.txt`; after `cd docs`, use the local filename. If there
+is an existing venv, prefer using the existing one. Otherwise, create one before
+installing dependencies:
+
+```
+uv venv
+uv pip install -r requirements-docs.txt
+```
+
+Clean stale build output when validating navigation, generated API pages, or
+theme behavior:
+
+```
+make clean
+```
+
+Build HTML before handing off user-visible documentation changes:
+
+```
+make html
+```
+
+Set `locale` correctly before building when the change depends on localized
+content or translated output.
+
+Serve the generated site for review:
+
+```
+python -m http.server -d build/html/
+```
+
+The default URL is `http://localhost:8000`. If port 8000 is busy, choose another
+available port.
+
+## Editing Guidance
+
+- Source pages live under `docs/source/`.
+- Keep links relative and Sphinx-compatible unless an external URL is required.
+- For navigation changes, inspect `docs/source/index.md` and the relevant
+ toctree before editing individual pages.
+- Use Sphinx-native structure for documentation behavior. Do not use client-side
+ JavaScript or post-render DOM patches for navigation or theme behavior.
+- If the requested behavior is not supported by Sphinx or the active theme,
+ prefer adding a Sphinx extension/plugin instead of patching rendered HTML.
+- When a page should be linked from content but excluded from the main sidebar,
+ use a content link plus appropriate Sphinx metadata such as `orphan: true`
+ instead of hiding rendered sidebar nodes.
+- Keep homepage toctree depth conservative. Do not increase `index.md` maxdepth
+ unless the user explicitly asks for deeper landing-page nesting.
+
+## Validation Checklist
+
+- Run `make html` for docs changes that affect rendered pages, navigation,
+ cross-references, or Sphinx configuration.
+- Check the generated HTML for the changed pages.
+- For sidebar or toctree changes, verify both the article body and left sidebar
+ render the intended entries.
+- If a local preview server is useful for review, start one from `docs/` with
+ `python -m http.server -d build/html/` or an alternate port.
+
+## Pull Request Hygiene
+
+- Keep docs-only changes narrowly scoped.
+- Review `git diff` before staging so generated files or hook-only formatting
+ changes do not leak into the PR.
+- If opening a PR, use the repository pull request template.
+- Use the repository PR title prefix rules from the root `AGENTS.md`.
diff --git a/docs/source/deployment/kubernetes-deployment-guide/index.md b/docs/source/deployment/kubernetes-deployment-guide/index.md
new file mode 100644
index 0000000000..c87126f436
--- /dev/null
+++ b/docs/source/deployment/kubernetes-deployment-guide/index.md
@@ -0,0 +1,45 @@
+# Kubernetes Deployment Guide
+
+Run Mooncake on Kubernetes as a shared **Store** cluster paired with SGLang **prefill/decode** inference — the Store serves as a HiCache L3 backend, while Mooncake's **Transfer Engine** moves KV cache directly between prefill and decode.
+
+---
+
+## Store + Transfer Engine (P/D disaggregation)
+
+A long-lived `mooncake-master` plus a replicated set of `mooncake-store` nodes form a shareable DRAM KV pool. The SGLang **prefill** pods use that pool as their hierarchical-cache L3 backend; **prefill and decode** use Mooncake's Transfer Engine for zero-copy P/D KV transfer over RDMA/TCP. A router fronts the prefill and decode endpoints.
+
+```
+ Store cluster (no GPU)
+ +--------------------------------------------+
+ | mooncake-master metadata + RPC |
+ | mooncake-store ×N (DRAM KV pool) |
+ +--------------------------------------------+
+ ▲
+ HiCache L3 │ (Get/Put) + metadata / RPC
+ │
+ +-----┴-----+ Transfer +-----------+
+ | SGLang | Engine | SGLang |
+ | Prefill |◄═════════════►| Decode |
+ | (GPU) | KV blocks | (GPU) |
+ +-----┬-----+ (RDMA/TCP) +-----┬-----+
+ ▲ ▲
+ │ │
+ +--------+ +-----┴---------------------------┴-----+
+ | client |──►| sglang-router |
+ +--------+ +---------------------------------------+
+```
+
+**This section covers:**
+
+- [Mooncake on Kubernetes](mooncake-on-kubernetes) — stand up the Mooncake Store cluster with plain `Deployment` / `Service` objects.
+- [RBG Integration](rbg-integration) — the full Store + P/D scenario with the [sgl-project/rbg](https://github.com/sgl-project/rbg) operator, including a production Mooncake cluster case.
+
+See also the [Mooncake Store Deployment & Tuning Guide](../mooncake-store-deployment-guide.md) for the component overview, client configuration, and tuning knobs.
+
+:::{toctree}
+:maxdepth: 1
+:hidden:
+
+mooncake-on-kubernetes
+rbg-integration
+:::
diff --git a/docs/source/deployment/kubernetes-deployment-guide/mooncake-on-kubernetes.md b/docs/source/deployment/kubernetes-deployment-guide/mooncake-on-kubernetes.md
new file mode 100644
index 0000000000..8316706856
--- /dev/null
+++ b/docs/source/deployment/kubernetes-deployment-guide/mooncake-on-kubernetes.md
@@ -0,0 +1,134 @@
+# Mooncake on Kubernetes
+
+Deploy a Mooncake Store cluster — a `mooncake-master` plus replicated `mooncake-store` nodes — with plain Kubernetes objects (`Deployment` and `Service`).
+
+Use it together with the [Mooncake Store Deployment & Tuning Guide](../mooncake-store-deployment-guide.md): that guide explains the components and tuning knobs; this page maps them to Kubernetes objects.
+
+## Deploy the Mooncake Store cluster
+
+A shareable Store cluster has one `mooncake-master` (the RPC coordinator) and a replicated set of stateless `mooncake-store` nodes that contribute DRAM to the pool. The nodes use Mooncake's P2P handshake (`P2PHANDSHAKE`) for Transfer Engine peer discovery, so there is no separate metadata service to run — each node stores its metadata locally and exchanges it with peers during connection setup. It needs no GPUs, and multiple inference deployments can point at the same cluster. The store nodes reach the master through the `mooncake-master` `Service`.
+
+```yaml
+apiVersion: apps/v1
+kind: Deployment
+metadata:
+ name: mooncake-master
+ labels:
+ app: mooncake-master
+spec:
+ replicas: 1
+ selector:
+ matchLabels:
+ app: mooncake-master
+ template:
+ metadata:
+ labels:
+ app: mooncake-master
+ spec:
+ containers:
+ - name: mooncake-master
+ image: lmsysorg/sglang:v0.5.5
+ command: ["mooncake_master"]
+ args:
+ - --rpc_address
+ - $(POD_IP)
+ - --rpc_port
+ - "50051"
+ - --metrics_port
+ - "9003"
+ env:
+ - name: POD_IP
+ valueFrom:
+ fieldRef:
+ fieldPath: status.podIP
+ ports:
+ - name: rpc
+ containerPort: 50051
+ - name: metrics
+ containerPort: 9003
+ readinessProbe:
+ tcpSocket:
+ port: 50051
+ initialDelaySeconds: 10
+ periodSeconds: 10
+---
+apiVersion: v1
+kind: Service
+metadata:
+ name: mooncake-master
+ labels:
+ app: mooncake-master
+spec:
+ type: ClusterIP
+ selector:
+ app: mooncake-master
+ ports:
+ - name: rpc
+ port: 50051
+ targetPort: 50051
+ - name: metrics
+ port: 9003
+ targetPort: 9003
+---
+apiVersion: apps/v1
+kind: Deployment
+metadata:
+ name: mooncake-store
+ labels:
+ app: mooncake-store
+spec:
+ replicas: 3
+ selector:
+ matchLabels:
+ app: mooncake-store
+ template:
+ metadata:
+ labels:
+ app: mooncake-store
+ spec:
+ containers:
+ - name: mooncake-store
+ image: lmsysorg/sglang:v0.5.5
+ command: ["python3", "-m", "mooncake.mooncake_store_service"]
+ args: ["--port", "8088"]
+ env:
+ - name: MOONCAKE_MASTER
+ value: "mooncake-master:50051"
+ - name: MOONCAKE_TE_META_DATA_SERVER
+ value: "P2PHANDSHAKE"
+ - name: MOONCAKE_GLOBAL_SEGMENT_SIZE
+ value: "10gb"
+ - name: MOONCAKE_LOCAL_BUFFER_SIZE
+ value: "0"
+ - name: MOONCAKE_PROTOCOL
+ value: "rdma"
+ resources:
+ requests:
+ memory: "16Gi"
+ limits:
+ memory: "16Gi"
+```
+
+See [Notes](#notes) for capacity, protocol (TCP/RDMA), and metadata guidance.
+
+**Verify:**
+
+```bash
+kubectl get pods -l app=mooncake-master
+kubectl get pods -l app=mooncake-store
+# Master metrics summary:
+kubectl port-forward svc/mooncake-master 9003:9003 &
+curl -s http://localhost:9003/metrics/summary
+```
+
+## Notes
+
+**Metadata (P2P handshake).** These manifests use Mooncake's P2P handshake (`MOONCAKE_TE_META_DATA_SERVER: P2PHANDSHAKE`): each node stores Transfer Engine metadata locally and exchanges it with peers during connection setup, so there is nothing extra to run and the `mooncake-master` needs no `--*http_metadata_server*` flags. This is the recommended starting point. For large or long-lived clusters, switch the store nodes to the master's embedded HTTP metadata server or an external etcd/Redis instead; see the store guide's [Deployment Scenarios](../mooncake-store-deployment-guide.md#deployment-scenarios).
+
+**High availability.** A single `mooncake-master` is a single point of failure. For HA, see the store guide's [High Availability](../mooncake-store-deployment-guide.md#deployment-scenarios) section for etcd/Redis backends.
+
+**TCP vs RDMA.** `MOONCAKE_PROTOCOL` selects the fabric. These manifests use `rdma`. Granting pods RDMA access is cluster-specific and not fully wired into the YAML above; the production reference (see [RBG Integration](rbg-integration)) does it with `hostNetwork: true`, a hostPath mount of `/dev/infiniband`, `privileged` + `IPC_LOCK`/`SYS_RESOURCE`, and an explicit NIC list via `MOONCAKE_DEVICE=`. (A device-plugin `rdma/hca` resource with `MC_MS_AUTO_DISC` / `MC_MS_FILTERS` auto-discovery is an alternative on clusters set up that way.) Switch `MOONCAKE_PROTOCOL` to `tcp` on clusters without an RDMA fabric.
+
+**Capacity.** Keep `MOONCAKE_GLOBAL_SEGMENT_SIZE` within each pod's memory `limit`. A pure store node issues no `Get`/`Put` itself, so its `MOONCAKE_LOCAL_BUFFER_SIZE` is small; the production RDMA reference sets a modest non-zero buffer (`67108864` = 64 MiB) rather than `0`.
+
+**Images.** The example uses `lmsysorg/sglang:v0.5.5`. This tag is **not** a reproducible pin — for production, replace it with a verified tag or digest.
diff --git a/docs/source/deployment/kubernetes-deployment-guide/rbg-integration.md b/docs/source/deployment/kubernetes-deployment-guide/rbg-integration.md
new file mode 100644
index 0000000000..ecd6fc5590
--- /dev/null
+++ b/docs/source/deployment/kubernetes-deployment-guide/rbg-integration.md
@@ -0,0 +1,280 @@
+# RBG Integration
+
+This page covers the same Store + Transfer Engine P/D scenario as the [main guide](index), deployed with the [sgl-project/rbg](https://github.com/sgl-project/rbg) operator instead of the vanilla `Deployment` / `Service` manifests on the [Mooncake on Kubernetes](mooncake-on-kubernetes) page. Install the RBG operator before applying any `RoleBasedGroup`.
+
+## RBG example
+
+The upstream RBG repository ships ready-to-use examples for running Mooncake on RBG:
+
+- [sgl-pd-disagg-with-mooncake-te.yaml](https://github.com/sgl-project/rbg/blob/main/examples/inference/ecosystem/mooncake/mooncake-transfer-engine/sgl-pd-disagg-with-mooncake-te.yaml) — SGLang P/D disaggregation using Mooncake's Transfer Engine for KV transfer.
+- [vllm-pd-disagg-with-mooncake-te.yaml](https://github.com/sgl-project/rbg/blob/main/examples/inference/ecosystem/mooncake/mooncake-transfer-engine/vllm-pd-disagg-with-mooncake-te.yaml) — vLLM P/D disaggregation using Mooncake's Transfer Engine for KV transfer.
+- [standalone-mooncake-store.yaml](https://github.com/sgl-project/rbg/blob/main/examples/inference/ecosystem/mooncake/mooncake-store/standalone-mooncake-store.yaml) — the shareable standalone Mooncake Store cluster (`mooncake-master` + `mooncake-store` roles).
+
+For background on the integration, see the RBG [Mooncake integration KEP](https://github.com/sgl-project/rbg/blob/main/keps/74-mooncake-integration/README.md).
+
+## Production Mooncake Cluster Example
+
+A production Mooncake cluster on RBG (`workloads.x-k8s.io/v1alpha1`): a Mooncake **Store** (one `master` plus NUMA-split `store` pods) and SGLang **prefill/decode** engines, all over RDMA. The two RBGs below are the Mooncake-side backend; a router/gateway (out of scope for this page) fronts the prefill/decode endpoints to make the P/D deployment servable — see the [overview](index) and the [Prefill/Decode Disaggregation quick start](../../getting_started/examples/sglang-integration/hicache-quick-start.md).
+
+```{note}
+The inline manifests below target `workloads.x-k8s.io/v1alpha1`. For the latest
+API version `v1alpha2`, please refer to the upstream examples linked under
+[RBG example](#rbg-example) above.
+```
+
+| Group | Roles | Purpose |
+|---|---|---|
+| Store (`qwen3-0`) | `master`, `store-1000gb` | Mooncake Store — the master coordinator plus NUMA-split store pods contributing the DRAM KV pool |
+| Workers (`sglang-workers-0`) | `prefill`, `decode` | SGLang engines: `prefill` is a Store/HiCache client **and** P/D transfer; `decode` does P/D transfer only |
+
+```{caution}
+These manifests are sanitized **excerpts** that show the structure and the Mooncake wiring — they cannot be applied directly. The `decode` role and the second NUMA store container are abbreviated to comments, and image / paths / devices are `<…>` placeholders. Fill them in against your own cluster before applying.
+```
+
+### 1. Store group — master + NUMA store
+
+The Store `RoleBasedGroup` has a `master` (the Store coordinator) and a `store-` role whose pods each run two NUMA-pinned store processes. The RBG operator creates a Service `s-qwen3-0-master` for the master role, so clients reach it at `s-qwen3-0-master:50051` — no Service object of your own. Node scheduling uses custom `kvcache.ai/master` and `kvcache.ai/store` labels so a node belongs to exactly one role/size.
+
+```yaml
+apiVersion: workloads.x-k8s.io/v1alpha1
+kind: RoleBasedGroup
+metadata:
+ name: qwen3-0
+ namespace: default
+ labels: { app.kubernetes.io/part-of: mooncake }
+spec:
+ roles:
+ - name: master
+ replicas: 1
+ template:
+ metadata:
+ labels: { role: master, app.kubernetes.io/instance: qwen3-0 }
+ spec:
+ affinity:
+ nodeAffinity:
+ requiredDuringSchedulingIgnoredDuringExecution:
+ nodeSelectorTerms:
+ - matchExpressions:
+ - { key: kvcache.ai/master, operator: In, values: [qwen3_0_master] }
+ containers:
+ - name: master
+ image:
+ command:
+ - sh
+ - -c
+ - |
+ ulimit -n 1048576
+ ulimit -l unlimited
+ mooncake_master \
+ --rpc_address=$(POD_IP) \
+ --rpc_port=50051 \
+ --eviction_high_watermark_ratio=0.9 \
+ --default_kv_lease_ttl=10000
+ env:
+ - { name: POD_IP, valueFrom: { fieldRef: { fieldPath: status.podIP } } }
+ - { name: NVIDIA_VISIBLE_DEVICES, value: "void" } # master needs no GPU
+ securityContext:
+ # master is an RPC coordinator with no RDMA data path — it does not need
+ # `privileged`. IPC_LOCK/SYS_RESOURCE cover the `ulimit -l unlimited` / mlock above.
+ privileged: false
+ capabilities: { add: ["IPC_LOCK", "SYS_RESOURCE"] }
+ livenessProbe:
+ exec: { command: ["/bin/sh", "-c", "pgrep -x mooncake_master >/dev/null"] }
+ initialDelaySeconds: 20
+ periodSeconds: 15
+ ports:
+ - { containerPort: 50051, name: http }
+ - { containerPort: 9003, name: metrics }
+ workload: { apiVersion: apps/v1, kind: StatefulSet }
+
+ - name: store-1000gb
+ replicas: 3
+ template:
+ metadata:
+ labels:
+ role: store-1000gb
+ app.kubernetes.io/instance: qwen3-0
+ app.kubernetes.io/part-of: mooncake
+ spec:
+ affinity:
+ nodeAffinity:
+ requiredDuringSchedulingIgnoredDuringExecution:
+ nodeSelectorTerms:
+ - matchExpressions:
+ - { key: kvcache.ai/store, operator: In, values: [qwen3_0_store-1000gb] }
+ podAntiAffinity: # at most one store pod per node across sizes
+ requiredDuringSchedulingIgnoredDuringExecution:
+ - labelSelector:
+ matchExpressions:
+ - { key: app.kubernetes.io/part-of, operator: In, values: [mooncake] }
+ - { key: app.kubernetes.io/instance, operator: In, values: [qwen3-0] }
+ topologyKey: kubernetes.io/hostname
+ hostNetwork: true # RDMA
+ dnsPolicy: ClusterFirstWithHostNet
+ containers:
+ - name: store-numa0
+ image:
+ command:
+ - sh
+ - -c
+ - |
+ ulimit -n 1048576
+ ulimit -l unlimited
+ exec numactl --cpunodebind=0 --membind=0 python3 -m mooncake.mooncake_store_service --port=8099
+ env:
+ - { name: MOONCAKE_LOCAL_HOSTNAME, valueFrom: { fieldRef: { fieldPath: status.podIP } } }
+ - { name: MOONCAKE_MASTER, value: "s-qwen3-0-master:50051" }
+ - { name: MOONCAKE_TE_META_DATA_SERVER, value: "P2PHANDSHAKE" }
+ - { name: MOONCAKE_GLOBAL_SEGMENT_SIZE, value: "1000gb" } # DRAM this store contributes
+ - { name: MOONCAKE_LOCAL_BUFFER_SIZE, value: "67108864" }
+ - { name: MOONCAKE_PROTOCOL, value: "rdma" }
+ - { name: MOONCAKE_DEVICE, value: "" }
+ - { name: MC_ENABLE_DEST_DEVICE_AFFINITY, value: "1" }
+ # pin the client metrics HTTP server per container (numa0=9300 / numa1=9301);
+ # under hostNetwork two processes cannot share 9300.
+ - { name: MOONCAKE_ENABLE_CLIENT_HTTP_SERVER, value: "true" }
+ - { name: MOONCAKE_CLIENT_HTTP_PORT, value: "9300" }
+ ports: [{ containerPort: 8099 }]
+ startupProbe:
+ exec: { command: ["sh", "-c", "nc -z 127.0.0.1 8099"] }
+ periodSeconds: 10
+ failureThreshold: 90
+ livenessProbe:
+ exec: { command: ["sh", "-c", "nc -z 127.0.0.1 8099"] }
+ initialDelaySeconds: 10
+ periodSeconds: 10
+ securityContext:
+ # least-privilege RDMA: no `privileged` needed — IPC_LOCK/SYS_RESOURCE plus
+ # the /dev/infiniband device mount below are enough for the Transfer Engine NICs.
+ privileged: false
+ capabilities: { add: ["IPC_LOCK", "SYS_RESOURCE"] }
+ volumeMounts:
+ - { mountPath: /dev/infiniband, name: ib }
+ # store-numa1: identical, but `numactl --cpunodebind=1 --membind=1`, --port=8100,
+ # containerPort 8100, and MOONCAKE_CLIENT_HTTP_PORT=9301.
+ volumes:
+ - { name: ib, hostPath: { path: /dev/infiniband, type: DirectoryOrCreate } }
+ workload: { apiVersion: apps/v1, kind: StatefulSet }
+```
+
+### 2. Inference workers — prefill + decode
+
+`sglang-workers-0` runs the SGLang PD engines, and the two roles are wired **differently**:
+
+- **`prefill`** is the Store/HiCache client. It sets `MOONCAKE_MASTER=s-qwen3-0-master:50051` (the Store master), `MOONCAKE_TE_META_DATA_SERVER=P2PHANDSHAKE` (the Transfer Engine coordinates P/D directly, no metadata server), `MOONCAKE_PROTOCOL=rdma` + `MOONCAKE_DEVICE`, and `MOONCAKE_GLOBAL_SEGMENT_SIZE=0` (a **pure client** — it contributes no DRAM; the store pods do). It launches with `--enable-hierarchical-cache --hicache-storage-backend mooncake`. The prefill manifest is shown below.
+- **`decode`** only participates in the P/D Transfer Engine — `--disaggregation-mode decode --disaggregation-ib-device`. It is **not** a Store/HiCache client: it sets no `MOONCAKE_MASTER` and enables no hierarchical cache.
+
+```yaml
+apiVersion: workloads.x-k8s.io/v1alpha1
+kind: RoleBasedGroup
+metadata:
+ name: sglang-workers-0
+ namespace: default
+spec:
+ roles:
+ - name: prefill
+ replicas: 4
+ template:
+ metadata:
+ labels:
+ app: sglang-worker
+ rolebasedgroup.workloads.x-k8s.io/name: sglang-workers-0
+ rolebasedgroup.workloads.x-k8s.io/role: prefill
+ spec:
+ hostNetwork: true # RDMA
+ dnsPolicy: ClusterFirstWithHostNet
+ nodeSelector: { deployment: sglang_0_prefill }
+ containers:
+ - name: sglang-prefill
+ image:
+ command:
+ - bash
+ - -c
+ - |
+ set -e
+ ulimit -n 1048576; ulimit -l unlimited
+ python -m sglang.launch_server \
+ --model ${MODEL_PATH} --served-model-name Qwen3-0.6B \
+ --host 0.0.0.0 --port 8000 \
+ --disaggregation-mode prefill \
+ --disaggregation-ib-device $IB_DEVICE_LIST \
+ --enable-hierarchical-cache --hicache-storage-backend mooncake \
+ --tp 8 --page-size 64 --trust-remote-code \
+ --enable-metrics --enable-cache-report
+ # … model/hardware tuning flags omitted (context length, mem fraction,
+ # NSA backends, EAGLE speculative decoding, KV-cache dtype, etc.)
+ env:
+ # --- pod identity ---
+ - { name: POD_NAME, valueFrom: { fieldRef: { fieldPath: metadata.name } } }
+ - { name: POD_IP, valueFrom: { fieldRef: { fieldPath: status.podIP } } }
+ - { name: MOONCAKE_LOCAL_HOSTNAME, valueFrom: { fieldRef: { fieldPath: status.podIP } } }
+ - { name: SGLANG_HOST_IP, valueFrom: { fieldRef: { fieldPath: status.podIP } } }
+ # --- model + fabric ---
+ - { name: MODEL_PATH, value: /models/Qwen3-0.6B }
+ - { name: IB_DEVICE_LIST, value: "" }
+ # --- Mooncake wiring ---
+ - { name: MOONCAKE_TE_META_DATA_SERVER, value: P2PHANDSHAKE }
+ - { name: MOONCAKE_MASTER, value: "s-qwen3-0-master:50051" } # the Store group's master
+ - { name: MOONCAKE_PROTOCOL, value: rdma }
+ - { name: MOONCAKE_DEVICE, value: "" }
+ - { name: MOONCAKE_GLOBAL_SEGMENT_SIZE, value: "0" } # pure client, contributes no DRAM
+ - { name: MC_TE_METRIC, value: "true" }
+ # … SGLANG_* / MC_* performance tuning omitted (heartbeat, timeouts,
+ # spec-decoding v2, auto-empty-cache, NCCL, JIT, CPU affinity, PRC port range) …
+ ports:
+ - { containerPort: 8000, name: http }
+ - { containerPort: 8998, name: bootstrap }
+ readinessProbe:
+ tcpSocket: { port: 8000 }
+ initialDelaySeconds: 30
+ periodSeconds: 10
+ resources:
+ limits: { nvidia.com/gpu: "8" }
+ requests: { nvidia.com/gpu: "8" }
+ securityContext:
+ # least-privilege RDMA: no `privileged` needed — IPC_LOCK/SYS_RESOURCE plus
+ # the /dev/infiniband device mount below are enough for the NICs.
+ privileged: false
+ capabilities: { add: ["IPC_LOCK", "SYS_RESOURCE"] }
+ volumeMounts:
+ - { mountPath: /models, name: model }
+ - { mountPath: /dev/shm, name: dshm }
+ - { mountPath: /dev/infiniband, name: ib }
+ volumes:
+ - { name: model, hostPath: { path: , type: DirectoryOrCreate } }
+ - { name: dshm, emptyDir: { medium: Memory, sizeLimit: 1300Gi } }
+ - { name: ib, hostPath: { path: /dev/infiniband, type: DirectoryOrCreate } }
+ workload: { apiVersion: apps/v1, kind: StatefulSet }
+
+ - name: decode
+ replicas: 1
+ # Abbreviated excerpt — a real decode PodSpec mirrors the prefill container EXCEPT:
+ # launch: --disaggregation-mode decode --disaggregation-ib-device $IB_DEVICE_LIST
+ # (NO --enable-hierarchical-cache / --hicache-storage-backend — decode is
+ # not a Store client), plus DP/EP attention, low-latency deepep, etc.
+ # env: NO MOONCAKE_MASTER / MOONCAKE_GLOBAL_SEGMENT_SIZE / hierarchical cache;
+ # keeps POD_NAME / POD_IP / MODEL_PATH / IB_DEVICE_LIST (P/D transfer only)
+ # sched: nodeSelector deployment: sglang_0_decode ; dshm sizeLimit 15Gi
+ template: { } # fill in a real PodSpec to deploy
+ workload: { apiVersion: apps/v1, kind: StatefulSet }
+```
+
+### Mooncake integration points (recap)
+
+- **Store master** — `mooncake_master --rpc_address=$(POD_IP) --rpc_port=50051 …`; the RBG operator exposes it as `s-qwen3-0-master`, and its clients (the store pods and the **prefill** engine) set `MOONCAKE_MASTER=s-qwen3-0-master:50051`.
+- **Only prefill is a Store client** — `prefill` enables HiCache (`--enable-hierarchical-cache --hicache-storage-backend mooncake`) and connects to the master; `decode` participates only in the P/D Transfer Engine and connects to no Store.
+- **Transfer Engine uses P2P handshake** — `prefill` sets `MOONCAKE_TE_META_DATA_SERVER=P2PHANDSHAKE`; the TE side-channel coordinates prefill↔decode directly, so there is no HTTP metadata server here (unlike the [main guide](index)).
+- **Store vs client segment size** — store pods set `MOONCAKE_GLOBAL_SEGMENT_SIZE=1000gb` (they own the DRAM pool); the prefill client sets `0` (contributes no DRAM, only `Get`/`Put`).
+- **RDMA fabric** — `MOONCAKE_PROTOCOL=rdma` + `MOONCAKE_DEVICE=`, `hostNetwork: true`, `/dev/infiniband` mounted, and the `IPC_LOCK`/`SYS_RESOURCE` capabilities (no `privileged` needed — a `/dev/infiniband` hostPath mount plus those two capabilities is the least-privilege way to reach the NICs; an RDMA device plugin is an alternative).
+- **NUMA split** — each store pod runs two `mooncake_store_service` processes, each `numactl`-pinned to one NUMA node with its own port and client-metrics port.
+
+(placeholders)=
+### Placeholders
+
+The example values above (`qwen3-0`, `default`, `store-1000gb`, replica counts) are yours to change. The `<…>` placeholders are:
+
+| Placeholder | Replace with |
+|---|---|
+| `` | the container image (`registry/name:tag`) for this role |
+| `` | host directory holding the model weights |
+| `` | your RDMA NIC list (e.g. `mlx5_0,mlx5_1,…`) |
diff --git a/docs/source/deployment/mooncake-store-deployment-guide.md b/docs/source/deployment/mooncake-store-deployment-guide.md
index 5333d7d3b2..653c3b373d 100644
--- a/docs/source/deployment/mooncake-store-deployment-guide.md
+++ b/docs/source/deployment/mooncake-store-deployment-guide.md
@@ -199,11 +199,12 @@ mooncake_master \
--offload_on_evict=true \
--promotion_on_hit=true \
--promotion_admission_threshold=2 \
- --root_fs_dir=/mnt/ssd_cache \
--enable_http_metadata_server=true \
--http_metadata_server_port=8080
```
+Do not set `--root_fs_dir` with `--enable_offload=true`. `--root_fs_dir` is a legacy parameter from an older persistence path and may cause issues on the SSD offload path. Configure each real client's offload directory with `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH` instead.
+
---
### CXL-Aware Allocation — Memory Tiering
@@ -278,7 +279,17 @@ mooncake_master \
--tenant_quota_connector_uri=/etc/mooncake/tenant_quotas.yaml
```
-The v1 connector is a writable YAML file. The file must use schema version `1`; tenant names must be non-empty, unique, must not start with `_`, and must not contain NUL or control characters; quotas must be positive integers with optional `B`, `KB`, `MB`, `GB`, or `TB` units:
+You can also store the same YAML policy in etcd when Mooncake Store is built with `STORE_USE_ETCD=ON`:
+
+```bash
+mooncake_master \
+ --enable_multi_tenants=true \
+ --cluster_id=mooncake_cluster \
+ --tenant_quota_connector_type=etcd \
+ --tenant_quota_connector_uri=127.0.0.1:2379
+```
+
+The etcd connector stores the policy at `mooncake-store//tenant_quota_policy`. If the key does not exist, the master starts with an empty policy so the first tenant policy can be created through the admin API. It shares the process-wide store etcd client used by HA/oplog, so if HA or oplog also uses etcd, `tenant_quota_connector_uri` must match those etcd endpoints. The policy must use schema version `1`; tenant names must be non-empty, unique, must not start with `_`, and must not contain NUL or control characters; quotas must be positive integers with optional `B`, `KB`, `MB`, `GB`, or `TB` units:
```yaml
version: 1
@@ -475,8 +486,8 @@ mooncake_master \
| Flag | Default | Description |
|------|---------|-------------|
| `--enable_multi_tenants` | `false` | Enable strict tenant registration and per-tenant memory quota admission |
-| `--tenant_quota_connector_type` | `file` | Tenant quota policy connector type |
-| `--tenant_quota_connector_uri` | empty | Connector URI; for `file`, the writable YAML policy path |
+| `--tenant_quota_connector_type` | `file` | Tenant quota policy connector type: `file` or `etcd` when built with `STORE_USE_ETCD=ON` |
+| `--tenant_quota_connector_uri` | empty | Connector URI; for `file`, the writable YAML policy path; for `etcd`, the endpoints string |
### High Availability
@@ -544,6 +555,8 @@ Flags for controlling data movement between DRAM and SSD.
Start with `--enable_offload=true` for eager asynchronous SSD persistence after `Put` completion. Add `--offload_on_evict=true` when you want SSD writes to happen only when memory pressure selects an object for eviction. Add `--promotion_on_hit=true` to allow hot SSD-only data to be promoted back to DRAM, and tune `--promotion_admission_threshold` to control how many observed reads are required before promotion is queued.
+For SSD offload, configure the disk path on each real client with `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH`; the master tracks these objects as `LOCAL_DISK` replicas. Do not use the legacy `--root_fs_dir` parameter with `--enable_offload=true`.
+
When `--offload_on_evict=true` is active, each `BatchEvict` cycle can queue at most `offloading_queue_limit * offload_cap_ratio` objects for SSD offload (default: `50000 * 0.5 = 25000`); objects exceeding this cap fall back to force-evict (discard) if `--offload_force_evict=true`, otherwise they remain in memory. For SSD-heavy workloads where NVMe bandwidth is underutilized while the KV-cache hit rate suffers, raise both `--offloading_queue_limit` and `--offload_cap_ratio` so more objects per cycle are actually persisted to SSD instead of discarded. Example: `--offloading_queue_limit=500000 --offload_cap_ratio=0.8` yields a per-cycle cap of `400000` (vs the default `25000`).
### CXL Memory
@@ -560,9 +573,11 @@ When `--allocation_strategy=cxl` is set alongside `--enable_cxl=true`, the maste
| Flag | Default | Description |
|------|---------|-------------|
-| `--root_fs_dir` | empty | DFS mount directory for multi-layer storage backend |
+| `--root_fs_dir` | empty | Legacy DFS persistence directory; do not use with SSD offload |
| `--global_file_segment_size` | `INT64_MAX` (unlimited) | Max available space for DFS segments; default does not cap DFS usage |
+`--root_fs_dir` is a legacy persistence parameter and is expected to be replaced as the distributed filesystem path is refactored. For SSD offload, configure `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH` on each real client instead.
+
### NoF (NVMe-oF SSD Pool)
```{caution}
@@ -637,9 +652,11 @@ Arguments of `MooncakeDistributedStore.setup(...)`:
| `enable_ssd_offload` | bool | `false` | *(advanced)* Enable client-side SSD offload |
| `ssd_offload_path` | str | empty | *(advanced)* SSD offload directory |
| `tenant_id` | str | `default` | *(advanced)* Tenant identifier |
+| `enable_client_http_server` | bool | `false` | Enable the client-side HTTP `/health`, `/metrics`, and `/metrics/summary` endpoints |
+| `client_http_port` | int | `9300` | Client-side HTTP endpoint port, used only when `enable_client_http_server=true` |
```{note}
-The first seven arguments have **no Python default** — the C++ defaults are not exposed by the pybind binding, so they must all be supplied (a bare `setup(local_hostname, metadata_server)` raises `TypeError`). Only `engine` / `enable_ssd_offload` / `ssd_offload_path` / `tenant_id` are optional. Also, in Method A the `MOONCAKE_*` variables used by `MooncakeConfig` are ignored; low-level runtime variables such as the `MC_*` engine variables below are still read by the C++ client.
+The first seven arguments have **no Python default** — the C++ defaults are not exposed by the pybind binding, so they must all be supplied (a bare `setup(local_hostname, metadata_server)` raises `TypeError`). The later arguments (`engine`, SSD offload fields, `tenant_id`, and client HTTP endpoint fields) are optional. Also, in Method A the `MOONCAKE_*` variables used by `MooncakeConfig` are ignored; low-level runtime variables such as the `MC_*` engine variables below are still read by the C++ client.
```
### Method B — Service / Integration (`MOONCAKE_*` + CLI)
@@ -665,6 +682,9 @@ The store service CLI only accepts `--config`, `-D/--define`, `--port`, and `--m
| `MOONCAKE_LOCAL_HOSTNAME` | `local_hostname` | `localhost` | |
| `MOONCAKE_OFFLOAD_ENABLED` | `enable_ssd_offload` | `false` | Client-side SSD offload |
| `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH` | `ssd_offload_path` | empty | Offload directory |
+| `MOONCAKE_TENANT_ID` | `tenant_id` | `default` | Tenant identifier |
+| `MOONCAKE_ENABLE_CLIENT_HTTP_SERVER` | `enable_client_http_server` | `false` | Enable client-side `/health`, `/metrics`, and `/metrics/summary` endpoints |
+| `MOONCAKE_CLIENT_HTTP_PORT` | `client_http_port` | `9300` | Client-side HTTP endpoint port |
| `MOONCAKE_CONFIG_PATH` | — | unset | Path to a JSON config file (takes precedence over the variables above) |
```{note}
@@ -695,12 +715,16 @@ Or via a JSON config file. The service also exposes a lightweight HTTP API (on `
"local_buffer_size": 268435456,
"protocol": "tcp",
"device_name": "",
- "master_server_address": "127.0.0.1:50051"
+ "master_server_address": "127.0.0.1:50051",
+ "tenant_id": "default",
+ "enable_client_http_server": false,
+ "client_http_port": 9300
}
```
```bash
python -m mooncake.mooncake_store_service --config= --port=8081
+python -m mooncake.mooncake_store_service --config= -Dtenant_id=tenant-a
```
### Method C — Resource-owning Real Client (`mooncake_client`)
@@ -711,21 +735,55 @@ Run the `mooncake_client` binary as a standalone RPC process that owns storage r
mooncake_client \
--global_segment_size="4GB" \
--master_server_address="127.0.0.1:50051" \
- --metadata_server="http://127.0.0.1:8080/metadata"
+ --metadata_server="http://127.0.0.1:8080/metadata" \
+ --tenant_id="default"
```
| Flag | Default | Description |
|------|---------|-------------|
-| `--host` | `0.0.0.0` | Client service bind host |
-| `--port` | `50052` | Client service listen port |
+| `--host` | `0.0.0.0` | Client service bind host. Accepts `ip:port` to specify the data plane port for TransferEngine |
+| `--port` | `50052` | Client RPC listen port (dummy↔real client control plane) |
| `--global_segment_size` | `4 GB` | Global segment size contributed by the client |
| `--master_server_address` | `127.0.0.1:50051` | Master service address |
| `--metadata_server` | `http://127.0.0.1:8080/metadata` | Transfer Engine metadata service |
| `--protocol` | `tcp` | Transfer protocol |
| `--device_names` | empty | Transfer device name(s), comma-separated |
| `--threads` | `1` | Client worker thread count |
+| `--tenant_id` | `default` | Tenant identifier |
| `--enable_offload` | `false` | Enable client-side SSD offload |
| `--start_offload_rpc_server` | `true` | Start the offload RPC server for dummy clients |
+| `--enable_http_server` | `false` | Enable client-side `/health`, `/metrics`, and `/metrics/summary` endpoints |
+| `--http_port` | `9300` | Client-side HTTP endpoint port |
+
+### Client HTTP Health and Metrics Endpoint
+
+Each real client can expose its own lightweight HTTP endpoint independently of the master admin HTTP server and the Python store REST API. This endpoint is disabled by default for programmatic clients and `mooncake_store_service`; enable it explicitly when you want to scrape client-local metrics:
+
+```python
+store.setup(
+ local_hostname,
+ metadata_server,
+ global_segment_size,
+ local_buffer_size,
+ protocol,
+ rdma_devices,
+ master_server_addr,
+ enable_client_http_server=True,
+ client_http_port=9300,
+)
+```
+
+For `mooncake_store_service`, use `MOONCAKE_ENABLE_CLIENT_HTTP_SERVER=true` and optionally `MOONCAKE_CLIENT_HTTP_PORT=`, or set the same fields in the JSON config. For `mooncake_client`, use `--enable_http_server=true --http_port=`.
+
+| Endpoint | Description |
+|----------|-------------|
+| `GET /health` | Client health check |
+| `GET /metrics` | Prometheus-format client metrics |
+| `GET /metrics/summary` | Human-readable client metrics summary |
+
+```{note}
+`MC_STORE_CLIENT_METRIC` controls whether client metrics are collected. If the client HTTP server is enabled but `MC_STORE_CLIENT_METRIC=0`, `/metrics` and `/metrics/summary` return HTTP 503 with `metrics not available`.
+```
### Engine Runtime Tuning (`MC_*`)
@@ -794,6 +852,21 @@ Local hot cache provides a DRAM read cache on top of SSD-resident objects for fa
| `MC_MMAP_ARENA_POOL_SIZE` | unset | Pre-allocated arena pool size (e.g., `8gb`). Explicitly set to enable the arena |
| `MC_DISABLE_MMAP_ARENA` | unset | Disable arena, fall back to per-call `mmap()`. Accepts `1`/`true`/`yes`/`on` (or `0`/`false`/`no`/`off`) |
+RDMA Store segments backed by HugeTLB are populated in parallel immediately
+before transfer-engine registration. No additional population-mode setting is
+required:
+
+```bash
+export MC_STORE_USE_HUGEPAGE=1
+export MC_STORE_HUGEPAGE_SIZE=2MB
+```
+
+For direct mappings, workers divide the mapping into page ranges. For
+NUMA-segmented mappings, each worker is scheduled on the NUMA node associated
+with its `mbind()` region before touching pages. The mmap arena retains its
+eager `MAP_POPULATE` behavior for DMA safety; set `MC_DISABLE_MMAP_ARENA=1` if
+the deferred direct-mmap path is desired while the arena is otherwise enabled.
+
#### yalantinglibs Log Level
```bash
diff --git a/docs/source/deployment/ssd-offload.md b/docs/source/deployment/ssd-offload.md
index 439f5f29b5..edf58f7008 100644
--- a/docs/source/deployment/ssd-offload.md
+++ b/docs/source/deployment/ssd-offload.md
@@ -2,9 +2,9 @@
## Overview
-Mooncake Store supports offloading KV cache objects from distributed memory to local SSD. When memory pressure is high, the master instructs clients to persist selected objects to disk. On a cache miss, the client automatically falls back to reading from SSD.
+Mooncake Store supports offloading KV cache objects from distributed memory to a local filesystem path, typically backed by local SSDs. When memory pressure is high, the master instructs clients to persist selected objects to disk. On a cache miss, the client automatically falls back to reading from the local filesystem-backed offload path.
-For measured TTFT and throughput impact in multi-turn workloads, see [Mooncake SSD Offload Benchmark](../performance/ssd-offload-benchmark-results.md).
+For measured TTFT and throughput impact in multi-turn workloads, see [Mooncake SSD Offload Benchmark](../performance/mooncake/ssd-offload-benchmark-results.md).
SSD offload requires the **Real Client** and supports two deployment modes:
@@ -13,6 +13,8 @@ SSD offload requires the **Real Client** and supports two deployment modes:
In both modes, all SSD reads and writes happen within the Real Client (embedded or standalone).
+SSD offload does not use the master's `--root_fs_dir` option. Configure the local disk path on each Real Client with `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH`; the master tracks offloaded objects as `LOCAL_DISK` replicas. `--root_fs_dir` is a legacy parameter from an older persistence path and may cause issues when used with `--enable_offload=true`.
+
## Startup Steps
### Step 1: Create the SSD storage directory
@@ -92,7 +94,7 @@ store.setup_dummy(
|------|---------|-------------|
| `--metadata_server` | `http://127.0.0.1:8080/metadata` | Metadata server connection string |
| `--master_server_address` | `127.0.0.1:50051` | Master address |
-| `--host` | `0.0.0.0` | This machine's externally reachable IP |
+| `--host` | `0.0.0.0` | This machine's externally reachable IP. Accepts `ip:port` to specify the data plane port for TransferEngine |
| `--port` | `50052` | Real client RPC listening port |
| `--device_names` | ` ` | NIC name(s), e.g. `eth0` or `mlx5_0` |
| `--protocol` | `tcp` | Transport protocol: `tcp` or `rdma` |
diff --git a/docs/source/design/conductor/indexer-api-design.md b/docs/source/design/conductor/indexer-api-design.md
index e79367e6cd..c44af602fc 100644
--- a/docs/source/design/conductor/indexer-api-design.md
+++ b/docs/source/design/conductor/indexer-api-design.md
@@ -360,3 +360,133 @@ normalizes `BlockStored` and `BlockRemoved` into the internal prefix index.
Registration metadata supplies fields such as `modelname`, `tenant_id`,
`instance_id`, `block_size`, and `additionalsalt` when the engine event does
not carry the full standardized envelope.
+
+### Mooncake Store master publisher
+
+`mooncake_master` can optionally publish RFC #1527 events when
+`enable_kv_events=true`. The publisher binds a ZMQ PUB socket
+(`kv_events_bind_endpoint`) and emits the same three-frame batch format used by
+vLLM/SGLang: empty topic, big-endian sequence number, and a msgpack payload
+`[timestamp, [events], dp_rank]`.
+
+**Per-block events, not global metadata.** Per the
+[Dynamo KV Events for Custom Engines](https://docs.nvidia.com/dynamo/kv-managers/kv-events-for-custom-engines)
+model, each event describes one or more **KV cache blocks** (`seq_hashes`,
+`token_ids`, `parent_hash`, eviction hashes). The master emits **one event per
+Mooncake object key** on `PutEnd` / `Remove` / eviction — each key is treated as
+one pooled block. Block identity comes from the object key (`seq_hashes` when
+the key is decimal/`0x` u64, else `object_key`) and per-object `tenant_id` /
+`medium`. The master does **not** stamp process-wide `model_name`, `block_size`,
+`lora_name`, or `dp_rank` on events; register those dimensions with the indexer
+via `POST /register` (same as decoupled SGLang + storage pool deployments).
+
+Publisher-level config is limited to transport and stream identity:
+`kv_events_bind_endpoint`, `kv_events_backend_id`, and optional compat flags
+(`kv_events_emit_object_key`, `kv_events_emit_legacy_compat`). Legacy master
+flags such as `kv_events_model_name` are retained for compatibility but are not
+written into event payloads.
+
+Each event map uses RFC #1527 field names (`event_type`, `seq_hashes`,
+`backend_id`, `medium`, and so on). When `kv_events_emit_object_key` is enabled
+(default), the map also includes `object_key` with the Mooncake store key so
+Dynamo and other consumers can match on `sha256` + Mooncake key format without
+requiring decimal/`0x` `seq_hash` encoding. When `kv_events_emit_legacy_compat`
+is enabled (default), the map also includes vLLM-compatible aliases such as
+`type` and `block_hashes` so Dynamo relay mode can forward events without an
+adapter.
+
+Object keys may encode the rolling `seq_hash` as a decimal or `0x`-prefixed
+hex string; when `seq_hash` cannot be parsed, events are still published if
+`kv_events_emit_object_key=true` (with an empty `seq_hashes` array). Configure
+`backend_id` to identify the cache owner (for example a per-node storage
+daemon) and register the bind endpoint with the indexer using publisher type
+`Mooncake`.
+
+### Field provenance matrix (SGLang vs master vs indexer registration)
+
+In decoupled deployments (inference workers + Mooncake host/disk pool), the
+global KV indexer merges **three sources of truth**. Use this table when
+splitting publishers or writing PR/integration notes.
+
+**Legend**
+
+| Symbol | Meaning |
+|---|---|
+| **SGLang** | Inference engine ZMQ KV events (`BlockStored` / `BlockRemoved` / `AllBlocksCleared`) |
+| **Master** | `mooncake_master` optional RFC #1527 publisher (`enable_kv_events`) |
+| **Register** | Indexer HTTP `POST /register` (or CLI `--workers`) — not carried on the event wire |
+| **S+M** | Either source may supply; must agree on value for the stream |
+| **—** | Not applicable for that event type |
+
+#### Envelope and stream identity
+
+| Field | SGLang | Master | Register | Notes |
+|---|---|---|---|---|
+| `event_id` | Yes | Yes | — | Each publisher maintains its own monotonic counter per stream. |
+| `timestamp` | Yes | Yes | — | Informational only; not used for ordering. |
+| `event_type` | Yes | Yes | — | `stored` / `removed` / `cleared`. |
+| `model_name` | S+M | — | S+M | Register uses `modelname`. Engine events carry per-block context; master omits (nil). |
+| `block_size` | Yes | — | Yes | Required for token↔block mapping. Register supplies for master publisher. |
+| `additional_salt` | Yes | — | S+M | Register uses `additionalsalt`. Engine per-block; master omits (nil). |
+| `lora_name` | Yes | — | S+M | Per-block on engine events; master has no adapter context. |
+| `tenant_id` | S+M | Yes | Yes | Per-object on master events. Register default `default`. |
+| `backend_id` | S+M | Yes | — | **Master**: storage daemon / pool owner. **SGLang**: often worker id; in decoupled mode prefer master=`daemon`, engine via **Register** `instance_id`. |
+| `medium` | Yes | Partial | — | **SGLang**: `GPU`, `CPU_PINNED`, `DISK`, `EXTERNAL`, etc. **Master**: only `cpu` / `disk` (host/disk pool), never GPU. |
+| `dp_rank` | Yes | — | Yes | Per-batch on engine ZMQ wire. Master batch trailer uses `0`; register dp_rank with indexer. |
+
+#### `stored` payload
+
+| Field | SGLang | Master | Register | Notes |
+|---|---|---|---|---|
+| `seq_hashes` | Yes | Conditional | — | **Required from SGLang** for correct prefix index. Master: single hash when key is decimal/`0x` u64; empty array when only `object_key` is used. |
+| `object_key` | — | Yes | — | Mooncake store key (`kv_events_emit_object_key`, default on). Used by Dynamo for sha256+key matching. |
+| `block_hashes` (legacy) | Yes | Conditional | — | Alias of `seq_hashes` when `kv_events_emit_legacy_compat` is enabled on master. |
+| `parent_hash` | Yes | — | — | Radix parent link; master has no sequence tree. |
+| `parent_block_hash` (legacy) | Yes | — | — | Same as `parent_hash`. |
+| `base_block_idx` | Yes | Partial | — | Depth of first block in batch; master uses `0` for standalone pool blocks. |
+| `token_ids` | Yes | — | — | Required for `/query` by tokens or hash recomputation when engine is non-standard. |
+| `block_size` (in-event) | Yes | — | — | Per-block token count in SGLang `BlockStored`; master uses envelope-level config only. |
+
+#### `removed` payload
+
+| Field | SGLang | Master | Register | Notes |
+|---|---|---|---|---|
+| `seq_hashes` | Yes | Conditional | — | **Required** on wire for strict RFC consumers. Master emits one hash when parseable, else empty with `object_key`. |
+| `base_block_idx` | Yes | — | — | Optional but recommended for observability. |
+
+#### `cleared` payload
+
+| Field | SGLang | Master | Register | Notes |
+|---|---|---|---|---|
+| (no extra fields) | — | — | — | Event is envelope-only. |
+| `cleared` / `AllBlocksCleared` | Yes | — | — | Engine `reset()` / full cache flush. Master does not emit today. |
+
+#### Indexer / router plane (not in KV event JSON)
+
+| Field | SGLang | Master | Register | Notes |
+|---|---|---|---|---|
+| `instance_id` | — | — | Yes | Router-facing schedule target. Distinct from `backend_id`. |
+| `endpoint` | — | — | Yes | ZMQ PUB to subscribe (SGLang or master bind address). |
+| `replay_endpoint` | — | — | Yes | Optional gap replay (engine ROUTER). |
+| `type` | — | — | Yes | Publisher kind: `vLLM`, `SGLang`, `Mooncake`, etc. |
+
+#### Recommended split for Dynamo global KV indexer
+
+```mermaid
+flowchart LR
+ SGLang["SGLang ZMQ"]
+ Master["Mooncake master ZMQ"]
+ Reg["POST /register"]
+ Idx["Global KV indexer"]
+
+ SGLang -->|"GPU + HiCache tiers
tokens, parent_hash, seq_hashes, lora"| Idx
+ Master -->|"Host/Disk pool
backend_id, medium=cpu|disk"| Idx
+ Reg -->|"instance_id, model, block_size"| Idx
+```
+
+| Capability | Primary source |
+|---|---|
+| GPU prefix hits, LoRA-aware hashes, parent chain, multi-block batches | **SGLang** |
+| Pooled host/disk replica visibility | **Master** (if keys encode `seq_hash`) |
+| Request routing target | **Register** (`instance_id`) |
+| Tiered `/query` response (`gpu` / `cpu` / `disk`) | Merge **SGLang** + **Master** events (see RFC #1403) |
diff --git a/docs/source/design/hicache-design.md b/docs/source/design/hicache-design.md
index db2dfa2b2e..a2a301e869 100644
--- a/docs/source/design/hicache-design.md
+++ b/docs/source/design/hicache-design.md
@@ -2,7 +2,7 @@
With the rapid development of tasks such as Agentic Coding, the length of request contexts continues to grow. Increasing the capacity of the KV Cache to improve its hit rate has become increasingly important for enhancing throughput and reducing TTFT. In this context, SGLang introduces **HiCache**, which extends the original RadixAttention (previously limited to GPU memory) by adding hierarchical caching support and integrating with distributed storage backends such as Mooncake.
-Inspired by the classic three-level cache design of modern CPUs, HiCache organizes GPU memory as L1, host memory as L2, and distributed storage as L3. This hierarchy enables HiCache to fully exploit the "idle" storage space of GPUs and CPUs, while integrating distributed cache systems for global KV cache storage and scheduling. As a result, HiCache significantly expands KV cache capacity while maintaining strong read performance, especially in workloads such as multi-QA and long-context inference, where KV cache reuse is frequent. For detailed benchmark results, see [this document](https://kvcache-ai.github.io/Mooncake/performance/sglang-hicache-benchmark-results-v1.html).
+Inspired by the classic three-level cache design of modern CPUs, HiCache organizes GPU memory as L1, host memory as L2, and distributed storage as L3. This hierarchy enables HiCache to fully exploit the "idle" storage space of GPUs and CPUs, while integrating distributed cache systems for global KV cache storage and scheduling. As a result, HiCache significantly expands KV cache capacity while maintaining strong read performance, especially in workloads such as multi-QA and long-context inference, where KV cache reuse is frequent. For detailed benchmark results, see [this document](https://kvcache-ai.github.io/Mooncake/performance/sglang/sglang-hicache-benchmark-results-v1.html).
While HiCache supports multiple L3 backends, this document focuses primarily on the **Mooncake** backend.
@@ -115,7 +115,7 @@ Furthermore, **Mooncake** supports efficient batch read and write operations and
## Integration with PD-Disaggregation Deployment Mode
-SGLang supports a PD (Prefill-Decode) disaggregation deployment mode through the **Mooncake TransferEngine** (for details, see [this document](https://docs.sglang.ai/advanced_features/pd_disaggregation.html)).
+SGLang supports a PD (Prefill-Decode) disaggregation deployment mode through the **Mooncake TransferEngine** (for details, see [this document](https://docs.sglang.ai/advanced_features/pd_disaggregation.html)).
In the PD-disaggregation deployment mode, HiCache can be enabled on the Prefill nodes to optimize prefill performance. With the hierarchical caching mechanism provided by **HiCache + Mooncake Store**, prefill nodes can handle long-context and multi-turn dialogue scenarios more efficiently, significantly improving performance during the prefill phase. HiCache can also be enabled on the decode nodes to write computation results back to L3.
diff --git a/docs/source/design/mooncake-store.md b/docs/source/design/mooncake-store.md
index 4ebe9751af..bb34a1ad34 100644
--- a/docs/source/design/mooncake-store.md
+++ b/docs/source/design/mooncake-store.md
@@ -95,7 +95,7 @@ To reduce cache warm-up time after a master restart, the Master Service supports
The Master Service can optionally enforce strict multi-tenant memory quota admission. This feature is disabled by default. When `enable_multi_tenants=false`, request tenant IDs are ignored for object placement, all objects use the `default` namespace, and tenant quota management requests return `UNAVAILABLE_IN_CURRENT_MODE`.
-When strict multi-tenant mode is enabled, the tenant quota policy is loaded from the configured connector. The v1 connector is a writable YAML file configured by `tenant_quota_connector_type=file` and `tenant_quota_connector_uri=`. Tenants must be explicitly present in that connector policy before they can write. Missing tenants, empty tenants, and an unregistered `default` tenant are rejected with `TENANT_NOT_REGISTERED`.
+When strict multi-tenant mode is enabled, the tenant quota policy is loaded from the configured connector. Supported connector types are `file` and, when the store is built with `STORE_USE_ETCD=ON`, `etcd`. The `file` connector uses `tenant_quota_connector_uri=` as a writable YAML policy path. The `etcd` connector uses `tenant_quota_connector_uri=` as the etcd endpoints string and stores the same YAML policy in `mooncake-store//tenant_quota_policy`; if that key does not exist, the master starts with an empty policy so the first policy can be created through the admin API. The etcd connector shares the process-wide store etcd client used by HA/oplog, so deployments that enable both must configure matching etcd endpoints. Tenants must be explicitly present in that connector policy before they can write. Missing tenants, empty tenants, and an unregistered `default` tenant are rejected with `TENANT_NOT_REGISTERED`.
The YAML policy uses schema version `1`:
@@ -494,7 +494,7 @@ Mooncake Store provides two concrete implementations of `BufferAllocatorBase`:
**OffsetBufferAllocator (default and recommended)**: This allocator is derived from [OffsetAllocator](https://github.com/sebbbi/OffsetAllocator), which uses a custom bin-based allocation strategy that supports fast hard realtime `O(1)` offset allocation with minimal fragmentation. Mooncake Store optimizes this allocator based on the specific memory usage characteristics of LLM inference workloads, thereby enhancing memory utilization in LLM scenarios.
-For measured utilization and allocation latency across LLM-style workloads, see [Allocator Performance](../performance/allocator-benchmark-result.md).
+For measured utilization and allocation latency across LLM-style workloads, see [Allocator Performance](../performance/mooncake/allocator-benchmark-result.md).
**CachelibBufferAllocator (deprecated)**: This allocator leverages Facebook's [CacheLib](https://github.com/facebook/CacheLib) to manage memory using a slab-based allocation strategy. It provides efficient memory allocation with good fragmentation resistance and is well-suited for high-performance scenarios. However, in our modified version, it does not handle workloads with highly variable object sizes effectively, so it is currently marked as deprecated.
@@ -588,7 +588,7 @@ Valid values are: `random` (default), `free_ratio_first`, `ssd_free_ratio_first`
**Use `local_first`** when inference workers and Mooncake Store memory segments are colocated and you want writes to prefer the writer's host before falling back to other hosts. For this strategy to work correctly, all writer and store processes on the same physical or logical host must use the same stable, globally unique host part in `local_hostname`.
-For benchmark data comparing `random` and `free_ratio_first` across segment counts, replica counts, and skewed capacities, see [AllocationStrategy Performance](../performance/allocation-strategy-benchmark-result.md).
+For benchmark data comparing `random` and `free_ratio_first` across segment counts, replica counts, and skewed capacities, see [AllocationStrategy Performance](../performance/mooncake/allocation-strategy-benchmark-result.md).
#### Strategy Details
@@ -731,6 +731,8 @@ When the user specifies `--root_fs_dir=/path/to/dir` when starting the master, a
Note: When enabling this feature, the user must ensure that the DFS-mounted directory (`root_fs_dir=/path/to/dir`) is valid and consistent across all client hosts. If some clients have invalid or incorrect mount paths, it may cause abnormal behavior in Mooncake Store.
+This `root_fs_dir` path is a legacy persistence path. SSD offload uses `--enable_offload=true` on the master and real client, stores data under the real client's `MOONCAKE_OFFLOAD_FILE_STORAGE_PATH`, and records `LOCAL_DISK` replicas. Do not use `--root_fs_dir` with `--enable_offload=true`.
+
### Persistent Storage Space Configuration
Mooncake provides configurable DFS available space. Users can specify `--global_file_segment_size=1048576` when starting the master, indicating a maximum usable space of 1MB on DFS.
The current default setting is the maximum value of int64 (as we generally do not restrict DFS storage usage), which is displayed as `infinite` in `mooncake_maseter`'s console logs.
diff --git a/docs/source/design/ssd-offload.md b/docs/source/design/ssd-offload.md
index d9430f5dd1..c55d1cd7e0 100644
--- a/docs/source/design/ssd-offload.md
+++ b/docs/source/design/ssd-offload.md
@@ -6,7 +6,7 @@ Mooncake Store supports offloading KV cache objects from distributed memory to l
SSD offload is implemented as a background subsystem within the **real client** process. It is transparent to the application: a `Put` that would otherwise be evicted from memory is persisted to disk, and a `Get` that finds no memory replica automatically falls back to reading from SSD.
-For multi-turn conversation benchmark results, see [Mooncake SSD Offload Benchmark](../performance/ssd-offload-benchmark-results.md).
+For multi-turn conversation benchmark results, see [Mooncake SSD Offload Benchmark](../performance/mooncake/ssd-offload-benchmark-results.md).
---
diff --git a/docs/source/design/tent/cpp-api.md b/docs/source/design/tent/cpp-api.md
index fc68a22c62..3acead95ea 100644
--- a/docs/source/design/tent/cpp-api.md
+++ b/docs/source/design/tent/cpp-api.md
@@ -75,6 +75,7 @@ For users migrating from Transfer Engine, the following table shows how TE APIs
| `allocateBatchID(batch_size)` | `allocateBatch(batch_size)` | Renamed |
| `freeBatchID(batch_id)` | `freeBatch(batch_id)` | Renamed |
| `submitTransfer(batch_id, entries)` | `submitTransfer(batch_id, request_list)` | `TransferRequest` → `Request` |
+| *Not available* | `cancelTransfer(batch_id, task_id)` | TENT-only: best-effort cancellation for queued and RDMA tasks |
| `submitTransferWithNotify(batch_id, entries, notify_msg)` | `submitTransfer(batch_id, request_list, notifi)` | Unified API with optional notification |
| `getTransferStatus(batch_id, task_id, status)` | `getTransferStatus(batch_id, task_id, status)` | Same |
| `getBatchTransferStatus(batch_id, status)` | `getTransferStatus(batch_id, status)` | Overloaded; single `TransferStatus` output = overall status |
@@ -274,6 +275,24 @@ Queries the status of transfer requests.
- `status` / `status_list` / `overall_status`: Output parameter(s) for status.
- Return value: `Status::OK()` on success; otherwise a non-OK status.
+#### TransferEngine::cancelTransfer
+
+```cpp
+Status cancelTransfer(BatchID batch_id, size_t task_id);
+```
+
+Requests best-effort cancellation of one public task. A task still waiting in
+the TENT admission queue becomes `CANCELED` without being dispatched. For RDMA,
+workers suppress slices they observe before `ibv_post_send`; work already
+posted to a QP is allowed to drain and may complete successfully. Consequently,
+the API returning `OK` means the cancellation request was accepted, not that
+the task is already terminal. Continue polling `getTransferStatus` before
+calling `freeBatch`.
+
+Cancellation is idempotent. Merged public tasks share one physical transfer,
+so canceling any alias cancels the shared task. Direct cancellation of staging
+or non-RDMA transport work currently returns `Status::NotImplemented`.
+
#### TransferEngine::freeBatch
```cpp
diff --git a/docs/source/design/tent/qos.md b/docs/source/design/tent/qos.md
index 06ecfc27db..a468b4145a 100644
--- a/docs/source/design/tent/qos.md
+++ b/docs/source/design/tent/qos.md
@@ -62,6 +62,20 @@ This ensures that:
- High-priority requests normally never wait behind lower-priority work
- Low-priority requests eventually get serviced even under continuous high-priority load
+**Promotion configuration**:
+
+| Config key | Default | Behavior |
+|---|---|---|
+| `transports/rdma/priority_promotion_timeout_us` | `10000` (10ms) | How long an entry may wait before it is eligible for promotion. |
+| `transports/rdma/priority_promotion_per_entry` | `false` | Selects the promotion policy (see below). |
+
+`priority_promotion_per_entry` controls *which* entries a promotion pass moves up:
+
+- **`false` (default, head-only)**: a pass inspects only the queue head; if the head has timed out, the whole queue is promoted one level. This is the original, lowest-overhead "flush the tier" behavior — coarse, but it never scans the queue.
+- **`true` (per-entry)**: a pass promotes exactly the entries that have themselves timed out, leaving freshly enqueued entries in place, and considers both MEDIUM→HIGH and LOW→MEDIUM in the same tick. This avoids promoting non-starving requests and avoids stalling a starving LOW entry behind an unrelated MEDIUM promotion, at the cost of scanning the drained queue. Behavior is identical to head-only for the all-timed-out / empty cases.
+
+The default is byte-for-byte the historical behavior; set the flag to `true` to opt into finer-grained, fairer promotion.
+
### Global Slot Coordination
For multi-process environments, TENT implements global time-sliced coordination using shared memory:
diff --git a/docs/source/design/tent/tebench.md b/docs/source/design/tent/tebench.md
index c25745b5bd..f3d061d276 100644
--- a/docs/source/design/tent/tebench.md
+++ b/docs/source/design/tent/tebench.md
@@ -91,6 +91,68 @@ Each output row corresponds to one benchmark configuration.
A short (~1 second) warmup phase is executed before measurements begin.
+### 4.1 QoS Metrics Baseline
+
+Use `--qos_classes` to partition a fixed number of worker threads into QoS
+classes:
+
+```text
+name:threads:slo_us:weight[:isolated_gbps],...
+```
+
+For readability, the same contract can be supplied as JSON with
+`--qos_classes_json`:
+
+```json
+[
+ {"name": "foreground", "threads": 4, "slo_us": 1000, "weight": 4, "isolated_gbps": 12.5},
+ {"name": "checkpoint", "threads": 12, "slo_us": 0, "weight": 1, "isolated_gbps": 10.0}
+]
+```
+
+Use only one of `--qos_classes` and `--qos_classes_json`.
+
+For example, the following closed-loop mixed workload assigns four workers to
+an SLO-constrained foreground class and twelve workers to a best-effort
+checkpoint class:
+
+```bash
+./tebench \
+ --target_seg_name= \
+ --backend=tent \
+ --start_num_threads=16 \
+ --max_num_threads=16 \
+ --qos_classes=foreground:4:1000:4:12.5,checkpoint:12:0:1:10.0 \
+ --qos_link_capacity_gbps=25 \
+ --qos_output_jsonl=qos-results.jsonl
+```
+
+The class thread counts must add up to the fixed `start_num_threads` value.
+An `slo_us` of zero marks a best-effort class. The SLO is a reporting threshold:
+QoS baseline mode measures whether each completed transfer meets it, without
+changing request scheduling policy on either backend.
+
+The human-readable summary and the optional versioned JSONL record report:
+
+| Metric | Definition |
+| ------ | ---------- |
+| `slo_attainment` | Fraction of completed batches whose measured end-to-end transfer time is at most `slo_us` |
+| `p99_us` | P99 end-to-end batch transfer latency for the class |
+| `goodput_gbps` | Class throughput multiplied by SLO attainment; best-effort classes use attainment 1 |
+| `weighted_goodput_gbps` | Sum of `weight × goodput_gbps` |
+| `jain_fairness` | Jain index over per-class `throughput_gbps / weight` |
+| `isolation_leakage` | `max(0, 1 - mixed_throughput / isolated_throughput)` |
+| `total_utilization` | Aggregate measured throughput divided by `qos_link_capacity_gbps` |
+
+Isolation leakage requires a matching class-only baseline, supplied as the
+optional fifth class field. Total utilization requires
+`--qos_link_capacity_gbps`. Missing baselines are emitted as `N/A` in text and
+`null` in JSON rather than being inferred from the mixed run. Run isolated and
+mixed cases with the same block size, batch size, transport, memory type, and
+host pair. JSONL records retain `isolated_throughput_gbps` and
+`link_capacity_gbps` alongside the derived values so every metric can be
+recomputed from one record.
+
## 5. Runtime Configuration
This section summarizes the key runtime options that control workload behavior,
@@ -187,8 +249,22 @@ gpu_id + thread_id
**Transport (TENT only)**
* `--xport_type` : `rdma | shm | mnnvl | gds | iouring`
+* `--tent_intent_type` : attach a standard transfer intent to every request,
+ such as `foreground_get`, `background_prefetch`, or `checkpoint`. This is
+ useful for validating intent-specific transport and QoS policy selection.
**Metadata service**
* `--metadata_type` : `p2p | etcd | redis | http` (default: `p2p`)
* `--metadata_url_list` : comma-separated URLs (ignored in `p2p` mode)
+
+### 5.7 QoS Reporting
+
+* `--qos_classes` : class/thread/SLO/weight contract described in Section 4.1
+* `--qos_link_capacity_gbps` : measured usable link capacity in decimal GB/s
+* `--qos_output_jsonl` : append one schema-versioned JSON object per benchmark
+ configuration
+
+QoS mode intentionally requires a fixed thread count. Sweep offered load by
+running explicit cases with different class thread allocations so every output
+record has an unambiguous workload contract.
diff --git a/docs/source/design/tent/transport-selector.md b/docs/source/design/tent/transport-selector.md
index d1a90e0877..e4ba13e2ec 100644
--- a/docs/source/design/tent/transport-selector.md
+++ b/docs/source/design/tent/transport-selector.md
@@ -23,8 +23,9 @@ Transport selection is driven by configuration with pattern-based rules.
{
"policy": [
{
- "name": "high_prio_fast",
+ "name": "foreground_get",
"segment_type": "memory",
+ "intent_type": "foreground_get",
"priority": "high",
"devices": ["mlx5_0", "mlx5_1", "mlx5_2"],
"transports": ["nvlink", "rdma", "shm"]
@@ -52,9 +53,46 @@ Transport selection is driven by configuration with pattern-based rules.
| `name` | string | Yes | Policy identifier (for logging) |
| `segment_type` | string | Yes | `"memory"` or `"file"` |
| `priority` | string or int | No | Match only requests with this priority: `"high"` (0), `"medium"` (1), `"low"` (2) |
+| `intent_type` | string or int | No | Match a standard transfer intent such as `"foreground_get"`, `"background_prefetch"`, `"migration"`, `"checkpoint"`, `"weight_loading"`, or `"staging_internal"` |
| `devices` | array[string] | No | List of allowed device names (empty = all devices) |
| `transports` | array[string] | No | Transport preference list (evaluated in order) |
+### Intent-Based Policy Binding
+
+`Request::intent_type` can select an intent-specific policy before transport,
+device, QP-pool, and SL/TC resolution:
+
+```json
+{
+ "policy": [
+ {
+ "name": "foreground-kv",
+ "segment_type": "memory",
+ "intent_type": "foreground_get",
+ "qp_pool": "foreground",
+ "service_level": 3,
+ "traffic_class": 96,
+ "transports": ["rdma"]
+ },
+ {
+ "name": "memory-fallback",
+ "segment_type": "memory",
+ "transports": ["rdma", "tcp"]
+ }
+ ]
+}
+```
+
+Policies are evaluated in JSON order, so intent-specific entries should appear
+before a catch-all entry. A policy without `intent_type` retains the historical
+behavior and matches any intent. `INTENT_UNSPEC` therefore behaves exactly as
+before with existing configurations.
+
+An explicit `Request::policy_name` remains the strongest per-request override:
+it selects the named policy by segment type and bypasses the policy's other
+match filters, including `intent_type`. Invalid intent values cause that policy
+entry to be skipped rather than silently converted into a catch-all rule.
+
### Memory Type Filters
For `memory` segments, you can filter by source/destination memory type:
@@ -228,6 +266,7 @@ TransportSelector.select(context, transports, transport_index)
↓
Match policy by:
- segment_type (file/memory)
+ - intent_type (exact match if specified in policy)
- priority (exact match if specified in policy)
- location constraints
- size constraints
diff --git a/docs/source/design/transfer-engine/index.md b/docs/source/design/transfer-engine/index.md
index f089747be9..d4df0e2106 100644
--- a/docs/source/design/transfer-engine/index.md
+++ b/docs/source/design/transfer-engine/index.md
@@ -471,9 +471,12 @@ For advanced users, TransferEngine provides the following advanced runtime optio
- `MC_WORKERS_PER_CTX` The number of asynchronous worker threads corresponding to each device instance
- `MC_SLICE_SIZE` The segmentation granularity of user requests in Transfer Engine
- `MC_RETRY_CNT` The maximum number of retries in Transfer Engine
+- `MC_TE_FILTERS` Restrict which RDMA NICs the engine discovers and uses, as a comma-separated allow-list of device names (e.g. `mlx5_bond_0,mlx5_bond_1`). Only the listed NICs are kept; all others are ignored. Unset (default) discovers all NICs. This is the **same env var and semantics as the legacy Transfer Engine's device whitelist** (see below), so a single variable scopes NICs across both engines. Useful on multi-NIC / multi-NUMA hosts to keep the engine (and its rail selection) off NICs that are not routable to the peer.
+- `MC_TE_FILTERS_EXCLUDE` The deny-list counterpart of `MC_TE_FILTERS`: a comma-separated list of device names to exclude from discovery. Ignored if `MC_TE_FILTERS` is set (allow-list takes precedence). Unset (default) excludes nothing. (New; the legacy engine has an allow-list only.)
- `MC_AUTO_GID_MAX_RETRIES` The maximum number of automatic local GID reprobe retries during classic RDMA handshake recovery. Default value 2. Set to 0 to disable automatic GID retry.
- `MC_LOG_LEVEL` This option can be set as `TRACE`/`INFO`/`WARNING`/`ERROR` (see [glog doc](https://github.com/google/glog/blob/master/docs/logging.md)), and more detailed logs will be output during runtime
- `MC_DISABLE_METACACHE` Disable local meta cache to prevent transfer failure due to dynamic memory registrations, which may downgrades the performance
+- `MC_TE_METADATA_REFRESH_INTERVAL_SECONDS` Periodically refresh Transfer Engine metadata-derived local caches. Currently refreshes cached remote segment descriptors from the metadata service. Default value 0 disables background polling; callers may still manually invoke `syncSegmentCache()`. Set a positive interval in seconds when peers may re-register the same segment name after restart and cached descriptors must converge automatically
- `MC_HANDSHAKE_LISTEN_BACKLOG` The backlog size of socket listening for handshaking, default value is 128
- `MC_HANDSHAKE_CONNECT_TIMEOUT` Connect timeout in seconds for outbound handshake-port requests (QP handshake, probe, notify, metadata exchange), default value is 5. Bounds the stall when the peer address is unreachable; without it, a connect to an unroutable address (e.g. a removed node) blocks for the kernel's full TCP SYN retry cycle, which can take minutes
- `MC_HANDSHAKE_MAX_LENGTH` The maximum handshake message length in bytes for P2P mode. Valid range: 1MB to 128MB. Default value is 1MB (1048576 bytes). Increase this value when using a single RDMA instance with many registered memory buffers (>10,000) to avoid handshake failures. Example: set to 10485760 for 10MB
@@ -482,6 +485,7 @@ For advanced users, TransferEngine provides the following advanced runtime optio
- `MC_REDIS_DB_INDEX` The database index for Redis storage plugin, must be an integer between 0 and 255. Only takes effect when Redis is specified as the metadata server. If not set or invalid, the default value is 0.
- `MC_FRAGMENT_RATIO ` In RdmaTransport::submitTransferTask, if the last data piece after division is ≤ 1/MC_FRAGMENT_RATIO of the block size, it merges with the previous block to reduce overhead. The default value is 4
- `MC_ENABLE_DEST_DEVICE_AFFINITY` Enable device affinity for RDMA performance optimization. When enabled, Transfer Engine will prioritize communication with remote NICs that have the same name as local NICs to reduce QP count and improve network performance in rail-optimized topologies. The default value is false
+- `MC_TRACK_RDMA_POSTED_SLICES` Enable RDMA posted-slice tracking for timeout diagnostics. When enabled, CQ timeout logs include stuck transfer groups by peer NIC path, slice count, bytes, oldest post age, and sample addresses. This adds synchronization on the RDMA post and poll hot paths, so it is disabled by default and should be enabled only while diagnosing stuck completions.
- `MC_ENABLE_PARALLEL_REG_MR` Control parallel memory region registration across multiple RDMA NICs. Valid values: -1 (auto, default), 0 (disabled), 1 (enabled). When set to -1, parallel registration is automatically enabled when multiple RNICs exist and memory has been pre-touched. Note: If memory hasn't been touched before registration, parallel registration can be slower than sequential registration
- `MC_FORCE_HCA` Force to use RDMA as the active transport, return error if no HCA has been found.
- `MC_FORCE_MNNVL` Force to use Multi-Node NVLink as the active transport regardless whether RDMA devices are installed.
@@ -495,6 +499,7 @@ For advanced users, TransferEngine provides the following advanced runtime optio
- `MC_ENDPOINT_STORE_TYPE` Choose FIFO Endpoint Store (`FIFO`) or Sieve Endpoint Store (`SIEVE`), default is `SIEVE`.
- `MC_TCP_ENABLE_CONNECTION_POOL` Enable TCP Connection Pool to avoid excessive sockets.
- `MC_TCP_SLICE_SIZE` The segmentation granularity (in bytes) of TCP transport for splitting large transfers into socket read/write operations. Corresponds to `MC_SLICE_SIZE` for RDMA. Default value 65536 (64KB).
+- `MC_TCP_PROTO` When set to `1`, TCP initiators use the legacy unacknowledged framing even against servers that support acknowledged framing (protocol v2). Under v2 (the default against v2-capable servers), a WRITE completes only after the receiver confirms the payload has been applied to destination memory, and server-side rejections surface as failed transfers instead of silent data loss. Use this variable only as a rollback escape hatch during mixed-version upgrades.
## C++ API Reference
diff --git a/docs/source/getting_started/build.md b/docs/source/getting_started/build.md
index 796dbaee7a..12b9d22564 100644
--- a/docs/source/getting_started/build.md
+++ b/docs/source/getting_started/build.md
@@ -121,6 +121,20 @@ sudo docker run --gpus all \
The `64gb` / `56gb` values above are tuned examples for large HiCache deployments, not defaults. The arena remains disabled unless you explicitly enable it, and if you enable it via gflag without an env override the default pool size is `8gb`. On smaller hosts, start with `8gb` or `16gb` and size upward with the helper. When you want the baseline direct-`mmap()` path instead of the arena, set `MC_DISABLE_MMAP_ARENA=1` (also accepts `true`, `yes`, or `on`) and omit `MC_MMAP_ARENA_POOL_SIZE`. Set it before the first Mooncake mmap-buffer allocation in the process. If you build the image from source with `docker/mooncake.Dockerfile`, that source-built image also installs the helper as `mooncake-hicache-sizing`.
Without `MC_STORE_USE_HUGEPAGE=1`, the arena may opportunistically try hugepages and then retry on regular pages if HugeTLB is unavailable. When `MC_STORE_USE_HUGEPAGE=1` is set, both the arena path and the direct-`mmap()` fallback path require HugeTLB pages. Mooncake will not silently degrade that explicit hugepage request to regular pages.
+For RDMA Store segments backed by HugeTLB, page population is automatically
+deferred until immediately before transfer-engine registration and
+parallelized across CPU threads:
+
+```bash
+export MC_STORE_USE_HUGEPAGE=1
+export MC_STORE_HUGEPAGE_SIZE=2MB
+```
+
+Direct mappings use a generic worker pool. NUMA-segmented mappings bind each
+worker to the node associated with its memory region. The mmap arena keeps its
+eager population behavior; set `MC_DISABLE_MMAP_ARENA=1` if an arena was
+otherwise enabled and deferred direct-mmap population is desired.
+
## Advanced Compile Options
The following options can be passed to `cmake ..`.
diff --git a/docs/source/getting_started/examples/sglang-integration-v1.md b/docs/source/getting_started/examples/sglang-integration-v1.md
index 4338001dda..a169558bec 100644
--- a/docs/source/getting_started/examples/sglang-integration-v1.md
+++ b/docs/source/getting_started/examples/sglang-integration-v1.md
@@ -4,7 +4,7 @@
SGLang uses Mooncake's Transfer Engine to enable disaggregated prefill-decode (PD) serving across nodes via RDMA, with support for EP and EPD backends. This integration is based on [PR 4654](https://github.com/sgl-project/sglang/pull/4654) and [PR 4880](https://github.com/sgl-project/sglang/pull/4880).
-In benchmarks, PD disaggregation with Mooncake achieves **~30% lower ITL** while maintaining comparable throughput ([details](../../performance/sglang-benchmark-results-v1)).
+In benchmarks, PD disaggregation with Mooncake achieves **~30% lower ITL** while maintaining comparable throughput ([details](../../performance/sglang/sglang-benchmark-results-v1)).
```
+-----------+ Transfer Engine (RDMA) +-----------+
diff --git a/docs/source/getting_started/examples/sglang-integration/hicache-integration-v1.md b/docs/source/getting_started/examples/sglang-integration/hicache-integration-v1.md
index 4a6e011cb0..6e9383062b 100644
--- a/docs/source/getting_started/examples/sglang-integration/hicache-integration-v1.md
+++ b/docs/source/getting_started/examples/sglang-integration/hicache-integration-v1.md
@@ -97,7 +97,7 @@ mooncake_master --enable_http_metadata_server=true --http_metadata_server_port=8
When a `PutStart` request fails due to insufficient memory, or when the eviction thread detects that space usage has reached the configured high watermark ratio, an eviction task is triggered to free up space by evicting a portion of objects.
-Due to memory fragmentation, allocation failures may occur even when memory usage has not yet reached 100%. The actual threshold depends on the workload. This [benchmark document](https://kvcache-ai.github.io/Mooncake/performance/allocator-benchmark-result.html) provides memory allocation efficiency results under different scenarios. if excessive allocation failures are observed, consider lowering this parameter accordingly.
+Due to memory fragmentation, allocation failures may occur even when memory usage has not yet reached 100%. The actual threshold depends on the workload. This [benchmark document](https://kvcache-ai.github.io/Mooncake/performance/mooncake/allocator-benchmark-result.html) provides memory allocation efficiency results under different scenarios. if excessive allocation failures are observed, consider lowering this parameter accordingly.
**Launch Mooncake `store service` (Optional):**
diff --git a/docs/source/getting_started/examples/sglang-integration/hicache-quick-start.md b/docs/source/getting_started/examples/sglang-integration/hicache-quick-start.md
index a338ce2903..a4004f280f 100644
--- a/docs/source/getting_started/examples/sglang-integration/hicache-quick-start.md
+++ b/docs/source/getting_started/examples/sglang-integration/hicache-quick-start.md
@@ -1,6 +1,6 @@
# Quick Start: SGLang HiCache with Mooncake Backend
-Follow this streamlined workflow to get SGLang HiCache running with Mooncake as the L3 storage backend. In benchmarks, pre-populated Mooncake achieves **best TTFT** across all tiers, maintaining high cache hit rates as conversation rounds grow ([details](../../../performance/sglang-hicache-benchmark-results-v1)).
+Follow this streamlined workflow to get SGLang HiCache running with Mooncake as the L3 storage backend. In benchmarks, pre-populated Mooncake achieves **best TTFT** across all tiers, maintaining high cache hit rates as conversation rounds grow ([details](../../../performance/sglang/sglang-hicache-benchmark-results-v1)).
> Need more background or tuning options? See the [Complete Guide](hicache-integration-v1.md).
diff --git a/docs/source/getting_started/examples/sglang-integration/index.md b/docs/source/getting_started/examples/sglang-integration/index.md
index 885c444f2d..b927695bc7 100644
--- a/docs/source/getting_started/examples/sglang-integration/index.md
+++ b/docs/source/getting_started/examples/sglang-integration/index.md
@@ -17,7 +17,7 @@ SGLang uses Mooncake's Transfer Engine for direct zero-copy KV cache transfer be
**Related:** [Full PD Disaggregation Guide](../sglang-integration-v1) — installation, cross-node/same-node setup, XpYd topology, EP backend for MoE models, and EPD backend for multimodal models.
-**Benchmark:** [PD Disaggregation Performance](../../../performance/sglang-benchmark-results-v1) — compares 1P1D disaggregation with regular SGLang instances.
+**Benchmark:** [PD Disaggregation Performance](../../../performance/sglang/sglang-benchmark-results-v1) — compares 1P1D disaggregation with regular SGLang instances.
---
diff --git a/docs/source/getting_started/examples/vllm-integration/disagg-prefill-decode.md b/docs/source/getting_started/examples/vllm-integration/disagg-prefill-decode.md
index c8f0ab246d..49b81849f8 100644
--- a/docs/source/getting_started/examples/vllm-integration/disagg-prefill-decode.md
+++ b/docs/source/getting_started/examples/vllm-integration/disagg-prefill-decode.md
@@ -135,7 +135,7 @@ vllm serve Qwen/Qwen2.5-7B-Instruct \
### Performance
-For detailed performance benchmarks and results, see the [vLLM Benchmark](../../../performance/vllm-v1-support-benchmark.md) documentation.
+For detailed performance benchmarks and results, see the [vLLM PD Disaggregation Performance](../../../performance/vllm/vllm-v1-pd-performance.md) documentation.
---
@@ -146,7 +146,7 @@ For detailed performance benchmarks and results, see the [vLLM Benchmark](../../
This section is for vLLM V0 backend (≤ v0.6.4.post1). For new deployments, use the [V1 backend](#using-vllm-v1-recommended) above.
```
-This integration is based on [PR 10502](https://github.com/vllm-project/vllm/pull/10502) and [PR 10884](https://github.com/vllm-project/vllm/pull/10884). Preview benchmark results are available at [vLLM Benchmark Results V0.2](../../../performance/vllm-benchmark-results-v0.2.md).
+This integration is based on [PR 10502](https://github.com/vllm-project/vllm/pull/10502) and [PR 10884](https://github.com/vllm-project/vllm/pull/10884).
### Installation
diff --git a/docs/source/getting_started/examples/vllm-integration/index.md b/docs/source/getting_started/examples/vllm-integration/index.md
index d6107e502e..3c6d443c4f 100644
--- a/docs/source/getting_started/examples/vllm-integration/index.md
+++ b/docs/source/getting_started/examples/vllm-integration/index.md
@@ -5,7 +5,7 @@
Mooncake integrates with vLLM to accelerate large language model serving through high-performance KV cache transfer and shared storage. The integration supports two primary scenarios:
- **Disaggregated Prefill-Decode Serving**: Seamlessly split prefill and decode across nodes using `MooncakeConnector`, with RDMA-powered cross-node KV cache transfer achieving up to **142.25 GB/s** peak bandwidth (71.1% utilization of 8x RoCE). Transfer overhead is negligible — for 32K-token prompts (4.50 GB of KV data), transfer takes only **31.65 ms**, accounting for just **4.2%** of total TTFT.
-- **KV Cache Storage & Sharing**: Extend effective KV cache capacity via `MooncakeStore` / `MooncakeStoreConnector`, with hash-based prefix caching that enables multiple vLLM instances to share cached KV blocks. Supports CPU/Disk offloading and dynamic XpYd topologies at runtime.
+- **KV Cache Storage & Sharing**: Extend effective KV cache capacity via `MooncakeStore` / `MooncakeStoreConnector`, with hash-based prefix caching that enables multiple vLLM instances to share cached KV blocks. Supports CPU/Disk offloading and dynamic XpYd topologies at runtime. Distributed KV cache pool improves throughput by **3.8x**, reduces P50 TTFT and E2E latency by **46x** and **8.6x** (1P1D, 12GPUs), and scales to **60 GPUs** with >95% cache hit rate as shown in this [webpage](../../../performance/vllm/vllm-v1-mooncake-store.md).
| Scenario | Guide | vLLM Backend |
|----------|-------|-------------|
diff --git a/docs/source/getting_started/examples/vllm-integration/kv-cache-storage.md b/docs/source/getting_started/examples/vllm-integration/kv-cache-storage.md
index c25427adef..c4d9128a6b 100644
--- a/docs/source/getting_started/examples/vllm-integration/kv-cache-storage.md
+++ b/docs/source/getting_started/examples/vllm-integration/kv-cache-storage.md
@@ -4,7 +4,7 @@
This guide demonstrates how to use `MooncakeStore` / `MooncakeStoreConnector` with vLLM to build a distributed KV cache storage pool. It enables KV cache offloading to CPU/SSD, hash-based prefix caching across multiple vLLM instances, and flexible XpYd disaggregated deployment — where you can dynamically adjust prefill and decode group sizes at runtime.
-Compared to Redis-based backends, MooncakeStore achieves significantly lower TTFT (e.g., **~32% improvement** in mean TTFT for 2P2D tp=2 under RDMA). See [benchmark results](../../../performance/vllm-benchmark-results-v1.md) for details.
+Compared to Redis-based backends, MooncakeStore achieves significantly lower TTFT (e.g., **~32% improvement** in mean TTFT for 2P2D tp=2 under RDMA).
---
@@ -388,15 +388,6 @@ curl -s http://localhost:8000/v1/completions \
---
-## Performance
-
-| Scenario | Document |
-|----------|----------|
-| V1 MooncakeStoreConnector vs Redis | [Benchmark V1](../../../performance/vllm-benchmark-results-v1.md) |
-| V0 MooncakeStore vs Redis | [Benchmark V0](../../../performance/vllm-benchmark-results-v0.2.md) |
-
----
-
## Troubleshooting
- If you encounter connection issues, check that:
diff --git a/docs/source/getting_started/examples/vllm-integration/vllm-integration-v0.2.md b/docs/source/getting_started/examples/vllm-integration/vllm-integration-v0.2.md
index c9421957fe..e4f41ce372 100644
--- a/docs/source/getting_started/examples/vllm-integration/vllm-integration-v0.2.md
+++ b/docs/source/getting_started/examples/vllm-integration/vllm-integration-v0.2.md
@@ -10,7 +10,7 @@ This page has been **consolidated** into the unified [Disaggregated Prefill-Deco
```
## Overview
-This is the latest version of mooncake-transfer-engine integration doc with the vLLM project based on [PR 10502](https://github.com/vllm-project/vllm/pull/10502) and [PR 10884](https://github.com/vllm-project/vllm/pull/10884) (vllm version: v0.6.4.post1/main) to accelerate KVCache transfer for inter-node disaggregated serving scenario. We have run some experiments to obtain some [preview benchmark results](../../../performance/vllm-benchmark-results-v0.2.md). More benchmark results will be released in due time.
+This is the latest version of mooncake-transfer-engine integration doc with the vLLM project based on [PR 10502](https://github.com/vllm-project/vllm/pull/10502) and [PR 10884](https://github.com/vllm-project/vllm/pull/10884) (vllm version: v0.6.4.post1/main) to accelerate KVCache transfer for inter-node disaggregated serving scenario.
**_Please note that this is still an experimental version and will be modified anytime based on feedback from the vLLM community._**
- **Update(Apr 10, 2025)**: We are working on the vLLM v1 integration now. Stay tuned.
diff --git a/docs/source/getting_started/examples/vllm-integration/vllm-integration-v1.0.md b/docs/source/getting_started/examples/vllm-integration/vllm-integration-v1.0.md
index c1b2c31af7..86a6aedd5f 100644
--- a/docs/source/getting_started/examples/vllm-integration/vllm-integration-v1.0.md
+++ b/docs/source/getting_started/examples/vllm-integration/vllm-integration-v1.0.md
@@ -54,7 +54,7 @@ vllm serve Qwen/Qwen2.5-7B-Instruct \
#### Proxy Server
```bash
-# In vllm root directory.
+# In vllm root directory.
python tests/v1/kv_connector/nixl_integration/toy_proxy_server.py \
--prefiller-host 192.168.0.2 --prefiller-port 8010 \
--decoder-host 192.168.0.3 --decoder-port 8020
@@ -127,7 +127,7 @@ The following environment variables can be used to customize Mooncake behavior:
## Performance
-For detailed performance benchmarks and results, see the [vLLM Benchmark](../../../performance/vllm-v1-support-benchmark.md) documentation.
+For detailed performance benchmarks and results, see the [vLLM PD Disaggregation Performance](../../../performance/vllm/vllm-v1-pd-performance.md) documentation.
## Notes
diff --git a/docs/source/getting_started/examples/vllm-integration/vllm-mooncakestoreconnector.md b/docs/source/getting_started/examples/vllm-integration/vllm-mooncakestoreconnector.md
index bb0a5f52fc..8517cb5de8 100644
--- a/docs/source/getting_started/examples/vllm-integration/vllm-mooncakestoreconnector.md
+++ b/docs/source/getting_started/examples/vllm-integration/vllm-mooncakestoreconnector.md
@@ -137,3 +137,8 @@ python examples/disaggregated/disaggregated_serving/mooncake_connector/mooncake_
> ```
>
> Without this, identical prompts may produce different block hashes on different DP ranks, preventing cross-instance prefix cache hits.
+
+
+### 4. Performance
+
+Please refer to this [webpage](../../../performance/vllm/vllm-v1-mooncake-store.md).
diff --git a/docs/source/getting_started/observability.md b/docs/source/getting_started/observability.md
index fd0e3922b1..ffc6b007bb 100644
--- a/docs/source/getting_started/observability.md
+++ b/docs/source/getting_started/observability.md
@@ -165,3 +165,46 @@ The admin HTTP server is configured in the master config file (`master.json` or
```
Set `enable_metric_reporting` to `false` to disable the periodic metrics log. HTTP endpoints (`/metrics`, `/health`, etc.) remain available regardless of this setting.
+
+## Client Metrics Endpoint
+
+Mooncake clients can also expose a client-local HTTP endpoint for health checks
+and client metrics. This is separate from the master admin endpoint above and is
+disabled by default for Python/programmatic clients.
+
+Enable it through the Python setup arguments:
+
+```python
+store.setup(
+ local_hostname,
+ metadata_server,
+ global_segment_size,
+ local_buffer_size,
+ protocol,
+ rdma_devices,
+ master_server_addr,
+ enable_client_http_server=True,
+ client_http_port=9300,
+)
+```
+
+For `mooncake.mooncake_store_service`, set
+`MOONCAKE_ENABLE_CLIENT_HTTP_SERVER=true` and optionally
+`MOONCAKE_CLIENT_HTTP_PORT=`. For the standalone `mooncake_client`, use
+`--enable_http_server=true --http_port=`.
+
+| Endpoint | Content-Type | Description |
+|----------|--------------|-------------|
+| `GET /health` | `application/json` | Client health check |
+| `GET /metrics` | `text/plain; version=0.0.4` | Prometheus-format client metrics |
+| `GET /metrics/summary` | `text/plain` | Human-readable client metrics summary |
+
+```bash
+curl http://:9300/health
+curl http://:9300/metrics
+curl http://:9300/metrics/summary
+```
+
+Set `MC_STORE_CLIENT_METRIC=0` to disable client metric collection. If the
+client HTTP server remains enabled while metrics are disabled, `/metrics` and
+`/metrics/summary` return HTTP 503 with `metrics not available`.
diff --git a/docs/source/getting_started/supported-protocols.md b/docs/source/getting_started/supported-protocols.md
index f98edb2fa8..d74ad0d4a3 100644
--- a/docs/source/getting_started/supported-protocols.md
+++ b/docs/source/getting_started/supported-protocols.md
@@ -16,6 +16,7 @@ Mooncake Transfer Engine supports multiple communication protocols for data tran
| **barex** | RDMA-capable NIC | Bare-metal RDMA extension | ⚠️ Advanced |
| **cxl** | CXL-capable hardware | Memory pooling and sharing | ⚠️ Advanced |
| **ascend** | Huawei Ascend NPU | Ascend NPU communication | ⚠️ Advanced |
+| **tpu** | Google TPU (PJRT) | TPU KV-cache transfer via host-DRAM staging | 🧪 Experimental (TENT) |
## Commonly Used Protocols (Python API)
@@ -266,6 +267,39 @@ export MC_FORCE_MNNVL=true
- [Heterogeneous Ascend](../design/transfer-engine/heterogeneous_ascend.md)
- [Ascend Transport](../design/transfer-engine/ascend_transport.md)
+### TPU Transport (tpu) — Experimental
+
+**Description:** Google TPU support in the TENT runtime. Because TPU HBM is not
+directly addressable by the NIC, transfers touching TPU memory are staged
+through host DRAM: the HBM ↔ host-DRAM hop is performed by a PJRT device-copy
+adapter, and the host ↔ host hop is carried by an existing transport (RDMA/TCP).
+The two stages are chained automatically by the TENT staging pipeline
+(`ProxyManager`), so no separate networked TPU transport is required.
+
+**Status:** Experimental. The C++/TENT data path is gated behind `-DUSE_TPU=ON`
+(OFF by default). A serving-framework (JAX / PyTorch-XLA) integration layer is
+planned as a follow-up.
+
+**Use When:**
+- Disaggregated prefill/decode serving on TPU hosts
+- KV-cache transfer between TPU nodes over RDMA/TCP
+
+**Requirements:**
+- Built with `-DUSE_TPU=ON -DUSE_TENT=ON`
+- A PJRT device-copy adapter shared library exposing the `mc_tpu_pjrt_*` C ABI
+ (see `tpu_pjrt_abi.h`). The adapter is resolved at runtime via `dlopen`; its
+ path defaults to `libmooncake_tpu_pjrt.so` and can be overridden with the
+ `MC_TPU_PJRT_LIB` environment variable. No PJRT/TPU SDK is required at build
+ time.
+- An RDMA (or TCP) transport enabled for the host ↔ host hop.
+
+**Design notes:**
+- TPU memory is reported as a distinct memory type (`tpu:N` locations); the
+ staging policy routes the local HBM ↔ host copy to the TPU device-copy
+ transport and the cross-node hop to RDMA/TCP.
+- DMA-mapped (pinned) staging buffers for true async device DMA are a planned
+ performance follow-up.
+
## Configuration Examples
### Configuration File (JSON)
diff --git a/docs/source/http-api-reference/http-service.md b/docs/source/http-api-reference/http-service.md
index cbd79e007d..8c8ee90fdd 100644
--- a/docs/source/http-api-reference/http-service.md
+++ b/docs/source/http-api-reference/http-service.md
@@ -91,7 +91,7 @@ curl "http://localhost:8080/query_key?key=my_object"
```
#### `/batch_query_keys`
-Retrieve replica information for multiple keys in a single request, including memory locations and transport endpoints for each key.
+Retrieve replica information for multiple keys in a single request, including memory locations and transport endpoints for each key. The endpoint performs a read-only metadata lookup and does not grant leases, trigger promotion, or update cache-hit metrics.
**Method**: `GET`
**Parameters**: `keys` (query parameter) - Comma-separated list of object keys to query (format: key1,key2,key3)
@@ -115,6 +115,25 @@ curl "http://localhost:8080/batch_query_keys?keys=key1,key2,key3"
"transport_endpoint_": "hostname:port",
"buffer_descriptor": {...}
}
+ ],
+ "disk_values": [
+ {
+ "file_path": "/path/to/object",
+ "object_size": 4096
+ }
+ ],
+ "local_disk_values": [
+ {
+ "client_id": "12345-67890",
+ "object_size": 4096,
+ "transport_endpoint": "hostname:port"
+ }
+ ],
+ "nof_values": [
+ {
+ "transport_endpoint_": "hostname:port",
+ "buffer_descriptor": {...}
+ }
]
},
"key2": {
@@ -125,6 +144,8 @@ curl "http://localhost:8080/batch_query_keys?keys=key1,key2,key3"
}
```
+The `values` field is always present (empty array when no memory replica exists). The `disk_values`, `local_disk_values`, and `nof_values` fields are optional and only appear when the corresponding replica type is present for the key.
+
#### `/get_all_keys`
List all keys currently stored in the distributed system.
diff --git a/docs/source/index.md b/docs/source/index.md
index 288b864f1c..94cc70ad9b 100644
--- a/docs/source/index.md
+++ b/docs/source/index.md
@@ -99,6 +99,7 @@ getting_started/quick-start
:maxdepth: 1
deployment/mooncake-store-deployment-guide
+deployment/kubernetes-deployment-guide/index
getting_started/examples/sglang-integration/index
getting_started/examples/vllm-integration/index
Mooncake x LMCache Integration
@@ -111,10 +112,9 @@ Mooncake x LMDeploy Integration95% cache hit rate |
:::{toctree}
:maxdepth: 1
:hidden:
-../vllm-v1-support-benchmark
-../vllm-benchmark-results-v1
-../vllm-benchmark-results-v0.2
+vllm-v1-pd-performance
+vllm-v1-mooncake-store
+
:::
diff --git a/docs/source/performance/vllm/vllm-v1-mooncake-store.md b/docs/source/performance/vllm/vllm-v1-mooncake-store.md
new file mode 100644
index 0000000000..df8a78c3db
--- /dev/null
+++ b/docs/source/performance/vllm/vllm-v1-mooncake-store.md
@@ -0,0 +1,44 @@
+# vLLM x Mooncake Store Performance
+Mooncake leverages the `MooncakeStoreConnector` in vLLM V1 to enable a distributed KV cache pool, supporting cross-instance sharing and reuse of KV caches. Furthermore, vLLM's `MultiConnector` can be configured to orchestrate both the `MooncakeConnector` (for peer-to-peer KV transfer) and the `MooncakeStoreConnector` (for the shared pool), enabling prefill-decode (PD) disaggregation.
+
+
+
+We thank the vLLM team for conducting the performance evaluation. The detailed results are presented below.
+
+> The original blog is available at https://vllm.ai/blog/2026-05-06-mooncake-store.
+
+
+## Speeding up real agentic traces
+
+Setup: Kimi-2.5 NVFP4 model on GB200 nodes with PD disaggregation
+
+In this experiment, the model was deployed with a 1P1D configuration across 12 GPUs in total.
+
+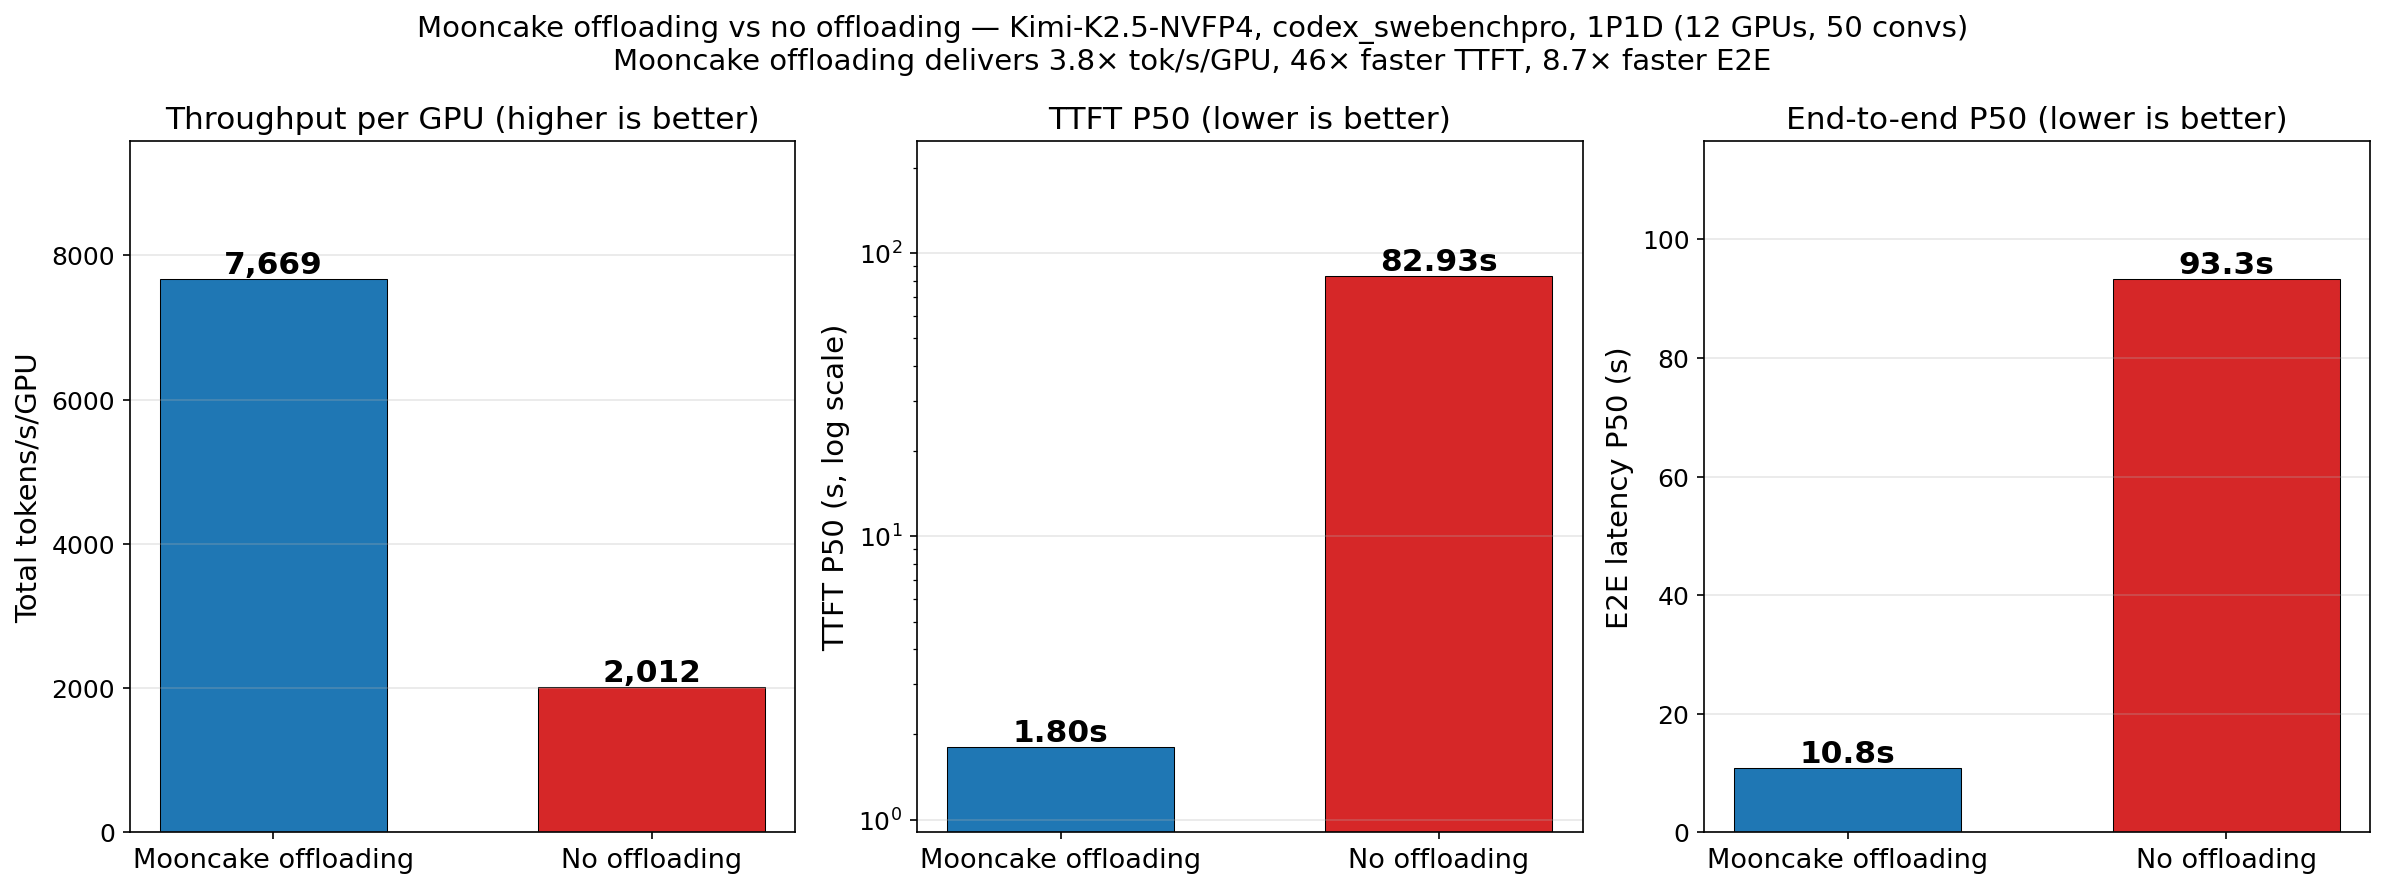
+
+The distributed KV cache pool improves vLLM throughput by 3.8x and reduces P50 TTFT and E2E latency by 46x and 8.6x, respectively. These gains are driven by a dramatic increase in cache hit rate: from 1.7%, where only the system prompt is cached, to 92.2%, where nearly the entire prefix is cached.
+
+## Scaling out to multiple nodes
+
+Experiment settings:
+
+* 20K common tokens (system instructions)
+* 10K tokens first input
+* 2,048 tokens per-turn input length
+* 900 output tokens
+* 30 turns total
+* Number of sessions scaled with number of GPUs: 75 → 150 → 225 → 300 → 375
+* Parameters were chosen to roughly align with the original Codex workload and keep the total output/input ratio ~1.3%
+
+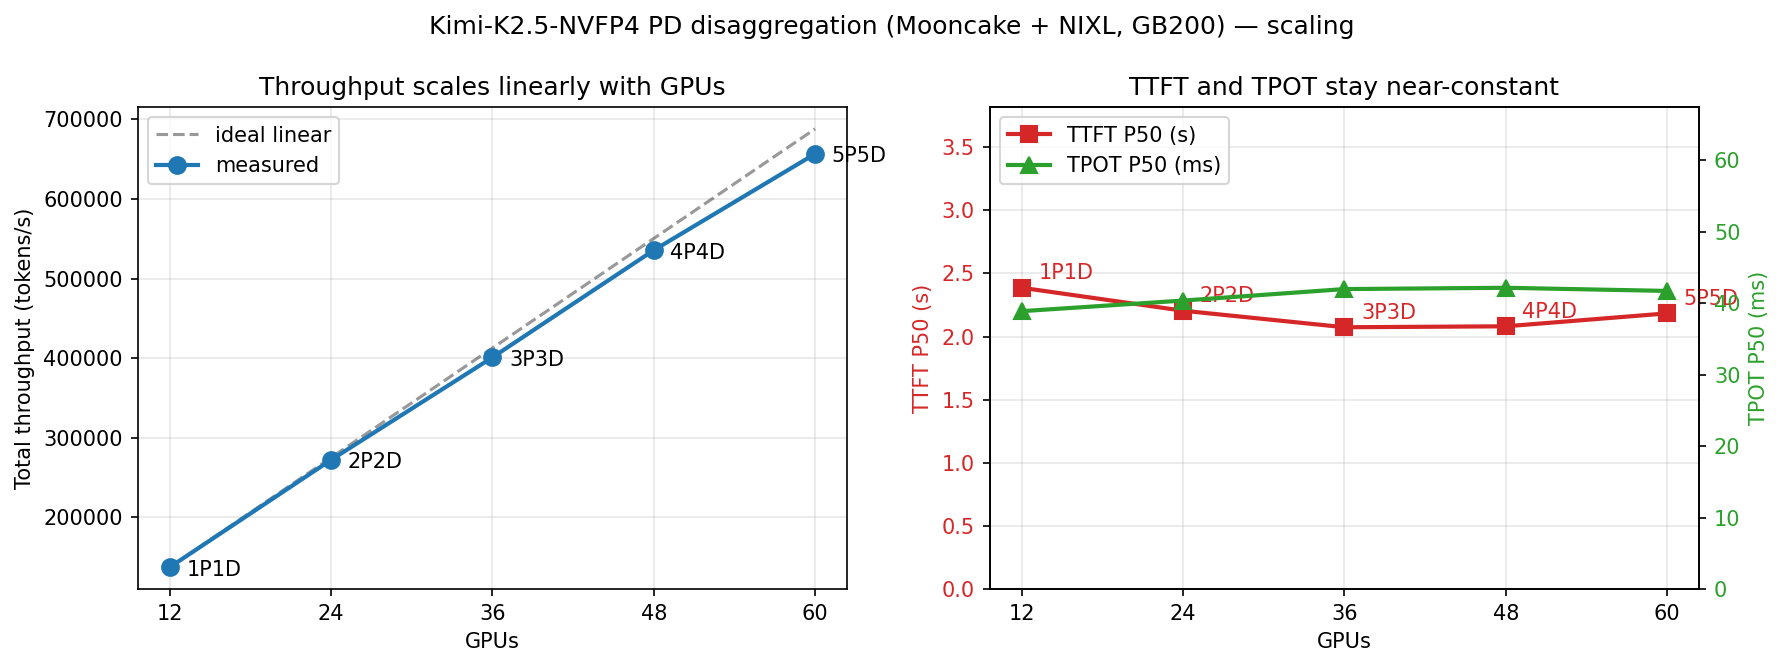
+
+To stress-test the datapath under cross-node traffic, we used round-robin routing. As a result, requests could be scheduled on different nodes across turns and often needed to fetch KV caches from a previous node.
+
+Without a distributed KV cache pool, this routing pattern would cause massive cache misses and severe throughput degradation. With Mooncake Store, vLLM consistently achieves a cache hit rate above 95%, and the system scales nearly linearly to 60 GPUs.
+
+This result shows that the distributed KV cache pool substantially improves cache hit rate while maintaining an efficient datapath as the cluster grows.
+
+
+## Benchmark Scripts
+
+The benchmark scripts are provided in the artifact repository [here](https://github.com/ivanium/vllm/tree/feat/mooncake-store-int/scripts/mooncake/artifacts).
diff --git a/docs/source/performance/vllm-v1-support-benchmark.md b/docs/source/performance/vllm/vllm-v1-pd-performance.md
similarity index 90%
rename from docs/source/performance/vllm-v1-support-benchmark.md
rename to docs/source/performance/vllm/vllm-v1-pd-performance.md
index d6cc7c578f..8780b3a4e5 100644
--- a/docs/source/performance/vllm-v1-support-benchmark.md
+++ b/docs/source/performance/vllm/vllm-v1-pd-performance.md
@@ -1,6 +1,6 @@
-# vLLM with Mooncake Transfer Engine Benchmark
+# vLLM PD Disaggregation Performance
-Mooncake has now implemented a vLLM connector, enabling direct support for the Prefill-Decode (PD) separation architecture in vLLM v1. We evaluated the performance of this integration, focusing on the efficiency of cross-node KV cache transfer using RDMA.
+Mooncake has now implemented a vLLM connector, enabling direct support for the Prefill-Decode (PD) disaggregation architecture in vLLM v1. We evaluated the performance of this integration, focusing on the efficiency of cross-node KV cache transfer using RDMA.
## Benchmark Result
@@ -8,7 +8,7 @@ Mooncake has now implemented a vLLM connector, enabling direct support for the P
We measured the actual transfer bandwidth during the execution of requests with varying prompt lengths.
-
+
In a 1P1D (1 Prefiller, 1 Decoder) configuration using the Qwen3-8B model, Mooncake achieved a peak actual transfer bandwidth of **142.25 GB/s**. Given the theoretical maximum bandwidth of approximately 200 GB/s for the 8x RoCE connections, this represents a **71.1% bandwidth utilization rate**. This efficiency demonstrates that the custom transfer protocol and GPU Direct RDMA capabilities can effectively saturate high-performance networks.
@@ -16,9 +16,9 @@ In a 1P1D (1 Prefiller, 1 Decoder) configuration using the Qwen3-8B model, Moonc
We analyzed the Time To First Token (TTFT) to understand the impact of KV transfer overhead on end-to-end latency.
-
+
-
+
The results show that Mooncake's high-speed transfer ensures that the overhead of moving KV cache is negligible compared to the computation time. For a prompt length of 32,768 tokens (transferring 4.50 GB of data), the actual KV transfer took only **31.65 ms**, accounting for merely **4.2%** of the total TTFT.
diff --git a/mooncake-common/FindUrma.cmake b/mooncake-common/FindUrma.cmake
index 0af8d1a7ca..1a069ddc41 100644
--- a/mooncake-common/FindUrma.cmake
+++ b/mooncake-common/FindUrma.cmake
@@ -1,20 +1,30 @@
include(FetchContent)
-# UMDK 头文件库
-FetchContent_Declare(
- urma
- GIT_REPOSITORY https://atomgit.com/openeuler/umdk.git
- GIT_TAG v25.12.0.B081
-)
+# Allow callers to supply headers without downloading UMDK, e.g.: cmake
+# -DURMA_INCLUDE_DIR=/usr/include ... cmake
+# -DFETCHCONTENT_SOURCE_DIR_URMA=/path/to/umdk ...
+if(DEFINED URMA_INCLUDE_DIR AND URMA_INCLUDE_DIR)
+ set(urma_INCLUDE_DIR ${URMA_INCLUDE_DIR})
+ message(STATUS "Using provided URMA_INCLUDE_DIR: ${urma_INCLUDE_DIR}")
+elseif(DEFINED FETCHCONTENT_SOURCE_DIR_URMA AND FETCHCONTENT_SOURCE_DIR_URMA)
+ set(urma_SOURCE_DIR ${FETCHCONTENT_SOURCE_DIR_URMA})
+ set(urma_INCLUDE_DIR ${urma_SOURCE_DIR}/src/urma/lib/urma/core/include)
+ message(STATUS "Using FETCHCONTENT_SOURCE_DIR_URMA: ${urma_SOURCE_DIR}")
+else()
+ FetchContent_Declare(
+ urma
+ GIT_REPOSITORY https://atomgit.com/openeuler/umdk.git
+ GIT_TAG v25.12.0.B081
+ GIT_SHALLOW TRUE)
-FetchContent_MakeAvailable(urma)
+ FetchContent_GetProperties(urma)
+ if(NOT urma_POPULATED)
+ FetchContent_Populate(urma)
+ endif()
-# 输出实际路径,确认位置
-message(STATUS "URMA source dir: ${urma_SOURCE_DIR}")
-message(STATUS "URMA binary dir: ${urma_BINARY_DIR}")
+ set(urma_INCLUDE_DIR ${urma_SOURCE_DIR}/src/urma/lib/urma/core/include)
+ message(STATUS "URMA source dir: ${urma_SOURCE_DIR}")
+ message(STATUS "URMA binary dir: ${urma_BINARY_DIR}")
+endif()
-# 假设 UMDK 头文件在其 include 目录下
-set(urma_INCLUDE_DIR ${urma_SOURCE_DIR}/src/urma/lib/urma/core/include)
-
-# 添加到需要的目标
-message(STATUS "urma_INCLUDE_DIR: ${urma_INCLUDE_DIR}")
\ No newline at end of file
+message(STATUS "urma_INCLUDE_DIR: ${urma_INCLUDE_DIR}")
diff --git a/mooncake-common/common.cmake b/mooncake-common/common.cmake
index 2426a6ebe1..6af779a249 100644
--- a/mooncake-common/common.cmake
+++ b/mooncake-common/common.cmake
@@ -91,6 +91,9 @@ option(USE_EFA "option for using AWS EFA transport" OFF)
option(USE_UB "option for using UB protocol transport" OFF)
option(USE_SUNRISE
"option for enabling gpu features for Sunrise GPU with Tang runtime" OFF)
+option(USE_TPU
+ "option for enabling TPU (PJRT) staging support in TENT; the PJRT adapter is loaded at runtime via dlopen, no build-time SDK required"
+ OFF)
if(USE_UB)
add_compile_definitions(USE_UB)
@@ -203,6 +206,20 @@ if(USE_CUDA)
link_directories(/usr/local/cuda/lib /usr/local/cuda/lib64)
endif()
+if(USE_TPU)
+ # Every TPU source file lives under mooncake-transfer-engine/tent, which is
+ # only added when USE_TENT is ON. Without this guard -DUSE_TPU=ON configures
+ # and builds cleanly while compiling no TPU code at all.
+ if(NOT USE_TENT)
+ message(
+ FATAL_ERROR
+ "USE_TPU=ON requires USE_TENT=ON: all TPU support lives in TENT. Re-run cmake with -DUSE_TENT=ON."
+ )
+ endif()
+ add_compile_definitions(USE_TPU)
+ message(STATUS "TPU (PJRT) staging support is enabled")
+endif()
+
if(NOT DEFINED NEUWARE_ROOT OR NEUWARE_ROOT STREQUAL "")
if(DEFINED ENV{NEUWARE_HOME} AND NOT "$ENV{NEUWARE_HOME}" STREQUAL "")
set(NEUWARE_ROOT
diff --git a/mooncake-common/include/environ.h b/mooncake-common/include/environ.h
index 78f8f45028..ec860500ae 100644
--- a/mooncake-common/include/environ.h
+++ b/mooncake-common/include/environ.h
@@ -52,8 +52,30 @@ class Environ {
bool GetWithNvidiaPeermem() const { return with_nvidia_peermem_; }
int GetEfaCqThreads() const { return efa_cq_threads_; }
+ // AWS / S3 client configuration
+ std::string GetAwsRegion() const { return aws_region_; }
+ std::string GetAwsS3Endpoint() const { return aws_s3_endpoint_; }
+ std::string GetAwsBucketName() const { return aws_bucket_name_; }
+ std::string GetAwsAccessKeyId() const { return aws_access_key_id_; }
+ std::string GetAwsSecretAccessKey() const { return aws_secret_access_key_; }
+ bool GetAwsUseVirtualAddressing() const {
+ return aws_use_virtual_addressing_;
+ }
+ bool GetAwsUseHttps() const { return aws_use_https_; }
+ // Empty string means "unset" — s3_helper keeps the AWS SDK default in
+ // that case. Parsing to AWS enums is done by the consumer.
+ std::string GetAwsRequestChecksumCalculation() const {
+ return aws_request_checksum_calculation_;
+ }
+ std::string GetAwsResponseChecksumValidation() const {
+ return aws_response_checksum_validation_;
+ }
+ int64_t GetAwsConnectTimeoutMs() const { return aws_connect_timeout_ms_; }
+ int64_t GetAwsRequestTimeoutMs() const { return aws_request_timeout_ms_; }
+
// Helper method to get int from env
static int GetInt(const char* name, int default_value);
+ static int64_t GetInt64(const char* name, int64_t default_value);
// Helper method to get size_t from env
static size_t GetSizeT(const char* name, size_t default_value);
// Helper method to get bool from env (checks for "1", "true", "TRUE")
@@ -103,6 +125,19 @@ class Environ {
bool path_roundrobin_;
bool with_nvidia_peermem_;
int efa_cq_threads_;
+
+ // AWS / S3 client configuration
+ std::string aws_region_;
+ std::string aws_s3_endpoint_;
+ std::string aws_bucket_name_;
+ std::string aws_access_key_id_;
+ std::string aws_secret_access_key_;
+ bool aws_use_virtual_addressing_;
+ bool aws_use_https_;
+ std::string aws_request_checksum_calculation_;
+ std::string aws_response_checksum_validation_;
+ int64_t aws_connect_timeout_ms_;
+ int64_t aws_request_timeout_ms_;
};
} // namespace mooncake
diff --git a/mooncake-common/k8s-lease/go.mod b/mooncake-common/k8s-lease/go.mod
index 4bfc205264..b3c7f5cdf2 100644
--- a/mooncake-common/k8s-lease/go.mod
+++ b/mooncake-common/k8s-lease/go.mod
@@ -1,6 +1,6 @@
module github.com/kvcache-ai/Mooncake/mooncake-common/k8s-lease
-go 1.24.0
+go 1.25.0
require (
k8s.io/api v0.34.3
@@ -40,11 +40,11 @@ require (
github.com/x448/float16 v0.8.4 // indirect
go.yaml.in/yaml/v2 v2.4.3 // indirect
go.yaml.in/yaml/v3 v3.0.4 // indirect
- golang.org/x/net v0.47.0 // indirect
+ golang.org/x/net v0.55.0 // indirect
golang.org/x/oauth2 v0.30.0 // indirect
- golang.org/x/sys v0.38.0 // indirect
- golang.org/x/term v0.37.0 // indirect
- golang.org/x/text v0.31.0 // indirect
+ golang.org/x/sys v0.45.0 // indirect
+ golang.org/x/term v0.43.0 // indirect
+ golang.org/x/text v0.37.0 // indirect
golang.org/x/time v0.9.0 // indirect
google.golang.org/protobuf v1.36.8 // indirect
gopkg.in/evanphx/json-patch.v4 v4.13.0 // indirect
diff --git a/mooncake-common/src/environ.cpp b/mooncake-common/src/environ.cpp
index 46aa1e9a9c..a920414fd9 100644
--- a/mooncake-common/src/environ.cpp
+++ b/mooncake-common/src/environ.cpp
@@ -31,6 +31,23 @@ int Environ::GetInt(const char* name, int default_value) {
return default_value;
}
+int64_t Environ::GetInt64(const char* name, int64_t default_value) {
+ const char* val = std::getenv(name);
+ if (val) {
+ char* endptr = nullptr;
+ errno = 0;
+ long long result = std::strtoll(val, &endptr, 10);
+ if (endptr == val || *endptr != '\0' || errno == ERANGE) {
+ std::cerr << "[Mooncake] Warning: invalid value '" << val
+ << "' for env " << name << ", using default "
+ << default_value << std::endl;
+ return default_value;
+ }
+ return static_cast(result);
+ }
+ return default_value;
+}
+
size_t Environ::GetSizeT(const char* name, size_t default_value) {
const char* val = std::getenv(name);
if (val) {
@@ -108,6 +125,26 @@ Environ::Environ() {
path_roundrobin_ = GetBool("MC_PATH_ROUNDROBIN", false);
with_nvidia_peermem_ = GetBool("WITH_NVIDIA_PEERMEM", true);
efa_cq_threads_ = GetInt("MC_EFA_CQ_THREADS", 1);
+
+ // AWS / S3 client configuration (consumed by s3_helper.cpp)
+ aws_region_ = GetString("MOONCAKE_AWS_REGION", "");
+ aws_s3_endpoint_ = GetString("MOONCAKE_AWS_S3_ENDPOINT", "");
+ aws_bucket_name_ = GetString("MOONCAKE_AWS_BUCKET_NAME", "");
+ aws_access_key_id_ = GetString("MOONCAKE_AWS_ACCESS_KEY_ID", "");
+ aws_secret_access_key_ = GetString("MOONCAKE_AWS_SECRET_ACCESS_KEY", "");
+ aws_use_virtual_addressing_ =
+ GetBool("MOONCAKE_AWS_USE_VIRTUAL_ADDRESSING", true);
+ aws_use_https_ = GetBool("MOONCAKE_AWS_USE_HTTPS", true);
+ // Empty string preserves "unset" semantics — s3_helper keeps the AWS SDK
+ // default in that case rather than forcing a value.
+ aws_request_checksum_calculation_ =
+ GetString("MOONCAKE_AWS_REQUEST_CHECKSUM_CALCULATION", "");
+ aws_response_checksum_validation_ =
+ GetString("MOONCAKE_AWS_RESPONSE_CHECKSUM_VALIDATION", "");
+ aws_connect_timeout_ms_ =
+ GetInt64("MOONCAKE_AWS_CONNECT_TIMEOUT_MS", 10000);
+ aws_request_timeout_ms_ =
+ GetInt64("MOONCAKE_AWS_REQUEST_TIMEOUT_MS", 30000);
}
} // namespace mooncake
diff --git a/mooncake-common/tests/environ_test.cpp b/mooncake-common/tests/environ_test.cpp
index 9a0b534063..b859d59359 100644
--- a/mooncake-common/tests/environ_test.cpp
+++ b/mooncake-common/tests/environ_test.cpp
@@ -28,9 +28,22 @@ class EnvironTest : public ::testing::Test {
void clearTestEnvVars() {
unsetenv("MC_TEST_INT");
+ unsetenv("MC_TEST_INT64");
unsetenv("MC_TEST_SIZET");
unsetenv("MC_TEST_BOOL");
unsetenv("MC_TEST_STRING");
+ // Make sure AWS vars don't leak in from the test runner's env.
+ unsetenv("MOONCAKE_AWS_REGION");
+ unsetenv("MOONCAKE_AWS_S3_ENDPOINT");
+ unsetenv("MOONCAKE_AWS_BUCKET_NAME");
+ unsetenv("MOONCAKE_AWS_ACCESS_KEY_ID");
+ unsetenv("MOONCAKE_AWS_SECRET_ACCESS_KEY");
+ unsetenv("MOONCAKE_AWS_USE_VIRTUAL_ADDRESSING");
+ unsetenv("MOONCAKE_AWS_USE_HTTPS");
+ unsetenv("MOONCAKE_AWS_REQUEST_CHECKSUM_CALCULATION");
+ unsetenv("MOONCAKE_AWS_RESPONSE_CHECKSUM_VALIDATION");
+ unsetenv("MOONCAKE_AWS_CONNECT_TIMEOUT_MS");
+ unsetenv("MOONCAKE_AWS_REQUEST_TIMEOUT_MS");
}
};
@@ -85,6 +98,70 @@ TEST_F(EnvironTest, GetIntMinValue) {
EXPECT_EQ(Environ::GetInt("MC_TEST_INT", 0), INT_MIN);
}
+// --- GetInt64 ---
+
+TEST_F(EnvironTest, GetInt64ValidValue) {
+ setenv("MC_TEST_INT64", "123456789012", 1);
+ EXPECT_EQ(Environ::GetInt64("MC_TEST_INT64", 0), 123456789012LL);
+}
+
+TEST_F(EnvironTest, GetInt64Missing) {
+ EXPECT_EQ(Environ::GetInt64("MC_TEST_INT64", 9999), 9999);
+}
+
+TEST_F(EnvironTest, GetInt64Empty) {
+ setenv("MC_TEST_INT64", "", 1);
+ EXPECT_EQ(Environ::GetInt64("MC_TEST_INT64", 555), 555);
+}
+
+TEST_F(EnvironTest, GetInt64NonNumeric) {
+ setenv("MC_TEST_INT64", "abc", 1);
+ EXPECT_EQ(Environ::GetInt64("MC_TEST_INT64", 555), 555);
+}
+
+TEST_F(EnvironTest, GetInt64Overflow) {
+ setenv("MC_TEST_INT64", "99999999999999999999999999", 1);
+ EXPECT_EQ(Environ::GetInt64("MC_TEST_INT64", 555), 555);
+}
+
+// --- AWS / S3 fields ---
+//
+// NOTE: Environ is a singleton whose constructor caches every value the
+// first time Get() is called. So all AWS env vars must be set BEFORE the
+// first Environ::Get() in this process. We therefore cover the populate
+// path in a single test that takes the singleton's "first call" for
+// itself; the default-path behavior is implicitly covered by Environ's
+// constructor defaults (any earlier test would lock the cache to defaults
+// and prevent us from observing populated values here).
+
+TEST_F(EnvironTest, AwsFieldsPopulateFromEnv) {
+ setenv("MOONCAKE_AWS_REGION", "us-east-1", 1);
+ setenv("MOONCAKE_AWS_S3_ENDPOINT", "https://s3.example.com", 1);
+ setenv("MOONCAKE_AWS_BUCKET_NAME", "my-bucket", 1);
+ setenv("MOONCAKE_AWS_ACCESS_KEY_ID", "AKIA-test", 1);
+ setenv("MOONCAKE_AWS_SECRET_ACCESS_KEY", "secret", 1);
+ setenv("MOONCAKE_AWS_USE_VIRTUAL_ADDRESSING", "0", 1);
+ setenv("MOONCAKE_AWS_USE_HTTPS", "0", 1);
+ setenv("MOONCAKE_AWS_REQUEST_CHECKSUM_CALCULATION", "when_required", 1);
+ setenv("MOONCAKE_AWS_RESPONSE_CHECKSUM_VALIDATION", "when_supported", 1);
+ setenv("MOONCAKE_AWS_CONNECT_TIMEOUT_MS", "5000", 1);
+ // Bogus request timeout should fall back to the registered default.
+ setenv("MOONCAKE_AWS_REQUEST_TIMEOUT_MS", "bogus", 1);
+
+ const auto& e = Environ::Get();
+ EXPECT_EQ(e.GetAwsRegion(), "us-east-1");
+ EXPECT_EQ(e.GetAwsS3Endpoint(), "https://s3.example.com");
+ EXPECT_EQ(e.GetAwsBucketName(), "my-bucket");
+ EXPECT_EQ(e.GetAwsAccessKeyId(), "AKIA-test");
+ EXPECT_EQ(e.GetAwsSecretAccessKey(), "secret");
+ EXPECT_FALSE(e.GetAwsUseVirtualAddressing());
+ EXPECT_FALSE(e.GetAwsUseHttps());
+ EXPECT_EQ(e.GetAwsRequestChecksumCalculation(), "when_required");
+ EXPECT_EQ(e.GetAwsResponseChecksumValidation(), "when_supported");
+ EXPECT_EQ(e.GetAwsConnectTimeoutMs(), 5000);
+ EXPECT_EQ(e.GetAwsRequestTimeoutMs(), 30000);
+}
+
// --- GetSizeT ---
TEST_F(EnvironTest, GetSizeTValidValue) {
diff --git a/mooncake-ep/benchmarks/elastic_buffer_perf.py b/mooncake-ep/benchmarks/elastic_buffer_perf.py
new file mode 100644
index 0000000000..0bd2d10d13
--- /dev/null
+++ b/mooncake-ep/benchmarks/elastic_buffer_perf.py
@@ -0,0 +1,307 @@
+#!/usr/bin/env python3
+"""Performance smoke for Mooncake ElasticBuffer dispatch/combine.
+
+The benchmark intentionally keeps the workload simple and reproducible. It is
+not a full system benchmark; it provides a reviewer-friendly way to verify that
+the new elastic path runs repeatedly, supports cached handles, and reports
+per-rank effective payload bandwidth.
+
+Typical single-node usage:
+
+ MOONCAKE_EP_NUM_LOCAL_RANKS=8 \
+ torchrun --standalone --nproc_per_node=8 \
+ mooncake-ep/benchmarks/elastic_buffer_perf.py --route alltoall
+"""
+
+from __future__ import annotations
+
+import argparse
+import os
+import time
+from dataclasses import dataclass
+
+import torch
+import torch.distributed as dist
+import torch.testing as testing
+
+from mooncake.mooncake_elastic_buffer import ElasticBuffer
+
+
+@dataclass(frozen=True)
+class RoutePlan:
+ topk_idx: torch.Tensor
+ expected_recv_tokens: int
+ expected_combine_factor: int
+
+
+def parse_args() -> argparse.Namespace:
+ parser = argparse.ArgumentParser(description="Benchmark Mooncake ElasticBuffer")
+ parser.add_argument("--num-tokens", type=int, default=128)
+ parser.add_argument("--max-tokens", type=int, default=0)
+ parser.add_argument("--hidden", type=int, default=4096)
+ parser.add_argument("--num-experts", type=int, default=256)
+ parser.add_argument("--num-topk", type=int, default=8)
+ parser.add_argument("--num-sms", type=int, default=24)
+ parser.add_argument("--warmup", type=int, default=5)
+ parser.add_argument("--iters", type=int, default=20)
+ parser.add_argument(
+ "--route",
+ choices=("alltoall", "local", "cross"),
+ default="alltoall",
+ help="Expert routing pattern to generate.",
+ )
+ parser.add_argument(
+ "--reuse-handle",
+ action=argparse.BooleanOptionalAction,
+ default=True,
+ help="Reuse the first dispatch handle for later iterations.",
+ )
+ parser.add_argument(
+ "--check-correctness",
+ action=argparse.BooleanOptionalAction,
+ default=True,
+ help="Check combine output on each iteration.",
+ )
+ parser.add_argument(
+ "--sync-actual-count",
+ action="store_true",
+ help="Synchronize and verify GPU-side received-token count each iteration.",
+ )
+ parser.add_argument("--seed", type=int, default=2026)
+ return parser.parse_args()
+
+
+def init_distributed(seed: int) -> tuple[int, int]:
+ if not dist.is_initialized():
+ dist.init_process_group("nccl")
+ rank = dist.get_rank()
+ local_rank = int(os.environ.get("LOCAL_RANK", rank % torch.cuda.device_count()))
+ torch.cuda.set_device(local_rank)
+ torch.set_default_device("cuda")
+ torch.set_default_dtype(torch.bfloat16)
+ torch.manual_seed(seed + rank)
+ return rank, dist.get_world_size()
+
+
+def make_route_plan(
+ *,
+ rank: int,
+ world_size: int,
+ buffer: ElasticBuffer,
+ num_tokens: int,
+ num_topk: int,
+ num_experts: int,
+ route: str,
+) -> RoutePlan:
+ local_experts = num_experts // world_size
+ if local_experts <= 0:
+ raise ValueError("num_experts must be at least world_size")
+ expert_offsets = torch.arange(num_topk, device="cuda", dtype=torch.long) % local_experts
+
+ if route == "cross" and buffer.num_scaleout_ranks > 1:
+ dst_scaleout = (buffer.scaleout_rank_idx + 1) % buffer.num_scaleout_ranks
+ dst_rank = dst_scaleout * buffer.num_scaleup_ranks + buffer.scaleup_rank_idx
+ choices = dst_rank * local_experts + expert_offsets
+ return RoutePlan(
+ choices.view(1, num_topk).repeat(num_tokens, 1).contiguous(),
+ num_tokens,
+ 1,
+ )
+
+ if route == "local" or (route == "cross" and buffer.num_scaleout_ranks == 1):
+ choices = rank * local_experts + expert_offsets
+ return RoutePlan(
+ choices.view(1, num_topk).repeat(num_tokens, 1).contiguous(),
+ num_tokens,
+ 1,
+ )
+
+ dst_ranks = (rank + torch.arange(num_topk, device="cuda", dtype=torch.long)) % world_size
+ choices = dst_ranks * local_experts + expert_offsets
+ unique_dst_ranks = int(torch.unique(dst_ranks).numel())
+ return RoutePlan(
+ choices.view(1, num_topk).repeat(num_tokens, 1).contiguous(),
+ num_tokens * unique_dst_ranks,
+ unique_dst_ranks,
+ )
+
+
+def make_input(rank: int, iteration: int, num_tokens: int, hidden: int) -> torch.Tensor:
+ base = torch.arange(num_tokens * hidden, device="cuda", dtype=torch.float32)
+ base = base.view(num_tokens, hidden)
+ return (base + rank * 1_000_000 + iteration * 17).to(torch.bfloat16).contiguous()
+
+
+def check_output(
+ *,
+ rank: int,
+ route: str,
+ combined: torch.Tensor,
+ expected: torch.Tensor,
+) -> None:
+ if route == "local":
+ if not torch.equal(combined, expected):
+ diff = (combined.float() - expected.float()).abs().max().item()
+ raise AssertionError(f"rank={rank}: local-route mismatch, max_diff={diff}")
+ return
+
+ testing.assert_close(
+ combined,
+ expected,
+ rtol=1e-2,
+ atol=1e-3,
+ msg=lambda msg: f"rank={rank}: {route} combine mismatch: {msg}",
+ )
+
+
+def main() -> None:
+ args = parse_args()
+ rank, world_size = init_distributed(args.seed)
+ max_tokens = args.max_tokens or max(128, args.num_tokens)
+ num_experts = args.num_experts
+ if num_experts % world_size != 0:
+ raise ValueError("num_experts must be divisible by world_size")
+
+ buffer = ElasticBuffer(
+ dist.group.WORLD,
+ num_max_tokens_per_rank=max_tokens,
+ hidden=args.hidden,
+ num_topk=args.num_topk,
+ use_fp8_dispatch=False,
+ deterministic=False,
+ allow_hybrid_mode=True,
+ allow_multiple_reduction=True,
+ num_gpu_timeout_secs=10,
+ )
+ route_plan = make_route_plan(
+ rank=rank,
+ world_size=world_size,
+ buffer=buffer,
+ num_tokens=args.num_tokens,
+ num_topk=args.num_topk,
+ num_experts=num_experts,
+ route=args.route,
+ )
+ weights = torch.ones((args.num_tokens, args.num_topk), device="cuda", dtype=torch.float32)
+
+ def run_one(iteration: int, cached_handle):
+ x = make_input(rank, iteration, args.num_tokens, args.hidden)
+ dispatch_start = torch.cuda.Event(enable_timing=True)
+ dispatch_end = torch.cuda.Event(enable_timing=True)
+ combine_end = torch.cuda.Event(enable_timing=True)
+
+ use_cached = args.reuse_handle and cached_handle is not None
+ dispatch_start.record()
+ recv_x, _recv_idx, recv_weights, handle, _ = buffer.dispatch(
+ x,
+ topk_idx=None if use_cached else route_plan.topk_idx,
+ topk_weights=None if use_cached else weights,
+ num_experts=num_experts,
+ num_max_tokens_per_rank=max_tokens,
+ expert_alignment=1,
+ handle=cached_handle if use_cached else None,
+ do_cpu_sync=True if not use_cached else None,
+ num_sms=args.num_sms,
+ async_with_compute_stream=False,
+ )
+ dispatch_end.record()
+
+ actual_recv_tokens = route_plan.expected_recv_tokens
+ if args.sync_actual_count:
+ actual_recv_tokens = int(handle.psum_num_recv_tokens_per_scaleup_rank[-1].item())
+ if actual_recv_tokens != route_plan.expected_recv_tokens:
+ raise AssertionError(
+ f"rank={rank}: got {actual_recv_tokens} received tokens, "
+ f"expected {route_plan.expected_recv_tokens}"
+ )
+
+ combined, _combined_weights, _ = buffer.combine(
+ recv_x[:actual_recv_tokens].contiguous(),
+ handle,
+ topk_weights=(
+ recv_weights[:actual_recv_tokens].contiguous()
+ if recv_weights is not None
+ else None
+ ),
+ num_sms=args.num_sms,
+ async_with_compute_stream=False,
+ )
+ combine_end.record()
+ torch.cuda.synchronize()
+
+ if args.check_correctness:
+ expected = (x.float() * route_plan.expected_combine_factor).to(torch.bfloat16)
+ check_output(rank=rank, route=args.route, combined=combined, expected=expected)
+
+ return (
+ handle,
+ dispatch_start.elapsed_time(dispatch_end),
+ dispatch_end.elapsed_time(combine_end),
+ actual_recv_tokens,
+ )
+
+ cached_handle = None
+ for i in range(args.warmup):
+ cached_handle, _dispatch_ms, _combine_ms, _actual = run_one(i, cached_handle)
+
+ dist.barrier()
+ torch.cuda.synchronize()
+ dispatch_ms = []
+ combine_ms = []
+ recv_tokens = []
+ wall_start = time.time()
+ for i in range(args.iters):
+ cached_handle, d_ms, c_ms, actual = run_one(args.warmup + i, cached_handle)
+ dispatch_ms.append(d_ms)
+ combine_ms.append(c_ms)
+ recv_tokens.append(actual)
+ torch.cuda.synchronize()
+ dist.barrier()
+ wall_seconds = time.time() - wall_start
+
+ stats = torch.tensor(
+ [
+ sum(dispatch_ms) / len(dispatch_ms),
+ sum(combine_ms) / len(combine_ms),
+ min(dispatch_ms),
+ max(dispatch_ms),
+ min(combine_ms),
+ max(combine_ms),
+ sum(recv_tokens) / len(recv_tokens),
+ wall_seconds,
+ ],
+ device="cuda",
+ dtype=torch.float64,
+ )
+ gathered = [torch.empty_like(stats) for _ in range(world_size)]
+ dist.all_gather(gathered, stats)
+
+ if rank == 0:
+ table = torch.stack(gathered).cpu()
+ payload_bytes = table[:, 6].mean().item() * args.hidden * 2
+ dispatch_avg_ms = table[:, 0].mean().item()
+ combine_avg_ms = table[:, 1].mean().item()
+ print(
+ "MOONCAKE_ELASTIC_PERF_OK",
+ f"world={world_size}",
+ f"route={args.route}",
+ f"reuse_handle={int(args.reuse_handle)}",
+ f"tokens={args.num_tokens}",
+ f"hidden={args.hidden}",
+ f"topk={args.num_topk}",
+ f"scaleout={buffer.num_scaleout_ranks}",
+ f"scaleup={buffer.num_scaleup_ranks}",
+ f"dispatch_avg_ms={dispatch_avg_ms:.3f}",
+ f"combine_avg_ms={combine_avg_ms:.3f}",
+ f"recv_tokens_avg={table[:, 6].mean().item():.1f}",
+ f"effective_payload_MB_per_rank={payload_bytes / 1e6:.1f}",
+ f"dispatch_effective_GBps={payload_bytes / dispatch_avg_ms / 1e6:.2f}",
+ f"combine_effective_GBps={payload_bytes / combine_avg_ms / 1e6:.2f}",
+ flush=True,
+ )
+
+ dist.destroy_process_group()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_api.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_api.cuh
new file mode 100644
index 0000000000..aa99b8e0c9
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_api.cuh
@@ -0,0 +1,20 @@
+#pragma once
+
+// Official DeepEP elastic source import surface for Mooncake.
+//
+// This umbrella intentionally lives under include/elastic, not in the legacy EP
+// include root. It keeps the imported elastic implementation discoverable
+// while allowing the host launch/runtime glue to opt in file-by-file without
+// perturbing legacy Buffer dispatch/combine symbols.
+
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+#include
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_buffer.h b/mooncake-ep/include/elastic/mooncake_ep_elastic_buffer.h
new file mode 100644
index 0000000000..6b5dacdd07
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_buffer.h
@@ -0,0 +1,170 @@
+#ifndef MOONCAKE_EP_ELASTIC_BUFFER_H
+#define MOONCAKE_EP_ELASTIC_BUFFER_H
+
+#include
+#include
+#include
+#include
+#include
+#include
+
+#include
+
+namespace mooncake {
+
+struct ElasticLaunchContext;
+
+struct ElasticTopology {
+ int rank_idx = 0;
+ int num_ranks = 1;
+ int num_rdma_ranks = 1;
+ int num_nvlink_ranks = 1;
+ int num_scaleout_ranks = 1;
+ int num_scaleup_ranks = 1;
+ int scaleout_rank_idx = 0;
+ int scaleup_rank_idx = 0;
+ bool hybrid_enabled = false;
+};
+
+struct ElasticConfig {
+ int64_t num_max_tokens_per_rank = 0;
+ int64_t hidden = 0;
+ int64_t num_topk = 0;
+ bool use_fp8_dispatch = false;
+ bool deterministic = false;
+ bool allow_hybrid_mode = true;
+ bool allow_multiple_reduction = true;
+ bool prefer_overlap_with_compute = true;
+ int sl_idx = 3;
+ int num_allocated_qps = 0;
+ int num_cpu_timeout_secs = 300;
+ int num_gpu_timeout_secs = 100;
+};
+
+struct ElasticNativeHandle {
+ bool do_expand = false;
+ int num_experts = 0;
+ int expert_alignment = 1;
+ int num_max_tokens_per_rank = 0;
+ int num_sms = 0;
+ torch::Tensor topk_idx;
+ torch::Tensor psum_num_recv_tokens_per_scaleup_rank;
+ torch::Tensor psum_num_recv_tokens_per_expert;
+ torch::Tensor recv_src_metadata;
+ torch::Tensor recv_layout_range;
+ torch::Tensor dst_buffer_slot_idx;
+ std::optional token_metadata_at_forward;
+ std::optional channel_linked_list;
+ std::vector num_recv_tokens_per_expert_list;
+};
+
+struct ElasticDispatchOutput {
+ torch::Tensor recv_x;
+ std::optional recv_x_scales;
+ std::optional recv_topk_idx;
+ std::optional recv_topk_weights;
+ ElasticNativeHandle handle;
+ std::optional event;
+};
+
+struct ElasticCombineOutput {
+ torch::Tensor combined_x;
+ std::optional combined_topk_weights;
+ std::optional event;
+};
+
+class MooncakeElasticBuffer {
+ public:
+ MooncakeElasticBuffer(int rank, int num_ranks, int64_t num_buffer_bytes,
+ int64_t num_max_tokens_per_rank, int64_t hidden,
+ int64_t num_topk, bool use_fp8_dispatch,
+ bool deterministic, bool allow_hybrid_mode,
+ bool allow_multiple_reduction,
+ bool prefer_overlap_with_compute, int sl_idx,
+ int num_allocated_qps, int num_cpu_timeout_secs,
+ int num_gpu_timeout_secs);
+
+ ~MooncakeElasticBuffer();
+
+ static int64_t calculate_buffer_size(int num_ranks,
+ int64_t num_max_tokens_per_rank,
+ int64_t hidden, int64_t num_topk,
+ bool use_fp8_dispatch,
+ bool allow_hybrid_mode,
+ bool allow_multiple_reduction);
+
+ std::tuple get_physical_domain_size() const;
+ std::tuple get_logical_domain_size() const;
+ int get_theoretical_num_sms(int num_experts, int num_topk) const;
+
+ ElasticDispatchOutput dispatch(
+ const torch::Tensor& x, const std::optional& sf,
+ const torch::Tensor& topk_idx,
+ const std::optional& topk_weights,
+ torch::Tensor& active_ranks, int num_experts,
+ int num_max_tokens_per_rank, int expert_alignment, int num_sms,
+ bool do_expand, bool do_cpu_sync, bool async_with_compute_stream,
+ const std::optional& cached_handle = std::nullopt);
+
+ ElasticCombineOutput combine(
+ const torch::Tensor& x, const ElasticNativeHandle& handle,
+ const std::optional& topk_weights,
+ torch::Tensor& active_ranks, int num_sms,
+ bool async_with_compute_stream,
+ const std::optional& out);
+
+ MooncakeEpBuffer& native_buffer() { return *native_buffer_; }
+
+ bool ibgda_disabled() const { return native_buffer_->ibgda_disabled(); }
+ bool use_fast_path() { return native_buffer_->use_fast_path(); }
+ void update_local_qpns() { native_buffer_->update_local_qpns(); }
+ bool is_roce() const { return native_buffer_->is_roce(); }
+ void sync_ibgda_peers(const std::vector& remote_addrs,
+ const std::vector& remote_keys,
+ const std::vector>& peer_qpns,
+ const std::vector>& peer_lids,
+ const std::vector& subnet_prefixes,
+ const std::vector& interface_ids,
+ const std::vector& active_ranks_mask) {
+ native_buffer_->sync_ibgda_peers(remote_addrs, remote_keys, peer_qpns,
+ peer_lids, subnet_prefixes,
+ interface_ids, active_ranks_mask);
+ }
+ std::tuple get_mr_info() {
+ return native_buffer_->get_mr_info();
+ }
+ std::tuple get_gid() { return native_buffer_->get_gid(); }
+ std::vector get_local_qpns() {
+ return native_buffer_->get_local_qpns();
+ }
+ std::vector get_local_lids() {
+ return native_buffer_->get_local_lids();
+ }
+ std::vector get_ipc_handle() {
+ return native_buffer_->get_ipc_handle();
+ }
+ void sync_nvlink_ipc_handles(
+ const std::vector>& remote_handles,
+ const std::vector& active_ranks_mask) {
+ native_buffer_->sync_nvlink_ipc_handles(remote_handles,
+ active_ranks_mask);
+ }
+
+ private:
+ ElasticConfig config_;
+ ElasticTopology topology_;
+ std::unique_ptr native_buffer_;
+ int64_t host_workspace_bytes_ = 0;
+ void* host_workspace_ = nullptr;
+ void* mapped_host_workspace_ = nullptr;
+
+ static ElasticLaunchContext make_launch_context(
+ MooncakeEpBuffer& buffer, const ElasticTopology& topology,
+ void* mapped_host_workspace, int64_t timeout_cycles);
+ static ElasticTopology discover_topology(int rank, int num_ranks,
+ bool allow_hybrid_mode);
+};
+
+} // namespace mooncake
+
+#endif // MOONCAKE_EP_ELASTIC_BUFFER_H
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_official.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_official.cuh
new file mode 100644
index 0000000000..9e36b344f7
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_official.cuh
@@ -0,0 +1,365 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+
+#include
+#include
+#include
+#include
+
+#include
+
+namespace mooncake::elastic {
+
+template (),
+ int kNumTokensInLayout = get_num_tokens_in_layout<
+ kAllowMultipleReduction, kNumRanks, kNumTopk>(),
+ typename team_t = std::conditional_t<
+ kIsScaleupNVLink, transport::ScaleupTeam, transport::WorldTeam>>
+__global__ void __launch_bounds__(kNumThreads, 1)
+ combine_impl(nv_bfloat16* x, float* topk_weights, int* src_metadata,
+ int* psum_num_recv_tokens_per_scaleup_rank,
+ const device::CommCtx comm_ctx, void* buffer, void* workspace,
+ const int rank_idx, int num_reduced_tokens) {
+ // Utils
+ const auto sm_idx = static_cast(blockIdx.x);
+ const auto thread_idx = static_cast(threadIdx.x);
+ const auto warp_idx = (ptx::get_warp_idx() + rank_idx) % kNumWarps;
+ const auto lane_idx = ptx::get_lane_idx();
+ const auto global_warp_idx = warp_idx * kNumSMs + sm_idx;
+ constexpr bool kDoExpandedSend =
+ not kAllowMultipleReduction and kUseExpandedLayout;
+
+ // We should assign the real number of received tokens if without CPU sync
+ if (num_reduced_tokens == kNumMaxTokensPerRank * kNumRanks)
+ num_reduced_tokens =
+ __ldg(psum_num_recv_tokens_per_scaleup_rank + kNumRanks - 1);
+
+ // Buffer layouts
+ extern __shared__ __align__(ptx::kNumTMAAlignBytes) int8_t smem[];
+ const auto token_layout =
+ layout::TokenLayout(kNumHiddenBytes, 0, kNumTopk, false);
+ const auto tma_buffer =
+ layout::BufferLayout(token_layout, kNumWarps, 1, smem)
+ .get_rank_buffer(warp_idx)
+ .get_token_buffer(0);
+ const auto recv_buffer = layout::BufferLayout(
+ token_layout, kNumTokensInLayout, kNumMaxTokensPerRank, buffer);
+ const auto send_buffer = layout::BufferLayout(
+ token_layout, kNumRanks,
+ kNumMaxTokensPerRank * (kDoExpandedSend ? kNumTopk : 1),
+ recv_buffer.get_buffer_end_ptr());
+
+ // Init TMA
+ ptx::arrival_phase phase = 0;
+ const auto mbarrier_ptr = tma_buffer.get_mbarrier_ptr();
+ if (ptx::elect_one_sync()) ptx::mbarrier_init_with_fence(mbarrier_ptr, 1);
+ __syncwarp();
+
+ // Expanding mode must not be backward
+ if constexpr (kUseExpandedLayout) EP_DEVICE_ASSERT(topk_weights == nullptr);
+
+ // Gin handle
+ // We treat each warp as a "channel"
+ const auto [qp_idx, sharing_mode] =
+ comm::get_qp_mode(sm_idx, warp_idx);
+ const auto gin = transport::MooncakeGin(comm_ctx, qp_idx, sharing_mode,
+ kNumQPs, 0, 0, 0, kNumRanks);
+
+ // Full barrier to ensure the remote buffer is available
+ const auto workspace_layout =
+ layout::WorkspaceLayout(workspace, 1, kNumRanks, kNumExperts);
+ comm::gpu_barrier(gin, workspace_layout, 0, rank_idx, sm_idx,
+ thread_idx);
+
+ // Do TMA writes into the remote buffers
+ int num_tokens_per_warp =
+ math::ceil_div(num_reduced_tokens, kNumSMs * kNumWarps);
+ const int token_start_idx = num_tokens_per_warp * global_warp_idx;
+ const int token_end_idx =
+ min(token_start_idx + num_tokens_per_warp, num_reduced_tokens);
+ for (int i = token_start_idx; i < token_end_idx; ++i) {
+ // The master slot index during dispatch
+ constexpr int kMetadataStride = 2 + kNumTopk;
+ const int src_token_idx =
+ __ldg(src_metadata + i * kMetadataStride) % kNumMaxTokensPerRank;
+ const int src_rank_topk_idx =
+ __ldg(src_metadata + i * kMetadataStride + 1);
+ const int src_rank_idx = src_rank_topk_idx / kNumTopk;
+ const int src_topk_idx = src_rank_topk_idx % kNumTopk;
+
+ // Directly to the remote or via RDMA
+ const bool nvlink_bypass =
+ gin.is_nvlink_accessible(src_rank_idx);
+ layout::TokenLayout master_token_buffer = [=]() {
+ // NVLink bypass
+ if (nvlink_bypass) {
+ auto token_buffer =
+ recv_buffer
+ .get_rank_buffer(kUseRankLayout ? rank_idx
+ : src_topk_idx)
+ .get_token_buffer(src_token_idx);
+ token_buffer.set_base_ptr(gin.get_sym_ptr(
+ token_buffer.get_base_ptr(), src_rank_idx));
+ return token_buffer;
+ }
+
+ // Use RDMA
+ return send_buffer.get_rank_buffer(src_rank_idx)
+ .get_token_buffer(src_token_idx);
+ }();
+
+ // Hidden requirements
+ EP_STATIC_ASSERT(
+ kHidden % (32 * sizeof(int4) / sizeof(nv_bfloat16)) == 0,
+ "Invalid hidden");
+ using combine_vec_t =
+ typename CombineVecTraits::vec_t;
+ constexpr int kHiddenVec =
+ kHidden * sizeof(nv_bfloat16) / sizeof(combine_vec_t);
+
+ // Read source indices for expand mode
+ int stored_topk_slot_idx = -1;
+ if constexpr (kUseExpandedLayout) {
+ if (lane_idx < kNumTopk)
+ stored_topk_slot_idx =
+ __ldg(src_metadata + i * kMetadataStride + (2 + lane_idx));
+ __syncwarp();
+ }
+
+ // 3 cases:
+ // - no expand + no reduce, or expand + no reduce
+ // - expand + reduce
+ // - expand + send all
+ auto reduce_valid_mask = ptx::gather(stored_topk_slot_idx >= 0);
+ auto no_local_reduce =
+ not kUseExpandedLayout or
+ (kAllowMultipleReduction and __popc(reduce_valid_mask) == 1);
+ if (no_local_reduce) {
+ int token_idx_in_tensor = i;
+ if constexpr (kUseExpandedLayout)
+ token_idx_in_tensor =
+ ptx::exchange(stored_topk_slot_idx,
+ ptx::get_master_lane_idx(reduce_valid_mask));
+
+ // No reduce
+#ifdef MOONCAKE_EP_USE_MUSA
+ {
+ const auto src_ptr = math::advance_ptr(
+ x, static_cast(token_idx_in_tensor) *
+ kNumHiddenBytes);
+ auto* dst_ptr = static_cast(
+ master_token_buffer.get_base_ptr());
+#pragma unroll 1
+ for (int vec_idx = lane_idx; vec_idx < kHiddenVec;
+ vec_idx += 32) {
+ ptx::st_na(dst_ptr + vec_idx, src_ptr[vec_idx]);
+ }
+ __syncwarp();
+ __threadfence_system();
+ }
+#else
+ if (ptx::elect_one_sync()) {
+ const auto load_ptr = math::advance_ptr(
+ x, static_cast(token_idx_in_tensor) *
+ kNumHiddenBytes);
+ ptx::tma_store_wait();
+ ptx::tma_load_1d(tma_buffer.get_base_ptr(), load_ptr,
+ mbarrier_ptr, kNumHiddenBytes);
+ ptx::mbarrier_arrive_and_set_tx(mbarrier_ptr, kNumHiddenBytes);
+ ptx::mbarrier_wait_and_flip_phase(mbarrier_ptr, phase);
+ ptx::tma_store_1d(master_token_buffer.get_base_ptr(),
+ tma_buffer.get_base_ptr(), kNumHiddenBytes);
+ ptx::tma_store_commit();
+ }
+ __syncwarp();
+#endif
+ } else if constexpr (kAllowMultipleReduction) {
+ // Do local reduction
+ // Sort valid top-k indices to front
+ int topk_slot_idx[kNumTopk];
+ compute_topk_slots(
+ topk_slot_idx, reduce_valid_mask, [=](const int& idx) {
+ return ptx::exchange(stored_topk_slot_idx, idx);
+ });
+
+ // Reduce into shared memory
+ constexpr int kUnrollFactor =
+ get_max_unroll_factor();
+ combine_reduce(
+ lane_idx, topk_slot_idx,
+ static_cast(tma_buffer.get_base_ptr()),
+ /* Get source base */
+ [=](const int& slot_idx) {
+ return math::advance_ptr(
+ x, slot_idx * static_cast(kNumHiddenBytes));
+ },
+ /* Wait buffer release */
+ [=]() {
+ ptx::tma_store_wait();
+ __syncwarp();
+ });
+ ptx::tma_store_fence();
+ __syncwarp();
+
+ // Issue TMA stores
+#ifdef MOONCAKE_EP_USE_MUSA
+ {
+ const auto* src_ptr = static_cast(
+ tma_buffer.get_base_ptr());
+ auto* dst_ptr = static_cast(
+ master_token_buffer.get_base_ptr());
+#pragma unroll 1
+ for (int vec_idx = lane_idx; vec_idx < kHiddenVec;
+ vec_idx += 32) {
+ ptx::st_na(dst_ptr + vec_idx, src_ptr[vec_idx]);
+ }
+ __syncwarp();
+ __threadfence_system();
+ }
+#else
+ if (ptx::elect_one_sync()) {
+ ptx::tma_store_1d(master_token_buffer.get_base_ptr(),
+ tma_buffer.get_base_ptr(), kNumHiddenBytes);
+ ptx::tma_store_commit();
+ }
+ __syncwarp();
+#endif
+ } else {
+// No local reduction, send all data (expanded send)
+#pragma unroll
+ for (int k = 0; k < kNumTopk; ++k) {
+ const auto slot_idx = ptx::exchange(stored_topk_slot_idx, k);
+ if (slot_idx >= 0) {
+ const auto src_token_ptr = math::advance_ptr(
+ x, slot_idx * static_cast(kNumHiddenBytes));
+ const auto token_buffer =
+ recv_buffer.get_rank_buffer(k).get_token_buffer(
+ src_token_idx);
+#ifdef MOONCAKE_EP_USE_MUSA
+ if (nvlink_bypass) {
+ auto* dst_ptr =
+ static_cast(gin.get_sym_ptr(
+ token_buffer.get_base_ptr(), src_rank_idx));
+#pragma unroll 1
+ for (int vec_idx = lane_idx; vec_idx < kHiddenVec;
+ vec_idx += 32) {
+ ptx::st_na(dst_ptr + vec_idx,
+ src_token_ptr[vec_idx]);
+ }
+ } else {
+ const auto send_token_buffer =
+ send_buffer.get_rank_buffer(src_rank_idx)
+ .get_token_buffer(src_token_idx * kNumTopk + k);
+ auto* dst_ptr = static_cast(
+ send_token_buffer.get_base_ptr());
+#pragma unroll 1
+ for (int vec_idx = lane_idx; vec_idx < kHiddenVec;
+ vec_idx += 32) {
+ ptx::st_na(dst_ptr + vec_idx,
+ src_token_ptr[vec_idx]);
+ }
+ __syncwarp();
+ if (ptx::elect_one_sync()) {
+ gin.put(token_buffer.get_base_ptr(),
+ send_token_buffer.get_base_ptr(),
+ kNumHiddenBytes, src_rank_idx);
+ }
+ }
+ __syncwarp();
+ __threadfence_system();
+#else
+ if (ptx::elect_one_sync()) {
+ // Load
+ ptx::tma_store_wait();
+ ptx::tma_load_1d(tma_buffer.get_base_ptr(),
+ src_token_ptr, mbarrier_ptr,
+ kNumHiddenBytes);
+ ptx::mbarrier_arrive_and_set_tx(mbarrier_ptr,
+ kNumHiddenBytes);
+ ptx::mbarrier_wait_and_flip_phase(mbarrier_ptr, phase);
+
+ if (nvlink_bypass) {
+ // Write into the same position
+ ptx::tma_store_1d(
+ gin.get_sym_ptr(
+ token_buffer.get_base_ptr(), src_rank_idx),
+ tma_buffer.get_base_ptr(), kNumHiddenBytes);
+ ptx::tma_store_commit();
+ } else {
+ // Write to the RDMA send buffer
+ const auto send_token_buffer =
+ send_buffer.get_rank_buffer(src_rank_idx)
+ .get_token_buffer(src_token_idx * kNumTopk +
+ k);
+ ptx::tma_store_1d(send_token_buffer.get_base_ptr(),
+ tma_buffer.get_base_ptr(),
+ kNumHiddenBytes);
+ ptx::tma_store_commit();
+ ptx::tma_store_wait();
+
+ // Issue RDMA
+ gin.put(token_buffer.get_base_ptr(),
+ send_token_buffer.get_base_ptr(),
+ kNumHiddenBytes, src_rank_idx);
+ }
+ }
+ __syncwarp();
+#endif
+ }
+ }
+ }
+
+ // Write topk weights
+ if (not kUseExpandedLayout and topk_weights != nullptr and
+ lane_idx < kNumTopk) {
+ const float value = __ldg(topk_weights + (i * kNumTopk + lane_idx));
+#ifdef MOONCAKE_EP_USE_MUSA
+ ptx::st_relaxed_sys(
+ master_token_buffer.get_topk_weights_ptr() + lane_idx, value);
+#else
+ master_token_buffer.get_topk_weights_ptr()[lane_idx] = value;
+#endif
+ }
+ __syncwarp();
+#ifdef MOONCAKE_EP_USE_MUSA
+ __threadfence_system();
+#endif
+
+ // Wait send buffer's TMA store and issue RDMA send
+ // NOTES: `kDoExpandedSend` mode has already issued
+ if (not kDoExpandedSend and not nvlink_bypass and
+ ptx::elect_one_sync()) {
+ ptx::tma_store_wait();
+ const auto dst_ptr =
+ recv_buffer
+ .get_rank_buffer(kUseRankLayout ? rank_idx : src_topk_idx)
+ .get_token_buffer(src_token_idx)
+ .get_base_ptr();
+ gin.put(dst_ptr, master_token_buffer.get_base_ptr(),
+ master_token_buffer.get_num_bytes(),
+ src_rank_idx);
+ }
+ }
+
+ // Final barrier to ensure data arrival
+ comm::gpu_barrier(gin, workspace_layout, 0, rank_idx, sm_idx,
+ thread_idx);
+}
+
+} // namespace mooncake::elastic
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_reduce_epilogue.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_reduce_epilogue.cuh
new file mode 100644
index 0000000000..6e41aebab8
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_reduce_epilogue.cuh
@@ -0,0 +1,212 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+#include
+#include
+
+#include
+
+namespace mooncake::elastic {
+
+template (),
+ int kNumTokensInLayout = get_num_tokens_in_layout<
+ kAllowMultipleReduction, kNumRanks, kNumTopk>()>
+__global__ void __launch_bounds__(kNumThreads, 1)
+ combine_reduce_epilogue_impl(nv_bfloat16* combined_x,
+ float* combined_topk_weights,
+ topk_idx_t* combined_topk_idx,
+ void* recv_buffer, void* bias_0, void* bias_1,
+ const int num_combined_tokens,
+ const int scaleout_rank_idx,
+ const int scaleup_rank_idx) {
+ constexpr int kNumExpertsPerScaleout = kNumExperts / kNumScaleoutRanks;
+ constexpr int kNumExpertsPerRank =
+ kNumExperts / (kNumScaleupRanks * kNumScaleoutRanks);
+ EP_STATIC_ASSERT(kNumExperts % (kNumScaleupRanks * kNumScaleoutRanks) == 0,
+ "Invalid number of experts or ranks");
+
+ // Utils
+ const auto sm_idx = static_cast(blockIdx.x);
+ const auto warp_idx = ptx::get_warp_idx(), lane_idx = ptx::get_lane_idx();
+ const auto global_warp_idx =
+ warp_idx * kNumSMs +
+ sm_idx; // NOTES: Here we prioritize distributing tasks to different
+ // SMs to ensure that the last wave is evenly concentrated on
+ // each SM.
+
+ // Load buffers from scale-out or scale-up ranks
+ extern __shared__ __align__(ptx::kNumTMAAlignBytes) int8_t smem[];
+ const auto comm_token_layout =
+ layout::TokenLayout(kNumHiddenBytes, 0, kNumTopk, false);
+ const auto comm_buffer =
+ layout::BufferLayout(comm_token_layout, kNumTokensInLayout,
+ kNumMaxTokensPerRank, recv_buffer);
+
+ // Store buffers
+ const auto output_token_layout =
+ layout::TokenLayout(kNumHiddenBytes, 0, 0, false);
+ const auto output_buffer = layout::BufferLayout(
+ output_token_layout, 1, num_combined_tokens, combined_x);
+ const auto tma_buffer =
+ layout::BufferLayout(output_token_layout, kNumWarps, 1, smem)
+ .get_rank_buffer(warp_idx)
+ .get_token_buffer(0);
+
+ // Bias layout
+ const auto bias_0_buffer = layout::BufferLayout(
+ output_token_layout, 1, num_combined_tokens, bias_0);
+ const auto bias_1_buffer = layout::BufferLayout(
+ output_token_layout, 1, num_combined_tokens, bias_1);
+
+ // Will block until the main combine kernel has finished and all data are
+ // visible NOTES: PDL is used, please do not use `__ldg`
+#if !defined(MOONCAKE_EP_USE_MUSA) && defined(__CUDA_ARCH__) && \
+ (__CUDA_ARCH__ >= 900)
+ cudaGridDependencySynchronize();
+#endif
+
+ // Read from buffers and do reduction
+ for (int token_idx = global_warp_idx; token_idx < num_combined_tokens;
+ token_idx += kNumWarps * kNumSMs) {
+ // Preprocess all indices
+ int stored_dst_rank_idx = -1, stored_dst_expert_idx = -1;
+ EP_STATIC_ASSERT(kNumTopk <= 32, "Too many top-k selections");
+ if (lane_idx < kNumTopk) {
+ stored_dst_expert_idx = static_cast(
+ combined_topk_idx[token_idx * kNumTopk + lane_idx]);
+ stored_dst_rank_idx =
+ stored_dst_expert_idx >= 0
+ ? stored_dst_expert_idx / (kNumScaleoutRanks == 1
+ ? kNumExpertsPerRank
+ : kNumExpertsPerScaleout)
+ : -1;
+ }
+ __syncwarp();
+
+ // Sort valid top-k indices to front
+ const auto [should_deduplicate,
+ deduplicate_key] = [&]() -> std::pair {
+ if constexpr (kUseExpandedLayout and not kAllowMultipleReduction) {
+ // Activations are never reduced before
+ return {false, 0};
+ } else if constexpr (kNumScaleoutRanks != 1 and
+ not kUseExpandedLayout and
+ not kAllowMultipleReduction) {
+ // Hybrid mode without expanded layout and multiple reduction.
+ // Should deduplicate on a per-rank basis
+ return {true, stored_dst_expert_idx >= 0
+ ? stored_dst_expert_idx / kNumExpertsPerRank
+ : -1};
+ } else {
+ // Should deduplicate on a per-rank (for non-hybrid mode) or a
+ // per-scale-rank (for hybrid mode) basis
+ return {true, stored_dst_rank_idx};
+ }
+ }();
+ auto reduce_valid_mask =
+ should_deduplicate
+ ? ptx::gather(ptx::deduplicate(deduplicate_key, lane_idx) and
+ stored_dst_rank_idx >= 0)
+ : ptx::gather(stored_dst_rank_idx >= 0);
+ int topk_slot_idx[kNumTokensInLayout];
+ compute_topk_slots(
+ topk_slot_idx, reduce_valid_mask, [=](const int& idx) {
+ return kUseRankLayout ? ptx::exchange(stored_dst_rank_idx, idx)
+ : idx;
+ });
+
+ // Iterate over per-hidden-chunk stage
+ using combine_vec_t =
+ typename CombineVecTraits::vec_t;
+ constexpr int kHiddenVec =
+ kHidden * sizeof(nv_bfloat16) / sizeof(combine_vec_t);
+ constexpr int kUnrollFactor = get_max_unroll_factor();
+ combine_reduce(
+ lane_idx, topk_slot_idx,
+ static_cast(tma_buffer.get_base_ptr()),
+ /* Get source base */
+ [=](const int& slot_idx) {
+ return static_cast(
+ comm_buffer.get_rank_buffer(slot_idx)
+ .get_token_buffer(token_idx)
+ .get_base_ptr());
+ },
+ /* Wait buffer release */
+ [=]() {
+ ptx::tma_store_wait();
+ __syncwarp();
+ },
+ /* Bias 0 */ bias_0 == nullptr
+ ? nullptr
+ : static_cast(
+ bias_0_buffer.get_token_buffer(token_idx).get_base_ptr()),
+ /* Bias 1 */ bias_1 == nullptr
+ ? nullptr
+ : static_cast(
+ bias_1_buffer.get_token_buffer(token_idx)
+ .get_base_ptr()));
+ ptx::tma_store_fence();
+ __syncwarp();
+
+ // Issue TMA copy
+#ifdef MOONCAKE_EP_USE_MUSA
+ {
+ const auto* src_ptr =
+ static_cast(tma_buffer.get_base_ptr());
+ auto* dst_ptr = static_cast(
+ output_buffer.get_token_buffer(token_idx).get_base_ptr());
+#pragma unroll 1
+ for (int vec_idx = lane_idx; vec_idx < kHiddenVec; vec_idx += 32) {
+ dst_ptr[vec_idx] = src_ptr[vec_idx];
+ }
+ __syncwarp();
+ }
+#else
+ if (ptx::elect_one_sync()) {
+ ptx::tma_store_1d(
+ output_buffer.get_token_buffer(token_idx).get_base_ptr(),
+ tma_buffer.get_base_ptr(), kNumHiddenBytes);
+ ptx::tma_store_commit();
+ }
+ __syncwarp();
+#endif
+
+ // Write top-k weights
+ if (combined_topk_weights != nullptr) {
+ const auto master_lane_idx =
+ ptx::get_master_lane_idx(ptx::match(stored_dst_rank_idx));
+ if (lane_idx < kNumTopk) {
+ float value = 0;
+ if (stored_dst_rank_idx >= 0) {
+ const auto dst_ptr =
+ comm_buffer
+ .get_rank_buffer(kUseRankLayout
+ ? stored_dst_rank_idx
+ : master_lane_idx)
+ .get_token_buffer(token_idx)
+ .get_topk_weights_ptr() +
+ lane_idx;
+ value = *dst_ptr;
+ }
+ combined_topk_weights[token_idx * kNumTopk + lane_idx] = value;
+ }
+ __syncwarp();
+ }
+ }
+}
+
+} // namespace mooncake::elastic
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_utils.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_utils.cuh
new file mode 100644
index 0000000000..b2e3623f2a
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_combine_utils.cuh
@@ -0,0 +1,209 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+
+namespace mooncake::elastic {
+
+template
+constexpr bool use_rank_layout() {
+ if constexpr (not kAllowMultipleReduction) return false;
+ return kNumRanks <= kNumTopk;
+}
+
+template
+constexpr int get_num_tokens_in_layout() {
+ return use_rank_layout()
+ ? kNumRanks
+ : kNumTopk;
+}
+
+template
+constexpr int get_max_unroll_factor() {
+ for (int i = kMaxUnrollFactor; i >= 1; --i)
+ if (kLength % (kWarpSize * i) == 0) return i;
+#ifdef MOONCAKE_EP_USE_MUSA
+ return 1;
+#else
+ throw std::logic_error("Invalid length, cannot find unrolling factor");
+#endif
+}
+
+// Determine the vector type for combine loads/stores based on arch and hidden
+// size alignment
+template
+struct CombineVecTraits {
+#if !defined(MOONCAKE_EP_USE_MUSA) && defined(__CUDA_ARCH__) && \
+ (__CUDA_ARCH__ >= 1000)
+ // On SM100+, use longlong4_t (32 bytes) if hidden is aligned, otherwise
+ // fall back to int4 (16 bytes)
+ static constexpr bool kUseLonglong4 =
+ (kHiddenBytes % sizeof(longlong4_t) == 0) and
+ ((kHiddenBytes / sizeof(longlong4_t)) % 32 == 0);
+ using vec_t = std::conditional_t;
+#else
+ using vec_t = int4;
+#endif
+};
+
+template
+__device__ __forceinline__ void compute_topk_slots(
+ int (&topk_slot_idx)[kNumValidTopk], uint32_t mask,
+ const fetch_func_t& fetch_func) {
+#pragma unroll
+ for (int k = 0; k < kNumValidTopk; ++k) {
+ const int lowest_idx = __ffs(mask) - 1;
+ // Here we perform the exchange unconditionally to avoid `BRA.DIV`
+ const auto fetched = fetch_func(lowest_idx);
+ mask &= mask - 1;
+ topk_slot_idx[k] = lowest_idx >= 0 ? fetched : -1;
+ }
+}
+
+template
+__device__ __forceinline__ void combine_reduce(
+ const int& lane_idx, int (&topk_slot_idx)[kNumValidTopk],
+ vec_t* dst_buffer_ptr,
+ const get_src_buffer_ptr_func_t& get_src_buffer_ptr_func,
+ const wait_buffer_func_t& wait_buffer_func, vec_t* bias_0 = nullptr,
+ vec_t* bias_1 = nullptr) {
+ constexpr int kNumElemsPerVec = sizeof(vec_t) / sizeof(nv_bfloat16);
+ EP_STATIC_ASSERT(kNumElemsPerVec % 2 == 0, "Invalid number of elements");
+ EP_STATIC_ASSERT(kHiddenVec % (kUnrollFactor * 32) == 0,
+ "Invalid unrolling");
+
+ // We use BF16 add as much as possible, as casting is slow
+ const bool enable_hadd_bypass =
+ (bias_0 == nullptr and bias_1 == nullptr) and
+ (kNumValidTopk <= 2 or topk_slot_idx[2] < 0);
+ EP_STATIC_ASSERT(kNumValidTopk > 0, "Invalid top-k");
+
+ if (enable_hadd_bypass) {
+#pragma unroll 1
+ for (int i = 0; i < kHiddenVec / (kUnrollFactor * 32); ++i) {
+ // Read values 0
+ const auto slot_0 = topk_slot_idx[0];
+ const auto src_base_ptr_0 = get_src_buffer_ptr_func(slot_0);
+ vec_t values_0[kUnrollFactor] = {};
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j) {
+ values_0[j] = ptx::ldg_with_gez_pred(
+ src_base_ptr_0 +
+ (i * (kUnrollFactor * 32) + j * 32 + lane_idx),
+ slot_0);
+ }
+
+ // Read values 1
+ vec_t values_1[kUnrollFactor] = {};
+ const auto slot_1 = kNumValidTopk == 1 ? -1 : topk_slot_idx[1];
+ const auto src_base_ptr_1 = get_src_buffer_ptr_func(slot_1);
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j) {
+ values_1[j] = ptx::ldg_with_gez_pred(
+ src_base_ptr_1 +
+ (i * (kUnrollFactor * 32) + j * 32 + lane_idx),
+ slot_1);
+ }
+
+ // Wait buffer releases for the first write
+ if (i == 0) wait_buffer_func();
+
+ // Reduce into shared memory
+ const auto bf162_view_0 = reinterpret_cast(values_0);
+ const auto bf162_view_1 = reinterpret_cast(values_1);
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j) {
+#pragma unroll
+ for (int l = 0; l < kNumElemsPerVec / 2; ++l) {
+ const int idx = j * (kNumElemsPerVec / 2) + l;
+#ifdef MOONCAKE_EP_USE_MUSA
+ bf162_view_0[idx] = __floats2bfloat162_rn(
+ __low2float(bf162_view_0[idx]) +
+ __low2float(bf162_view_1[idx]),
+ __high2float(bf162_view_0[idx]) +
+ __high2float(bf162_view_1[idx]));
+#else
+ bf162_view_0[idx] += bf162_view_1[idx];
+#endif
+ }
+ dst_buffer_ptr[i * (kUnrollFactor * 32) + j * 32 + lane_idx] =
+ values_0[j];
+ }
+ }
+ } else {
+#pragma unroll 1
+ for (int i = 0; i < kHiddenVec / (kUnrollFactor * 32); ++i) {
+ // Add bias
+ float2 reduced[kUnrollFactor * kNumElemsPerVec / 2] = {};
+ const auto add_bias = [&](const vec_t* base_ptr) {
+ // Read
+ vec_t values[kUnrollFactor];
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j)
+ values[j] = ptx::ldg(base_ptr + i * (kUnrollFactor * 32) +
+ j * 32 + lane_idx);
+
+ // Reduce
+ const auto bf162_view = reinterpret_cast(values);
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor * kNumElemsPerVec / 2; ++j)
+ ptx::accumulate(reduced[j], bf162_view[j]);
+ };
+ bias_0 != nullptr ? add_bias(bias_0) : void();
+ bias_1 != nullptr ? add_bias(bias_1) : void();
+
+#pragma unroll
+ for (int k = 0; k < kNumValidTopk; ++k) {
+ // We have a limitation on `k` to reduce the branch instruction
+ // count
+ if (k >= kNumExpectedTopk and topk_slot_idx[k] < 0) break;
+
+ // Read values
+ const auto src_base_ptr =
+ get_src_buffer_ptr_func(topk_slot_idx[k]);
+ vec_t values[kUnrollFactor] = {};
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j) {
+ values[j] = ptx::ldg_with_gez_pred(
+ src_base_ptr +
+ (i * (kUnrollFactor * 32) + j * 32 + lane_idx),
+ topk_slot_idx[k]);
+ }
+
+ // Reduce
+ const auto bf162_view = reinterpret_cast(values);
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor * kNumElemsPerVec / 2; ++j)
+ ptx::accumulate(reduced[j], bf162_view[j]);
+ }
+
+ // Wait buffer releases for the first write
+ if (i == 0) wait_buffer_func();
+
+// Cast into shared memory
+#pragma unroll
+ for (int j = 0; j < kUnrollFactor; ++j) {
+ vec_t casted_value;
+ auto bf162_view =
+ reinterpret_cast(&casted_value);
+#pragma unroll
+ for (int l = 0; l < kNumElemsPerVec / 2; ++l) {
+ const auto value = reduced[j * (kNumElemsPerVec / 2) + l];
+#ifdef MOONCAKE_EP_USE_MUSA
+ bf162_view[l] = __floats2bfloat162_rn(value.x, value.y);
+#else
+ bf162_view[l] = __float22bfloat162_rn(value);
+#endif
+ }
+ dst_buffer_ptr[i * (kUnrollFactor * 32) + j * 32 + lane_idx] =
+ casted_value;
+ }
+ }
+ }
+}
+
+} // namespace mooncake::elastic
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_comm.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_comm.cuh
new file mode 100644
index 0000000000..886c2f12d8
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_comm.cuh
@@ -0,0 +1,190 @@
+#pragma once
+
+#include
+#include
+
+#include
+#include
+#include
+
+namespace mooncake::elastic::comm {
+
+static constexpr int64_t kNumOneSecCycles = 2000000000;
+
+static constexpr int kDeviceBarrierTag = 0;
+static constexpr int kKernelBarrierTag = 1;
+static constexpr int kDispatchTag0 = 2;
+static constexpr int kDispatchTag1 = 3;
+static constexpr int kCombineTag0 = 4;
+static constexpr int kCombineTag1 = 5;
+static constexpr int kHybridDispatchTag0 = 6;
+static constexpr int kHybridDispatchTag1 = 7;
+static constexpr int kHybridCombineTag0 = 8;
+static constexpr int kHybridCombineTag1 = 9;
+
+static constexpr int kFlushAllAllocatedQPs = -1;
+
+template
+__device__ __forceinline__ void timeout_while(const bool& condition,
+ const func_t& func,
+ int64_t start_clock = 0) {
+ if (start_clock == 0) start_clock = clock64();
+ while (condition) {
+ const bool timeout = kNumTimeoutCycles >= 0 &&
+ (clock64() - start_clock >= kNumTimeoutCycles);
+ if (func(timeout)) break;
+ if (timeout) {
+ const auto timeout_start = clock64();
+ while (clock64() - timeout_start < kNumOneSecCycles) {
+ }
+ ptx::trap();
+ }
+ }
+}
+
+template
+__device__ __forceinline__ void timeout_while(const func_t& func,
+ const int64_t& start_clock = 0) {
+ timeout_while(true, func, start_clock);
+}
+
+template
+__forceinline__ __device__ void local_grid_sync(
+ const layout::WorkspaceLayout& workspace, const int& thread_idx) {
+#ifdef MOONCAKE_EP_USE_MUSA
+ (void)kNumThreads;
+ __shared__ unsigned long long ticket;
+ __syncthreads();
+ if (thread_idx == 0) {
+ ticket = atomicAdd(
+ workspace.get_nvl_barrier_counter_ptr(kKernelBarrierTag), 1ULL);
+ }
+ __syncthreads();
+ const auto target = ((ticket / kNumSMs) + 1ULL) * kNumSMs;
+ timeout_while(thread_idx == 0, [=](const bool&) {
+ return ptx::ld_volatile(
+ workspace.get_nvl_barrier_counter_ptr(kKernelBarrierTag)) >=
+ target;
+ });
+ __syncthreads();
+#else
+ (void)workspace;
+ (void)thread_idx;
+ (gridDim.x > 1) ? cooperative_groups::this_grid().sync() : __syncthreads();
+#endif
+}
+
+template
+__device__ __forceinline__ std::pair get_qp_mode(
+ const int& sm_idx, const int& channel_in_sm_idx,
+ const bool& is_notify_warp = false) {
+ if constexpr (kNumQPs == 1) return {0, 1};
+ if (is_notify_warp) return {0, 0};
+
+ constexpr int kQPStartIdx = static_cast(kWithNotifyWarps);
+ constexpr int kNumAvailableQPs = kNumQPs - kQPStartIdx;
+ if constexpr (kNumSMs <= kNumAvailableQPs) {
+ const int num_qps_in_sm = (kNumAvailableQPs / kNumSMs) +
+ (sm_idx < (kNumAvailableQPs % kNumSMs));
+ return {kQPStartIdx + sm_idx +
+ (channel_in_sm_idx % max(1, num_qps_in_sm)) * kNumSMs,
+ 0};
+ } else {
+ const auto global_channel_idx =
+ sm_idx * kNumChannelsPerSM + channel_in_sm_idx;
+ return {kQPStartIdx + (global_channel_idx % max(1, kNumAvailableQPs)),
+ 1};
+ }
+}
+
+template
+__forceinline__ __device__ void mooncake_barrier_wo_local_sync(
+ const transport::MooncakeGin& gin, const layout::WorkspaceLayout& workspace,
+ const int& rank_idx, const int& sm_idx, const int& thread_idx) {
+ if (kNumSMs > 1 && sm_idx > 0) return;
+
+ const int status =
+ static_cast((*workspace.get_nvl_barrier_counter_ptr(kTag)) & 3);
+ const int phase = status & 1;
+ const int sign = status >> 1;
+ const int* base_signal = workspace.get_nvl_barrier_signal_ptr(kTag, phase);
+
+ if (thread_idx < kNumRanks) {
+ auto* dst_ptr = const_cast(base_signal) + rank_idx;
+ gin.red_add_rel(dst_ptr, sign ? -1 : 1, thread_idx);
+ }
+ __syncthreads();
+
+ if (thread_idx == 0)
+ atomicAdd(workspace.get_nvl_barrier_counter_ptr(kTag), 1ULL);
+
+ timeout_while(
+ thread_idx == 0, [=](const bool& is_last_check) {
+ int sum = 0;
+#pragma unroll
+ for (int i = 0; i < kNumRanks; ++i) {
+ sum +=
+ ptx::ld_acquire_sys(const_cast(base_signal) + i);
+ }
+ // Mooncake's portable barrier uses one additive slot per source
+ // rank. Each positive phase adds +1 into a zeroed phase slot; the
+ // matching negative phase later adds -1 into the same phase slot.
+ // This matches RDMA atomic-add semantics and avoids relying on a
+ // remote store primitive for non-P2P peers.
+ const auto target = sign ? 0 : kNumRanks;
+ if (sum == target) return true;
+ if (is_last_check) {
+ printf(
+ "Mooncake elastic barrier timeout, tag: %d, rank: %d, "
+ "signal-sum: %d, target: %d\n",
+ kTag, rank_idx, sum, target);
+ }
+ return false;
+ });
+}
+
+template
+__forceinline__ __device__ void gpu_barrier(
+ const transport::MooncakeGin& gin, const layout::WorkspaceLayout& workspace,
+ const int& scaleout_rank_idx, const int& scaleup_rank_idx,
+ const int& sm_idx, const int& thread_idx, bool do_scaleout = true,
+ bool do_scaleup = true) {
+ if constexpr (kFlushStores) gin.flush();
+ if constexpr (kSyncAtStart) {
+ local_grid_sync(workspace,
+ thread_idx);
+ }
+
+ do_scaleout &= kNumScaleoutRanks > 1;
+ do_scaleup &= kNumScaleupRanks > 1;
+ if (do_scaleup && !do_scaleout) {
+ mooncake_barrier_wo_local_sync(gin, workspace, scaleup_rank_idx,
+ sm_idx, thread_idx);
+ } else if (do_scaleout && !do_scaleup) {
+ mooncake_barrier_wo_local_sync(
+ gin, workspace, scaleout_rank_idx, sm_idx, thread_idx);
+ } else {
+ const int global_rank =
+ scaleout_rank_idx * kNumScaleupRanks + scaleup_rank_idx;
+ mooncake_barrier_wo_local_sync<
+ transport::WorldTeam, kNumScaleoutRanks * kNumScaleupRanks, kNumSMs,
+ kNumThreads, kNumTimeoutCycles, kTag>(gin, workspace, global_rank,
+ sm_idx, thread_idx);
+ }
+
+ if constexpr (kSyncAtEnd) {
+ local_grid_sync(workspace,
+ thread_idx);
+ }
+}
+
+} // namespace mooncake::elastic::comm
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_compiled.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_compiled.cuh
new file mode 100644
index 0000000000..1850361106
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_compiled.cuh
@@ -0,0 +1,115 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+// Make CLion CUDA indexing work
+#ifdef __CLION_IDE__
+#define __CUDA_ARCH__ 900
+#define __CUDACC_RDC__
+#define __CUDACC__
+#endif
+
+// Remove Torch restrictions
+#ifdef __CUDA_NO_HALF_CONVERSIONS__
+#undef __CUDA_NO_HALF_CONVERSIONS__
+#endif
+#ifdef __CUDA_NO_HALF_OPERATORS__
+#undef __CUDA_NO_HALF_OPERATORS__
+#endif
+#ifdef __CUDA_NO_HALF2_OPERATORS__
+#undef __CUDA_NO_HALF2_OPERATORS__
+#endif
+#ifdef __CUDA_NO_BFLOAT16_CONVERSIONS__
+#undef __CUDA_NO_BFLOAT16_CONVERSIONS__
+#endif
+#ifdef __CUDA_NO_BFLOAT162_OPERATORS__
+#undef __CUDA_NO_BFLOAT162_OPERATORS__
+#endif
+
+#include
+#include
+#include
+
+#if defined(MOONCAKE_EP_USE_MUSA) && defined(__MCC__) && \
+ !defined(MOONCAKE_EP_MUSA_LDG_DEFINED)
+#define MOONCAKE_EP_MUSA_LDG_DEFINED
+template
+__device__ __forceinline__ dtype_t __ldg(const dtype_t* ptr) {
+ return *ptr;
+}
+#endif
+
+#ifndef DISABLE_SM90_FEATURES
+#include
+#elif !defined(MOONCAKE_EP_USE_MUSA)
+// Ampere does not support FP8 features
+#define __NV_E4M3 0
+#define __NV_E5M2 1
+typedef int __nv_fp8_interpretation_t;
+typedef int __nv_fp8x4_e4m3;
+typedef uint8_t __nv_fp8_storage_t;
+#endif
+
+// Compatibility: 256 bits LD/ST instructions
+#if !defined(MOONCAKE_EP_USE_MUSA) && defined(CUDART_VERSION) and \
+ CUDART_VERSION >= 13000
+using longlong4_t = longlong4_32a;
+#define make_longlong4_t make_longlong4_32a
+#else
+struct alignas(32) longlong4_t {
+ long long x, y, z, w;
+};
+__device__ __forceinline__ longlong4_t make_longlong4_t(const long long& x,
+ const long long& y,
+ const long long& z,
+ const long long& w) {
+ return {x, y, z, w};
+}
+#endif
+
+#ifndef EP_NUM_TOPK_IDX_BITS
+#define EP_NUM_TOPK_IDX_BITS 64
+#endif
+
+namespace mooncake {
+
+#ifndef DISABLE_SM90_FEATURES
+constexpr bool kEnableSM90Features = true;
+#else
+constexpr bool kEnableSM90Features = false;
+#endif
+
+template
+struct int_with_bits;
+template <>
+struct int_with_bits<8> {
+ using type = int8_t;
+};
+template <>
+struct int_with_bits<16> {
+ using type = int16_t;
+};
+template <>
+struct int_with_bits<32> {
+ using type = int32_t;
+};
+template <>
+struct int_with_bits<64> {
+ using type = int64_t;
+};
+
+using topk_idx_t = int_with_bits::type;
+
+union sf_pack_t {
+ float fp32;
+ int ue8m0x4;
+};
+
+constexpr int kNumTMAAlignedBytes = 16;
+constexpr int kNumAlignedSFPacks = 16 / sizeof(sf_pack_t);
+
+// Some communication channel settings
+constexpr int kNumMaxChannels = 1024;
+
+} // namespace mooncake
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_copy_epilogue.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_copy_epilogue.cuh
new file mode 100644
index 0000000000..47cfca8401
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_copy_epilogue.cuh
@@ -0,0 +1,277 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+#include
+#include
+#include
+
+namespace mooncake::elastic {
+
+template <
+ bool kDoExpand, bool kCachedMode,
+ // NOTES: this channel concept only applies for scale-out ranks
+ int kNumSMs, int kNumChannels, int kNumWarps, int kNumScaleoutRanks,
+ int kNumScaleupRanks, int kNumHiddenBytes, int kNumSFPacks,
+ int kNumMaxTokensPerRank, int kNumExperts, int kNumTopk,
+ int kNumRanks = kNumScaleoutRanks * kNumScaleupRanks,
+ int kNumThreads = kNumWarps * 32,
+ int kNumMaxTokensPerChannel = math::constexpr_ceil_div(kNumMaxTokensPerRank,
+ kNumChannels),
+ bool kDoCreateLinkedList = (kNumScaleoutRanks > 1 and not kCachedMode)>
+__global__ void __launch_bounds__(kNumThreads, 1) dispatch_copy_epilogue_impl(
+ void* buffer, void* workspace, int* psum_num_recv_tokens_per_scaleup_rank,
+ int* psum_num_recv_tokens_per_expert, void* recv_x, sf_pack_t* recv_sf,
+ topk_idx_t* recv_topk_idx, float* recv_topk_weights, int* recv_src_metadata,
+ int* channel_linked_list, int num_recv_tokens,
+ const int recv_sf_token_stride, const int recv_sf_hidden_stride,
+ const int scaleout_rank_idx, const int scaleup_rank_idx) {
+ // Utils
+ const auto sm_idx = static_cast(blockIdx.x),
+ thread_idx = static_cast(threadIdx.x);
+ const auto warp_idx = ptx::get_warp_idx(), lane_idx = ptx::get_lane_idx();
+ const auto global_warp_idx = warp_idx * kNumSMs + sm_idx;
+
+ // For top-k index transformations
+ constexpr int kNumExpertsPerRank = kNumExperts / kNumRanks;
+ const auto rank_idx =
+ scaleout_rank_idx * kNumScaleupRanks + scaleup_rank_idx;
+ const auto expert_start_idx = kNumExpertsPerRank * rank_idx,
+ expert_end_idx = kNumExpertsPerRank * (rank_idx + 1);
+
+ // Buffer layouts
+ extern __shared__ __align__(ptx::kNumTMAAlignBytes) int8_t smem[];
+ const auto token_layout = layout::TokenLayout(
+ kNumHiddenBytes, kNumSFPacks * sizeof(sf_pack_t), kNumTopk, true);
+ const auto tma_buffer =
+ layout::BufferLayout(token_layout, kNumWarps, 1, smem)
+ .get_rank_buffer(warp_idx)
+ .get_token_buffer(0);
+ const auto scaleup_buffer = layout::BufferLayout(
+ token_layout, kNumScaleupRanks,
+ kNumScaleoutRanks * kNumMaxTokensPerRank, buffer);
+
+ // Init TMA
+ ptx::arrival_phase phase = 0;
+ const auto mbarrier_ptr = tma_buffer.get_mbarrier_ptr();
+ if (ptx::elect_one_sync()) ptx::mbarrier_init_with_fence(mbarrier_ptr, 1);
+ __syncwarp();
+
+ // Will block until the main dispatch kernel has finished and all data are
+ // visible NOTES: PDL is used, please do not use `__ldg`
+#if !defined(MOONCAKE_EP_USE_MUSA) && defined(__CUDA_ARCH__) && \
+ (__CUDA_ARCH__ >= 900)
+ cudaGridDependencySynchronize();
+#endif
+
+ // For no CPU sync case, the number of received tokens should be read from
+ // the GPU tensor
+ if (num_recv_tokens == kNumMaxTokensPerRank * kNumRanks)
+ num_recv_tokens =
+ psum_num_recv_tokens_per_scaleup_rank[kNumScaleupRanks - 1];
+
+ // Current rank indices should be maintained
+ int current_rank_idx = -1, stored_psum_num_recv_tokens;
+ int current_rank_start = 0, current_rank_end = 0;
+#pragma unroll
+ for (int i = global_warp_idx; i < num_recv_tokens;
+ i += kNumWarps * kNumSMs) {
+ // Calculate token index in the buffer
+ while (i >= current_rank_end) {
+ current_rank_idx += 1;
+ EP_DEVICE_ASSERT(current_rank_idx < kNumScaleupRanks);
+ const auto stored_lane_idx = current_rank_idx % 32;
+ if (stored_lane_idx == 0 and
+ current_rank_idx + lane_idx < kNumScaleupRanks)
+ stored_psum_num_recv_tokens =
+ psum_num_recv_tokens_per_scaleup_rank[current_rank_idx +
+ lane_idx];
+ current_rank_start = current_rank_end;
+ current_rank_end =
+ ptx::exchange(stored_psum_num_recv_tokens, stored_lane_idx);
+ }
+ const auto buffer_token =
+ scaleup_buffer.get_rank_buffer(current_rank_idx)
+ .get_token_buffer(i - current_rank_start);
+
+ // Wait buffer releases
+ ptx::tma_store_wait();
+ __syncwarp();
+
+ // Issue TMA loads
+ // Including all stuffs: data, SF, top-k metadata
+ if (ptx::elect_one_sync()) {
+ ptx::tma_load_1d(tma_buffer.get_base_ptr(),
+ buffer_token.get_base_ptr(), mbarrier_ptr,
+ tma_buffer.get_num_bytes());
+ ptx::mbarrier_arrive_and_set_tx(mbarrier_ptr,
+ tma_buffer.get_num_bytes());
+ }
+ __syncwarp();
+
+ // Load target expert indices separately to tolerate TMA load latency
+ EP_STATIC_ASSERT(kNumTopk <= 32, "Too many top-k selections");
+ int dst_expert_idx = -1;
+ if (lane_idx < kNumTopk)
+ dst_expert_idx = buffer_token.get_topk_idx_ptr()[lane_idx];
+ __syncwarp();
+
+ // Validate target expert indices and store for non-expand mode
+ const auto in_range = expert_start_idx <= dst_expert_idx and
+ dst_expert_idx < expert_end_idx;
+ const auto master_src_topk_idx =
+ ptx::get_master_lane_idx(ptx::gather(in_range));
+ dst_expert_idx = in_range ? dst_expert_idx - expert_start_idx : -1;
+ EP_DEVICE_ASSERT(ptx::deduplicate(dst_expert_idx, lane_idx) or
+ dst_expert_idx == -1);
+ if (not kDoExpand and lane_idx < kNumTopk)
+ recv_topk_idx[i * kNumTopk + lane_idx] =
+ static_cast(dst_expert_idx);
+ __syncwarp();
+
+ // Calculate target indices in the tensor
+ int dst_tensor_idx = -1;
+ if (not kDoExpand and ptx::elect_one_sync()) {
+ dst_tensor_idx = i;
+ } else if (kDoExpand and dst_expert_idx >= 0) {
+ dst_tensor_idx =
+ atomicAdd(psum_num_recv_tokens_per_expert + dst_expert_idx, 1);
+ }
+ __syncwarp();
+
+ // Wait for TMA arrival
+ if (ptx::elect_one_sync())
+ ptx::mbarrier_wait_and_flip_phase(mbarrier_ptr, phase);
+ __syncwarp();
+
+ // Maintain linked list
+ if constexpr (kDoCreateLinkedList) {
+ if (ptx::elect_one_sync())
+ channel_linked_list[tma_buffer.get_linked_list_idx_ptr()
+ [master_src_topk_idx]] = i;
+ __syncwarp();
+ }
+
+ // Issue TMA stores for data
+ if (kDoExpand ? (dst_tensor_idx >= 0) : ptx::elect_one_sync()) {
+ ptx::tma_store_1d(
+ math::advance_ptr(recv_x, static_cast(dst_tensor_idx) *
+ kNumHiddenBytes),
+ tma_buffer.get_hidden_ptr(), kNumHiddenBytes);
+ ptx::tma_store_commit();
+ }
+ __syncwarp();
+
+ // Store SF
+ if constexpr (kNumSFPacks > 0) {
+ constexpr auto kNumFullIters = kNumSFPacks / 32;
+ const bool do_last_iter =
+ (kNumSFPacks % 32 != 0) and
+ (kNumFullIters * 32 + lane_idx < kNumSFPacks);
+ EP_STATIC_ASSERT(sizeof(sf_pack_t) % 4 == 0,
+ "Unaligned SF element type");
+
+ // Load into registers
+ const auto smem_src_ptr = tma_buffer.get_sf_ptr();
+ sf_pack_t reg_src[kNumFullIters + 1];
+#pragma unroll
+ for (int k = 0; k < kNumFullIters; ++k)
+ reg_src[k] = smem_src_ptr[k * 32 + lane_idx];
+ if (do_last_iter)
+ reg_src[kNumFullIters] =
+ smem_src_ptr[kNumFullIters * 32 + lane_idx];
+
+ // Prepare strides
+ const auto recv_sf_token_stride_i64 =
+ static_cast(recv_sf_token_stride);
+ const auto recv_sf_hidden_stride_i64 =
+ static_cast(recv_sf_hidden_stride);
+
+ // Iterate through all valid indices and store into output buffer
+ auto mask = kDoExpand ? ptx::gather(dst_tensor_idx >= 0) : 1;
+ while (mask) {
+ const int valid_lane_idx = __ffs(mask) - 1;
+ const auto gmem_dst = math::advance_ptr(
+ recv_sf,
+ ptx::exchange(dst_tensor_idx, valid_lane_idx) *
+ (recv_sf_token_stride_i64 * sizeof(sf_pack_t)));
+#pragma unroll
+ for (int k = 0; k < kNumFullIters; ++k)
+ gmem_dst[(k * 32 + lane_idx) * recv_sf_hidden_stride_i64] =
+ reg_src[k];
+ if (do_last_iter)
+ gmem_dst[(kNumFullIters * 32 + lane_idx) *
+ recv_sf_hidden_stride_i64] =
+ reg_src[kNumFullIters];
+ mask ^= 1 << valid_lane_idx;
+ }
+ }
+
+ // Store the top-k weights
+ if (kDoExpand and recv_topk_weights != nullptr and
+ dst_tensor_idx >= 0) {
+ recv_topk_weights[dst_tensor_idx] =
+ tma_buffer.get_topk_weights_ptr()[lane_idx];
+ } else if (not kDoExpand and recv_topk_weights != nullptr and
+ lane_idx < kNumTopk) {
+ // For backward, weights are optional
+ recv_topk_weights[i * kNumTopk + lane_idx] =
+ tma_buffer.get_topk_weights_ptr()[lane_idx];
+ }
+ __syncwarp();
+
+ // Write source token index
+ // And:
+ // - Non-hybrid mode: the source scaleup peer rank index and master
+ // top-k lane index
+ // - Hybrid mode: the slot index and master top-k lane index
+ constexpr int kMetadataStride = 2 + kNumTopk;
+ if (ptx::elect_one_sync()) {
+ recv_src_metadata[i * kMetadataStride + 0] =
+ *tma_buffer.get_src_token_global_idx_ptr();
+ if constexpr (kNumScaleoutRanks == 1) {
+ recv_src_metadata[i * kMetadataStride + 1] =
+ current_rank_idx * kNumTopk + master_src_topk_idx;
+ } else {
+ recv_src_metadata[i * kMetadataStride + 1] =
+ (i - current_rank_start) * kNumTopk + master_src_topk_idx;
+ }
+ }
+ __syncwarp();
+
+ // Write reduction source indices
+ if (kDoExpand and lane_idx < kNumTopk)
+ recv_src_metadata[i * kMetadataStride + 2 + lane_idx] =
+ dst_tensor_idx;
+ __syncwarp();
+ }
+
+ // Maintain linked list's ending
+ // Or you can understand it as writing the tail at once
+ if constexpr (kDoCreateLinkedList) {
+ constexpr int kNumScaleupRanksPerLane =
+ math::constexpr_ceil_div(kNumScaleupRanks, 32);
+ const auto workspace_layout = layout::WorkspaceLayout(
+ workspace, kNumScaleoutRanks, kNumScaleupRanks, kNumExperts);
+ for (int i = global_warp_idx; i < kNumChannels;
+ i += kNumSMs * kNumWarps) {
+#pragma unroll
+ for (int j = 0; j < kNumScaleupRanksPerLane; ++j) {
+ if (const auto k = j * 32 + lane_idx;
+ j < (kNumScaleupRanksPerLane - 1) or k < kNumScaleupRanks) {
+ channel_linked_list
+ [*workspace_layout.get_channel_scaleup_tail_ptr(i, k)] =
+ -1;
+
+ // Clean for combine usages
+ *workspace_layout.get_channel_scaleup_tail_ptr(i, k) = 0;
+ }
+ }
+ __syncwarp();
+ }
+ }
+}
+
+} // namespace mooncake::elastic
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_deterministic_prologue.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_deterministic_prologue.cuh
new file mode 100644
index 0000000000..323f81d5fb
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_deterministic_prologue.cuh
@@ -0,0 +1,171 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+
+#include
+#include
+#include
+
+namespace mooncake::elastic {
+
+// Slot preassignment runs in the active scale-up domain. Hybrid scale-out
+// forwarding is handled by the hybrid dispatch kernel.
+template
+__global__ void __launch_bounds__(kNumThreads, 1)
+ dispatch_deterministic_prologue_impl(topk_idx_t* topk_idx,
+ int* rank_count_buffer,
+ int* dst_buffer_slot_idx,
+ const int num_tokens,
+ const int scaleup_rank_idx) {
+ constexpr int kNumExpertsPerRank = kNumExperts / kNumScaleupRanks;
+ EP_STATIC_ASSERT(kNumExperts % kNumScaleupRanks == 0,
+ "Invalid number of experts or ranks");
+
+ // Utils
+ const auto sm_idx = static_cast(blockIdx.x),
+ thread_idx = static_cast(threadIdx.x);
+ const auto warp_idx = ptx::get_warp_idx(), lane_idx = ptx::get_lane_idx();
+ const auto global_warp_idx = sm_idx * kNumWarps + warp_idx;
+
+ // Token region the current warp is responsible for
+ const auto num_tokens_per_warp =
+ math::ceil_div(num_tokens, kNumSMs * kNumWarps);
+ const auto start_token_idx = global_warp_idx * num_tokens_per_warp;
+ const auto end_token_idx =
+ min(start_token_idx + num_tokens_per_warp, num_tokens);
+
+ // Group configs
+ // NOTES: Group refers to the tokens that each warp handles concurrently
+ constexpr int kNumTokensPerGroup = 32 / kNumTopk;
+ const auto token_idx_offset = lane_idx / kNumTopk;
+ const unsigned token_mask = ((1u << kNumTopk) - 1)
+ << (token_idx_offset * kNumTopk);
+ EP_STATIC_ASSERT(kNumTopk <= 32, "Too many top-k");
+
+ // Shared memory for reduction
+ // NOTES: Each warp owns separate shared memory region for separate sum.
+ extern __shared__ int8_t smem[];
+ const auto rank_count_global_psum = math::advance_ptr(smem, 0);
+ const auto rank_count_warp_sum = math::advance_ptr(
+ rank_count_global_psum,
+ (kNumScaleupRanks + warp_idx * kNumScaleupRanks) * sizeof(int));
+ const auto rank_count_warp_psum = math::advance_ptr(
+ rank_count_warp_sum, kNumWarps * kNumScaleupRanks * sizeof(int));
+
+ // Initialize to zero before reduce
+ for (int i = thread_idx; i < kNumScaleupRanks * (1 + 2 * kNumWarps);
+ i += kNumThreads)
+ reinterpret_cast(smem)[i] = 0;
+ __syncthreads();
+
+ // Util functions
+ const auto map_expert_to_rank_idx = [&](const int& expert_idx) {
+ return expert_idx >= 0 ? expert_idx / kNumExpertsPerRank : -1;
+ };
+ const auto is_unique = [&](const int& rank_idx) {
+ return ((ptx::match(rank_idx) & token_mask) >> lane_idx) == 1;
+ };
+ const auto count_ones_before = [&](const unsigned& mask,
+ const int& bit_idx) {
+ return __popc(mask & ((1u << bit_idx) - 1));
+ };
+ const auto get_other_rank_count_warp_sum = [&](const int& other_warp_idx) {
+ // NOTES: pass negative num_bytes to advance pointer
+ return math::advance_ptr(
+ rank_count_warp_sum,
+ (other_warp_idx - warp_idx) * kNumScaleupRanks * sizeof(int));
+ };
+
+ // Each warp scan the tokens separately
+ for (int i = start_token_idx; i < end_token_idx; i += kNumTokensPerGroup) {
+ const auto token_idx = i + token_idx_offset;
+ const auto is_active_thread =
+ lane_idx < kNumTopk * kNumTokensPerGroup and
+ token_idx < end_token_idx;
+ const int expert_idx =
+ is_active_thread
+ ? static_cast(__ldg(topk_idx + i * kNumTopk + lane_idx))
+ : -1;
+ const auto rank_idx = map_expert_to_rank_idx(expert_idx);
+
+ // Avoid duplicate messages to a single rank
+ const auto deduped_rank_idx = is_unique(rank_idx) ? rank_idx : -1;
+ const auto rank_idx_mask = ptx::match(deduped_rank_idx);
+
+ // Let the one with the largest lane index send the count
+ if ((rank_idx_mask >> lane_idx) == 1 and deduped_rank_idx >= 0)
+ rank_count_warp_sum[deduped_rank_idx] += __popc(rank_idx_mask);
+ }
+ __syncthreads();
+
+ // Get block sum and store to global
+ for (int rank_idx = thread_idx; rank_idx < kNumScaleupRanks;
+ rank_idx += kNumThreads) {
+ int rank_count_block_sum = 0;
+ for (int i = 0; i < kNumWarps; i++)
+ rank_count_block_sum += get_other_rank_count_warp_sum(i)[rank_idx];
+ rank_count_buffer[sm_idx * kNumScaleupRanks + rank_idx] =
+ rank_count_block_sum;
+ }
+ cooperative_groups::this_grid().sync();
+
+ // Get the prefix sum before the current SM
+ for (int rank_idx = lane_idx; rank_idx < kNumScaleupRanks; rank_idx += 32) {
+ int rank_count = 0;
+ for (int i = warp_idx; i < sm_idx; i += kNumWarps)
+ rank_count += rank_count_buffer[i * kNumScaleupRanks + rank_idx];
+ atomicAdd_block(rank_count_global_psum + rank_idx, rank_count);
+ }
+ __syncthreads();
+
+ // Get each warp's prefix sum
+ for (int rank_idx = lane_idx; rank_idx < kNumScaleupRanks; rank_idx += 32) {
+ int rank_count = rank_count_global_psum[rank_idx];
+ for (int i = 0; i < warp_idx; i++)
+ rank_count += get_other_rank_count_warp_sum(i)[rank_idx];
+ rank_count_warp_psum[rank_idx] = rank_count;
+ }
+ __syncwarp();
+
+ // Each warp scan the tokens separately
+ for (int i = start_token_idx; i < end_token_idx; i += kNumTokensPerGroup) {
+ const auto token_idx = i + token_idx_offset;
+ const auto is_active_thread =
+ lane_idx < kNumTopk * kNumTokensPerGroup and
+ token_idx < end_token_idx;
+ const auto expert_idx =
+ is_active_thread
+ ? static_cast(__ldg(topk_idx + i * kNumTopk + lane_idx))
+ : -1;
+ const auto rank_idx = map_expert_to_rank_idx(expert_idx);
+
+ // Avoid duplicate messages to a single rank
+ const auto deduped_rank_idx = is_unique(rank_idx) ? rank_idx : -1;
+ const auto rank_idx_mask = ptx::match(deduped_rank_idx);
+
+ // Store to target buffer
+ const auto stored_dst_slot_idx =
+ deduped_rank_idx >= 0
+ ? rank_count_warp_psum[deduped_rank_idx] +
+ count_ones_before(rank_idx_mask, lane_idx)
+ : -1;
+ const auto value =
+ stored_dst_slot_idx >= 0
+ ? scaleup_rank_idx * kNumMaxTokensPerRank + stored_dst_slot_idx
+ : -1;
+ if (is_active_thread)
+ dst_buffer_slot_idx[i * kNumTopk + lane_idx] = value;
+
+ // Let the one with the largest lane index send the count
+ if ((rank_idx_mask >> lane_idx) == 1 and deduped_rank_idx >= 0)
+ rank_count_warp_psum[deduped_rank_idx] += __popc(rank_idx_mask);
+ __syncwarp();
+ }
+}
+
+} // namespace mooncake::elastic
diff --git a/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_official.cuh b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_official.cuh
new file mode 100644
index 0000000000..761392dde4
--- /dev/null
+++ b/mooncake-ep/include/elastic/mooncake_ep_elastic_dispatch_official.cuh
@@ -0,0 +1,512 @@
+// Ported from DeepEP official elastic source.
+// Mooncake changes: namespace switched to mooncake::elastic and NCCL GIN
+// transport references are replaced with Mooncake Device API adapters.
+#pragma once
+
+#include
+
+#include
+#include
+#include
+#include
+#include
+#include
+#include
+
+namespace mooncake::elastic {
+
+template >
+__global__ void __launch_bounds__(kNumThreads, 1)
+ dispatch_impl(void* x, sf_pack_t* sf, topk_idx_t* topk_idx,
+ float* topk_weights, topk_idx_t* copied_topk_idx,
+ int* cumulative_local_expert_recv_stats,
+ int* psum_num_recv_tokens_per_scaleup_rank,
+ int* psum_num_recv_tokens_per_expert,
+ int* dst_buffer_slot_idx, const int num_tokens,
+ const int sf_token_stride, const int sf_hidden_stride,
+ const device::CommCtx comm_ctx, void* buffer, void* workspace,
+ void* mapped_host_workspace, const int rank_idx) {
+ constexpr int kNumExpertsPerRank = kNumExperts / kNumRanks;
+ EP_STATIC_ASSERT(kNumExperts % kNumRanks == 0,
+ "Invalid number of experts or ranks");
+ EP_STATIC_ASSERT(kNumNotifyWarps % 4 == 0, "Invalid warpgroup size");
+
+ // Utils
+ const auto sm_idx = static_cast(blockIdx.x),
+ thread_idx = static_cast(threadIdx.x);
+ const auto warp_idx = ptx::get_warp_idx(), lane_idx = ptx::get_lane_idx();
+
+ // Workspaces
+ const auto workspace_layout =
+ layout::WorkspaceLayout(workspace, 1, kNumRanks, kNumExperts);
+ const auto host_workspace_layout = layout::WorkspaceLayout(
+ mapped_host_workspace, 1, kNumRanks, kNumExperts);
+
+ // The kernel uses a fixed space of dynamic shared memory (no static shared
+ // memory)
+ extern __shared__ __align__(ptx::kNumTMAAlignBytes) int8_t smem[];
+ constexpr int kNumSmemBytesForNotify =
+ kNumNotifyThreads > 0 ? math::constexpr_align(kNumRanks + kNumExperts,
+ kNumNotifyThreads) *
+ sizeof(int)
+ : 0;
+ EP_STATIC_ASSERT(kNumSmemBytesForNotify % ptx::kNumTMAAlignBytes == 0,
+ "Invalid TMA alignment");
+
+ // Named barrier indices
+ constexpr int kNotifyBarrierIndex = 1;
+
+ // Gin handle
+ // We treat each warp as a "channel"
+ const auto [qp_idx, sharing_mode] =
+ comm::get_qp_mode 0)>(
+ sm_idx, warp_idx - kNumNotifyWarps, warp_idx < kNumNotifyWarps);
+ const auto gin = transport::MooncakeGin(comm_ctx, qp_idx, sharing_mode,
+ kNumQPs, 0, 0, 0, kNumRanks);
+
+ // Barrier without TMA store flush, without prologue grid sync
+ comm::gpu_barrier(gin, workspace_layout, 0, rank_idx, sm_idx,
+ thread_idx);
+
+ // Different warp roles
+ if (warp_idx < kNumNotifyWarps) {
+ // Assign shared memory
+ constexpr int kNumAlignedElems = kNumSmemBytesForNotify / sizeof(int);
+ const auto rank_expert_count = math::advance_ptr(smem, 0);
+
+ // Clean initial counts
+ // NOTES: if you want to change the order of different warp roles,
+ // please take care of the `thread_idx`
+ int *rank_count = rank_expert_count,
+ *expert_count = rank_expert_count + kNumRanks;
+#pragma unroll
+ for (int i = 0; i < kNumAlignedElems / kNumNotifyThreads; ++i)
+ rank_expert_count[i * kNumNotifyThreads + thread_idx] = 0;
+ ptx::named_barrier(kNotifyBarrierIndex);
+
+ // Atomic add on shared memory
+ EP_STATIC_ASSERT(kNumTopk <= 32, "Insufficient lanes");
+ const auto global_warp_idx = warp_idx * kNumSMs + sm_idx;
+ for (int i = global_warp_idx; i < num_tokens;
+ i += kNumNotifyWarps * kNumSMs) {
+ // Expert choice can not be redundant
+ // NOTES: no assertions here as they are expensive
+ const auto dst_expert_idx =
+ lane_idx < kNumTopk ? static_cast(__ldg(
+ topk_idx + i * kNumTopk + lane_idx))
+ : -1;
+ if (dst_expert_idx >= 0)
+ atomicAdd_block(expert_count + dst_expert_idx, 1);
+
+ // Rank choice should do deduplication here
+ const auto dst_rank_idx =
+ dst_expert_idx >= 0 ? dst_expert_idx / kNumExpertsPerRank : -1;
+ if (ptx::deduplicate(dst_rank_idx, lane_idx) and dst_rank_idx >= 0)
+ atomicAdd_block(rank_count + dst_rank_idx, 1);
+ }
+ ptx::named_barrier(kNotifyBarrierIndex);
+
+// Do full-grid reduction
+#pragma unroll
+ for (int i = thread_idx; i < kNumRanks + kNumExperts;
+ i += kNumNotifyThreads) {
+ const int64_t counter = (1ll << 32ll) | rank_expert_count[i];
+ ptx::red_add(
+ workspace_layout.get_notify_reduction_workspace_ptr() + i,
+ counter);
+ }
+
+ // Do the remaining work by SM 0
+ if (sm_idx == 0) {
+// Reduce all SM's count
+// Wait all SMs' arrival
+#pragma unroll
+ for (int i = thread_idx; i < kNumRanks + kNumExperts;
+ i += kNumNotifyThreads) {
+ comm::timeout_while<
+ kNumTimeoutCycles>(true, [=](const bool& is_last_check) {
+ const auto status = ptx::ld_volatile(
+ workspace_layout.get_notify_reduction_workspace_ptr() +
+ i);
+ if ((status >> 32) == kNumSMs) {
+ // Write into shared memory
+ // Write into send buffer if with RDMA
+ const auto encoded = math::encode_decode_positive(
+ static_cast(status & 0xffffffffll));
+ rank_expert_count[i] = encoded;
+ if constexpr (not kIsScaleupNVLink)
+ workspace_layout
+ .get_scaleup_rank_expert_count_ptr()[i] =
+ encoded;
+
+ // Clean for the next usage
+ workspace_layout
+ .get_notify_reduction_workspace_ptr()[i] = 0;
+ return true;
+ }
+
+ if (is_last_check) {
+ printf(
+ "DeepEP notify (GPU reduction) timeout, rank: "
+ "%d/%d, "
+ "thread: %d, status: %d | %d, expected: %d\n",
+ rank_idx, kNumRanks, thread_idx,
+ static_cast(status >> 32),
+ static_cast(status & 0xffffffff), kNumSMs);
+ }
+ return false;
+ });
+ }
+ ptx::named_barrier(kNotifyBarrierIndex);
+
+ // TODO: for further optimization, we can fuse rank and expert
+ // counters Issue scaleup rank count writes to peers
+ for (int i = thread_idx; i < kNumRanks; i += kNumNotifyThreads) {
+ // Rank counters
+ const auto dst_rank_counter =
+ workspace_layout.get_scaleup_rank_count_ptr() +
+ rank_idx;
+ gin.put_value(dst_rank_counter,
+ static_cast(rank_count[i]), i,
+ 0);
+ }
+ __syncwarp();
+
+ // Issue scaleup expert count writes to peers
+ if constexpr (kIsScaleupNVLink) {
+ // NVLink per-element copy
+ // We don't use TMA as the dtype of shared memory and global is
+ // different
+ for (int i = thread_idx; i < kNumExperts;
+ i += kNumNotifyThreads) {
+ const auto idx = kNumExpertsPerRank * rank_idx +
+ (i % kNumExpertsPerRank);
+ gin.put_value(
+ workspace_layout.get_scaleup_expert_count_ptr() +
+ idx,
+ static_cast(expert_count[i]),
+ i / kNumExpertsPerRank);
+ }
+ } else {
+ // RDMA bulk copy
+ for (int i = thread_idx; i < kNumRanks;
+ i += kNumNotifyThreads) {
+ const auto src_ptr =
+ workspace_layout.get_scaleup_expert_count_ptr() +
+ kNumExpertsPerRank * i;
+ const auto dst_ptr =
+ workspace_layout.get_scaleup_expert_count_ptr() +
+ kNumExpertsPerRank * rank_idx;
+ gin.put(dst_ptr, src_ptr,
+ kNumExpertsPerRank * sizeof(int64_t), i);
+ }
+ }
+
+ // This is necessary, as the waited results will rewrite the shared
+ // memory
+ ptx::named_barrier(kNotifyBarrierIndex);
+
+ // Wait for rank and expert count
+ const auto start_clock = clock64();
+ for (int i = thread_idx; i < kNumRanks + kNumExperts;
+ i += kNumNotifyThreads) {
+ comm::timeout_while(
+ [=](const bool& is_last_check) {
+ // NOTES: the global memory type has 64 bits
+ const auto count = static_cast<
+ int>(ptx::ld_volatile