This big data project will look at Hive's capabilities to run analytical queries on massive datasets. We will use the Adventure works dataset in a MySQL dataset for this project, and we'll need to ingest and modify the data. We'll use Adventure works sales and Customer demographics data to perform analysis and answer the following questions:
- Sqoop
- Hive
- PySpark
Adventure Works is a free sample database of retail sales data. In this project, we will be only using Customer test, Individual test, Credit card, Sales order details, Store, Sales territory, Salesperson, Sales order header, Special offer tables from this database.
Customer Test: This table contain all customer data related information.
Individual Text: This table contain all Individual data information.
Credit Card: This table contain all credit card data information.

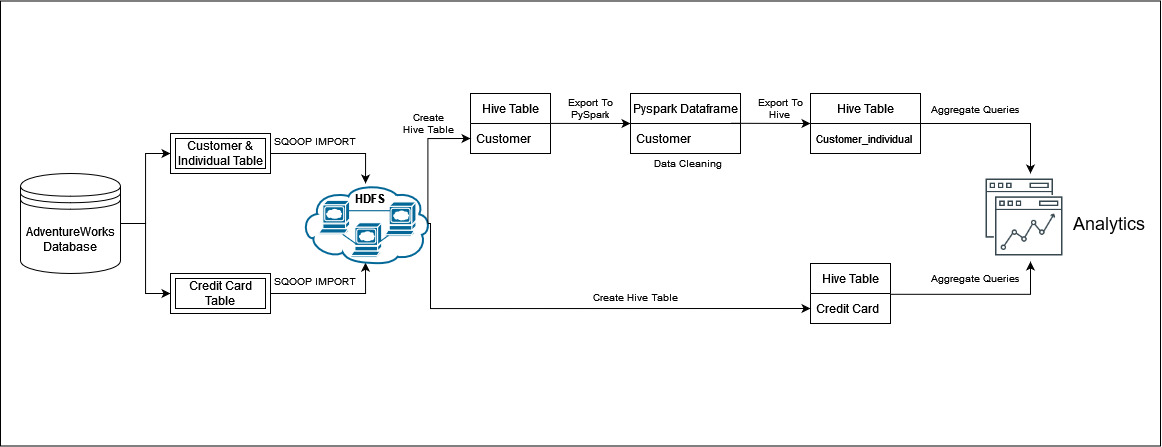
- Create tables in MySQL database.
- Load data from MySQL into HDFS storage using Sqoop commands.
- Move data from HDFS to Hive.
- Integrate Hive into Spark and perform data cleaning.
- Using Pyspark, extract Customer demographics information from data and store it as parquet files.
- Move parquet files from Spark to Hive.
- Create tables in Hive and load data from Parquet files into tables.
- Perform Hive analytics on Sales and Customer demographics data.