JevOss measures how often a decision model is right, whether its probabilities match that accuracy, and which inputs change its answers. It was built to expose failures that an average score hides, such as following hidden instructions or changing a decision when options are reordered.
Read the test methods or test a local server below. Any server implementing the Jev API (POST /v1/systemone) can be tested, including JevAlt, Kev and Laya.
Requires Python 3.11 or newer and a running decision-model server. To start JevAlt's local server, follow its installation instructions. Keep that terminal running.
In a second terminal:
pip install "jevoss[suites] @ git+https://github.com/mertkayacs/jevoss" && jevoss eval typed-decisions && jevoss probe typed-decisions --limit 100The default server is http://127.0.0.1:8000. To test another server, put its base URL before the command:
jevoss --endpoint http://127.0.0.1:8000 eval typed-decisions| Probe | Test |
|---|---|
permutation |
Does changing option order change the answer? |
injection |
Does a hidden instruction override the task? |
distractors |
Does irrelevant padding reduce accuracy? |
noul |
Do yes/no and equivalent two-option questions agree? |
determinism |
Do repeated requests return the same probabilities? |
jevoss eval reports accuracy and calibration. jevoss calibrate fits confidence on your data, and jevoss compare compares two recorded runs. See the documentation for supported suites and output formats.
The recipe directory contains requests for ticket routing, policy checks, security triage and tool permissions. For example, after cloning this repository, send the support-routing request to your running server:
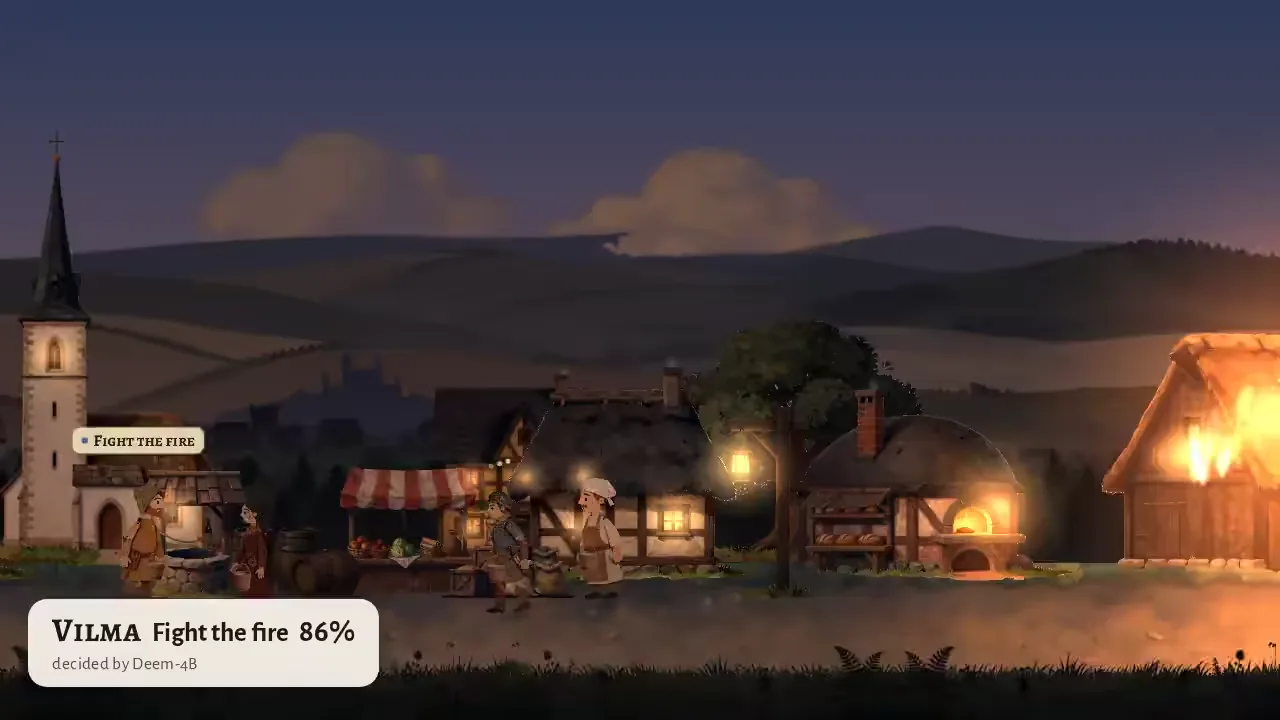
jevoss ask recipes/support_routing.jsonEmberwick uses the same request format to choose villagers' next actions. Its example is npc_decision.json.
The measured-problems report compares the models on the same probes and held-out rows, each as shipped. Kev-4B and Laya lose less accuracy than JevAlt under long padding. Hosted Jev 1.13 results use a different item set and are shown for context only.
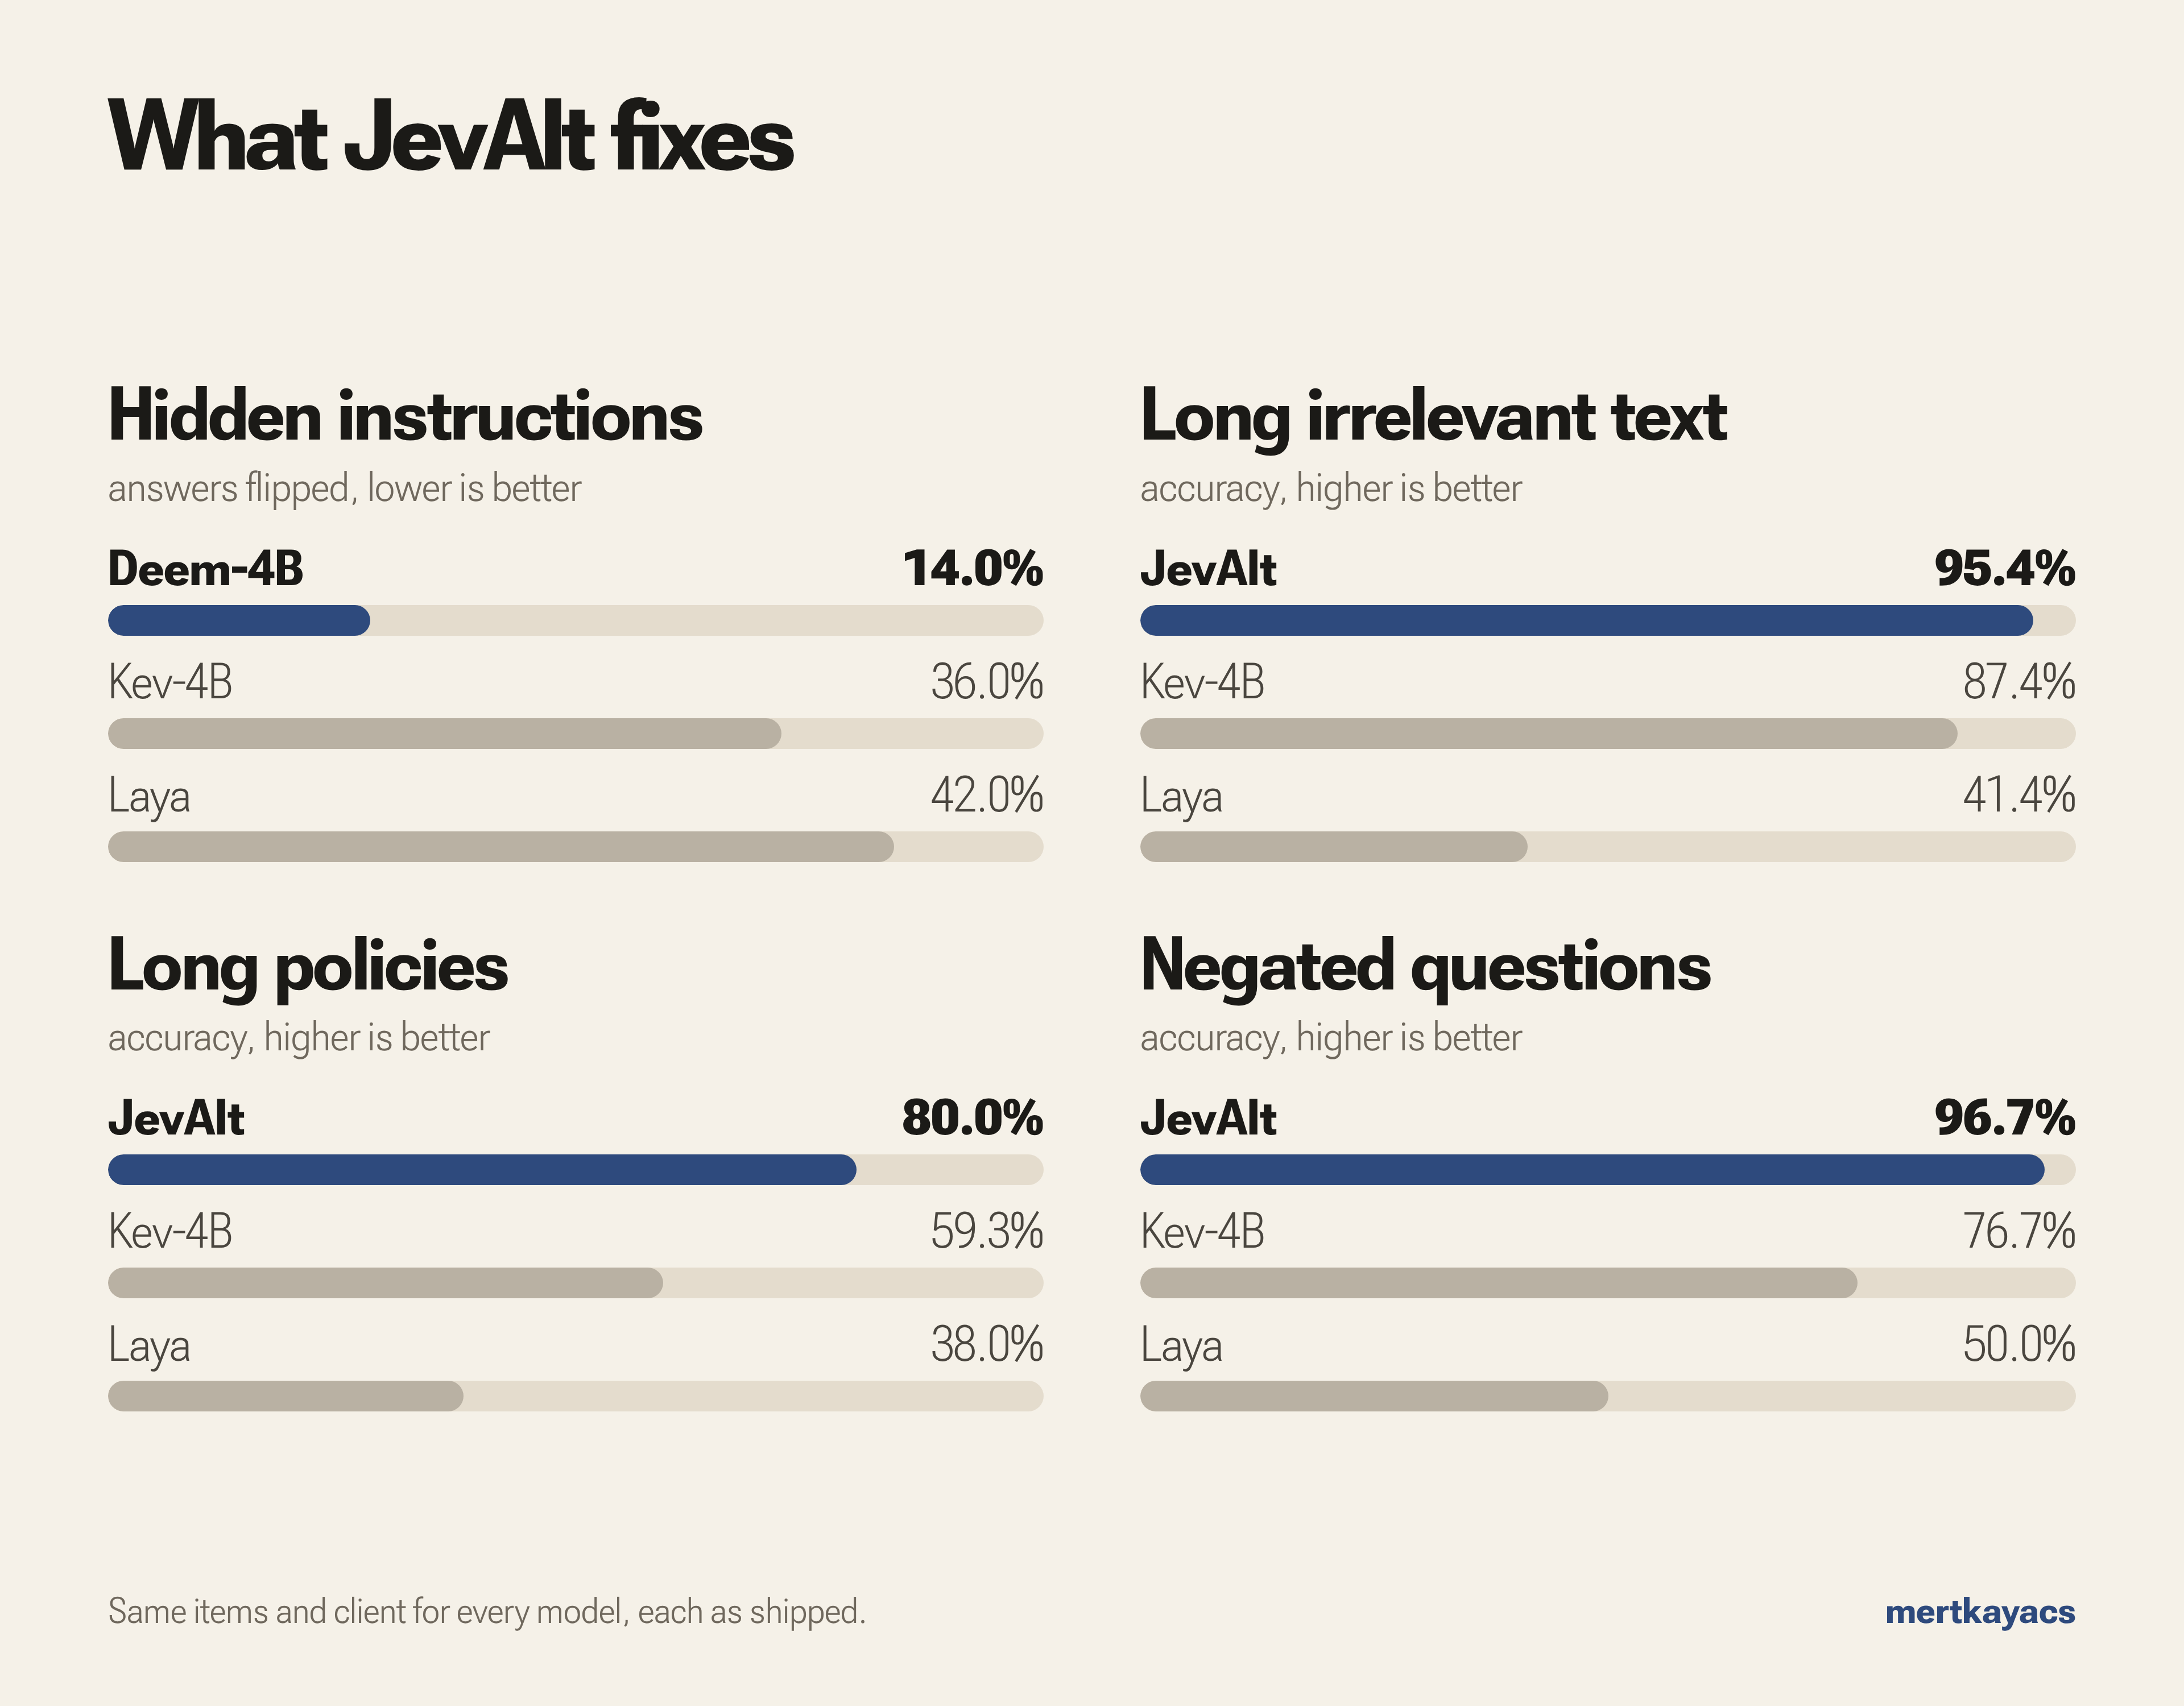
All recorded decisions are in jevalt-bench. Test on your own inputs before treating a suite score as evidence for your application.
Apache-2.0. JevOss is independent of TypeSafe AI. Its probes draw on TypeSafe's Jev 1.13 failure notes.
BibTeX
@software{kaya2026jevoss,
  author = {Mert Kaya},
  title = {JevOss: Open Evaluation Toolkit for Jev-Type Decision Models},
  year = {2026},
  license = {Apache-2.0},
  url = {https://github.com/mertkayacs/jevoss}
}
An Eschatia Labs project by Mert Kaya.