
Clustering PPINs by GO similarity scores.
Uses STRINGdb and INet networks, GSE23561 microarray gene expressions data, GOSemSim and org.Hs.ed.db packages.
You first need download and export the PPI data (i.e. link files) into LINKS/ directory using the download instructions given in LINKS/DOWNLOAD.txt.
To be able run the pipeline with different Gene Expression and PPI data, you must apply the following changes:
-
Replace the
RAW.csvfile with your own gene expression data. This is a comma-separated matrix, where each column represents genes and each column represents the subjects (i.e., persons or test-conditions). Please, see theRAW.csvas an example. -
Put the PPI file to the
LINKS/directory. This file must consist of a comma-separated edgelist representing the PPI score (i.e., weight) for the gene pairs. Please, see theLINKS/elinks_inet.csvas an example. -
Update the variables in the
vars.Rfile to match your Gene Expression and PPI data. It is necessary to reassign the ranges (i.e.,intervals) in order to correctly separate the control group and each disease group in Gene Expression matrix. It is also necessary to reset thecutoffvalue for PPI scores used in PPIN reduction. Invars.R, you can also change the t-test significance (P_VAL) and the fold-change threshold (FC) that are used in the DEG analysis.
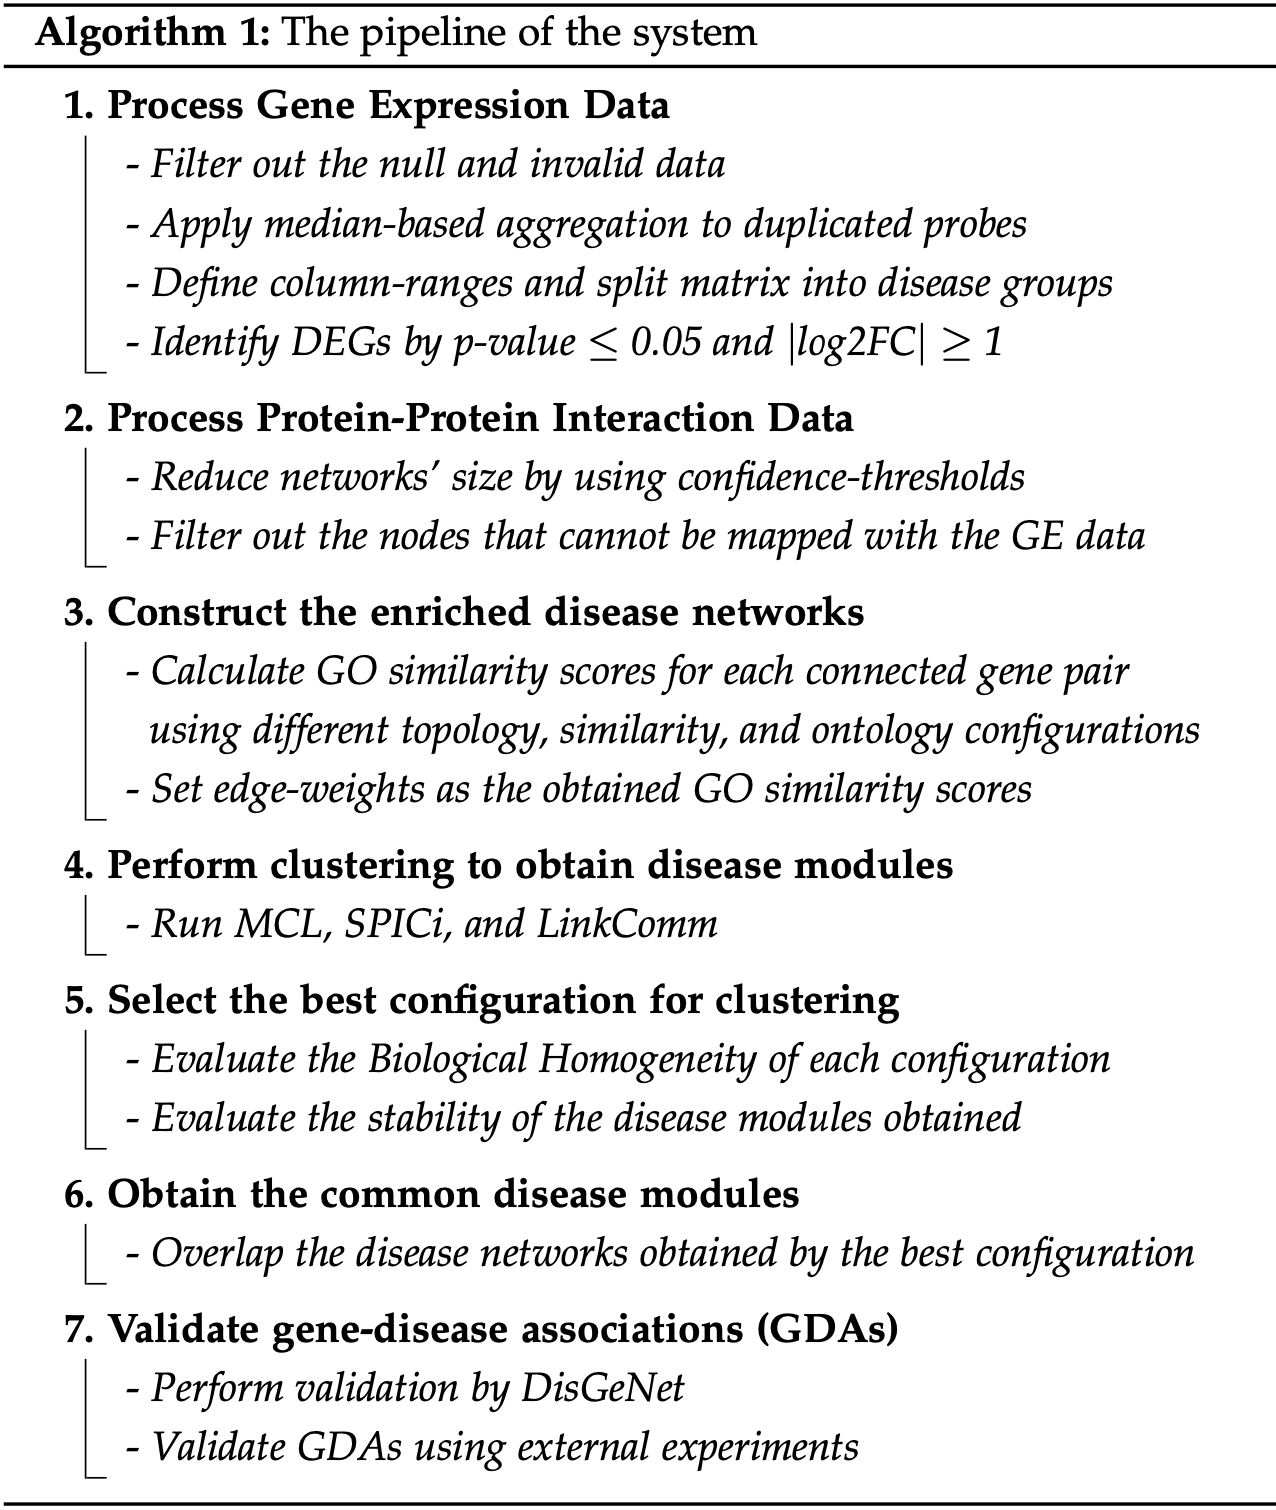
vars.Rmanages the packages, global variables, paths, and I/O files.degs.Rincludes the necessary functions to identify differentially expressed genes.links.Rhandles reading, preprocessing, and mapping of PPI data.msLinks.Rresponsible from filtering out unmapped and insignificant PPIs.go.Rfetches GO information and calculates the GO similarity scores.spici.R,mcl.R,linkcomm.Rperforms the clustering operations.bhi.Rcalculates Biological Homogeneity Index for the clusters.stability.Rcalculates stability of disease modules.validation.Rsearches for the identified genes in DEGS of the validation sets.plot.Rresponsible from generating the plots for the obtained results.stats.R,bhi_stats.Rcreates tables including statistics about the clustering or validation.
It is highly recommended to install all packages required in the vars.R file.
To overcome possible dependency problems, please run the scripts in the following order, and note that all scripts depend to vars.R which manages the packages as well as the global paths, files, and variables:
vars.R ➡️ degs.R ➡️ links.R ➡️ msLinks.R ➡️ go.R ➡️ spici.R || mcl.R || linkcomm.R ➡️ bhi.R || stability.R ➡️ validation.R ➡️ plot.R || stats.R || bhi_stats.R
S. Tenekeci, S. Tekir, Identifying promoter and enhancer sequences by graph convolutional networks, Computational Biology and Chemistry (2024) https://doi.org/10.1016/j.compbiolchem.2024.108040