
Your agent failed. Make the failure a test.
Local-first behavioral regression testing for AI agents.
Stepfork is for developers building AI agents who need to:
- Turn production failures into reproducible regression tests
- Debug multi-step agent behaviors without re-running live services
- Prevent behavioral regressions when fixing bugs or refactoring code
- Minimize complex failures to their essential reproduction steps
If you're writing evals, Stepfork complements them: evals measure model quality across datasets, Stepfork tests that specific agent behaviors don't break.


Install the alpha: pip install --pre stepfork
Product goal:
Turn a failed AI-agent run into a reproducible pytest regression test, locally, in under five minutes.
AI agents fail in ways unit tests miss. A flight-search agent books the wrong flight. A refund agent denies an eligible claim. When you diagnose such a failure you usually hand-write a fix and hope the regression is covered.
Stepfork records what an agent actually did during a run: every instrumented tool call, every instrumented LLM request, and the final output. When the agent misbehaves, you replay that recording and export it as an executable pytest regression test that asserts the corrected behavior. The test fails on the buggy code and passes on the fix, using the recorded responses instead of live services.
This terminal recording runs the complete failure-to-test flow:

Stepfork turns a failed AI-agent execution into a reproducible pytest regression test.
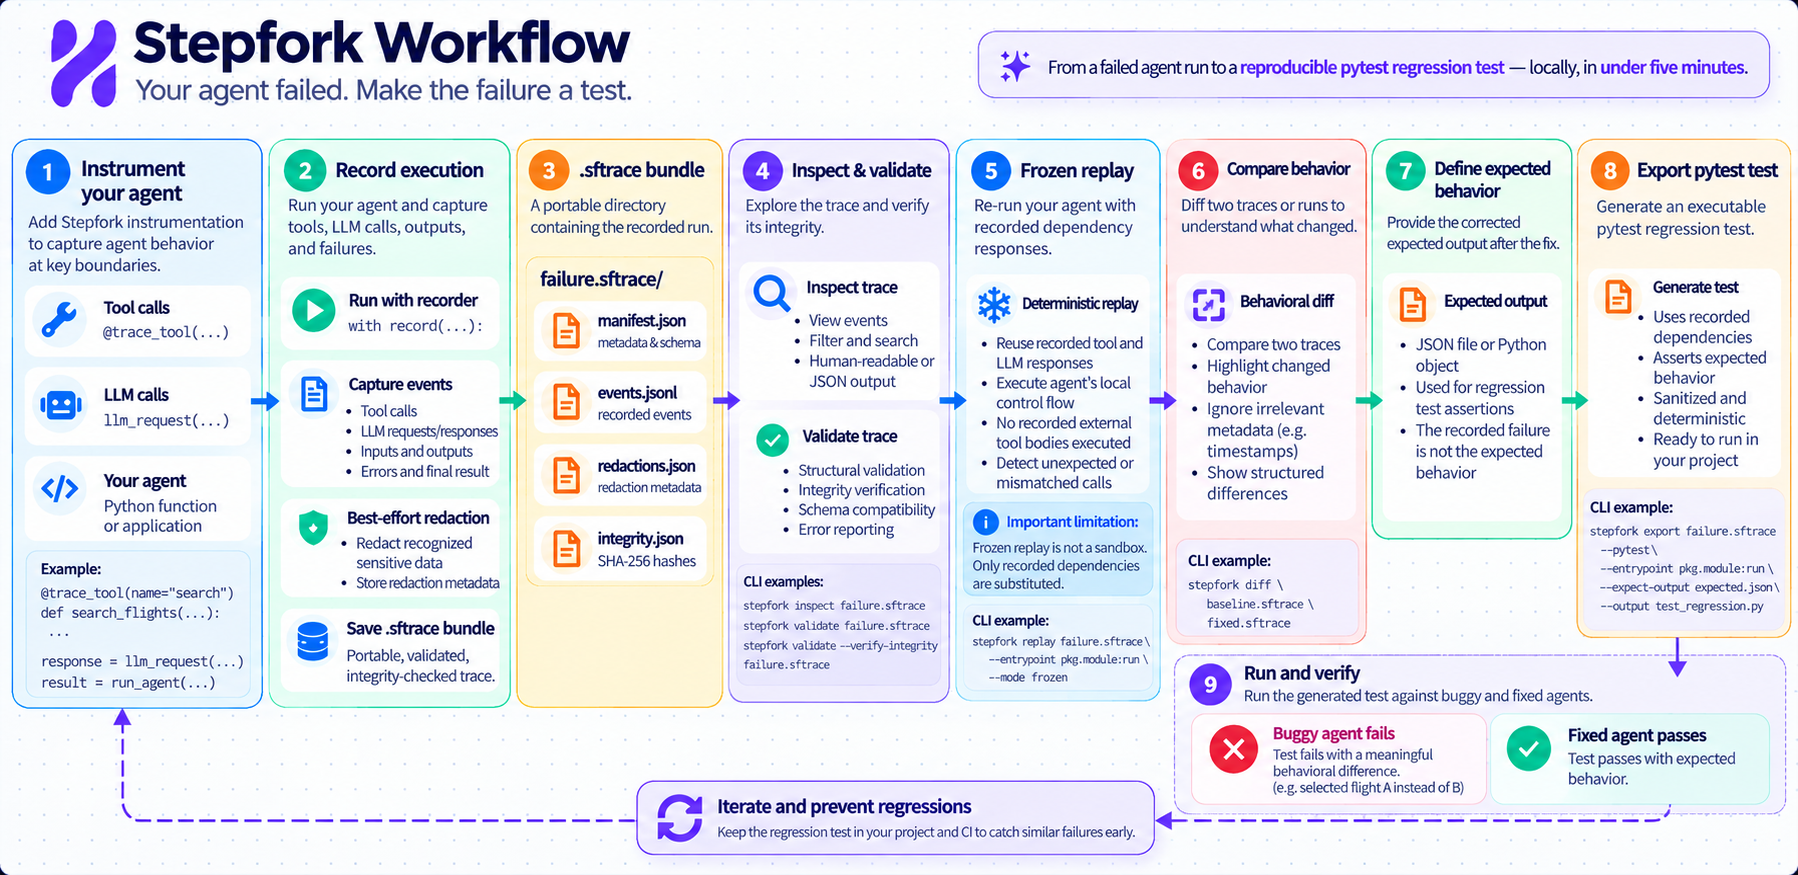
Workflow: Instrument → Record → Inspect → Validate → Frozen Replay → Compare → Define Expected Behavior → Export pytest → Verify Fix
- Record a buggy run into a portable
.sftracebundle, including runs that raise. Recording is local-first; nothing leaves your machine. - Frozen replay reruns your entrypoint with responses taken from the
recording, so instrumented tool and LLM bodies never run again. Calls outside
instrumented boundaries are not intercepted; wrap every external dependency
you want frozen with
@trace_toolorllm_request. - Behavioral diff compares a buggy run against a corrected run and reports exactly which behaviors changed.
- Failure minimization automatically finds the smallest trace that still reproduces a failure via dependency-aware delta debugging.
- Fork-at-step creates new traces at specific execution points with optional output overrides for "what-if" debugging scenarios.
- pytest export turns a recorded failure into a regression test that asserts the corrected behavior.
- Best-effort redaction of known credential-shaped values at record time.
- Integrity verification via SHA-256 digests that make tampering evident.
- Python 3.11, 3.12, and 3.13 support.
| Failure class | Frozen replay | Hybrid replay with a selected live LLM |
|---|---|---|
| Deterministic application logic | Reproduces with recorded dependencies | Can test against reviewed output |
| Tool-result parsing | Reproduces with recorded tool output | Same if the tool remains frozen |
| Tool arguments and orchestration | Strictly matches recorded calls; trajectory assertions check execution | New tool calls diverge before instrumented tool bodies run |
| Model judgment | Repeats the recorded answer only | Re-runs the selected model; outcome is variable |
| Prompt-change evaluation | Rejects a changed prompt as divergence | Allows the selected LLM prompt to change and checks reviewed expectations |
| Uninstrumented side effects | Not intercepted | Not intercepted |
| Nondeterministic execution | May diverge when call order changes | May diverge; model output is also variable |
Frozen replay substitutes recorded dependency responses and tests the application logic around them. It cannot prove that a prompt improves model quality. Hybrid replay explicitly selects LLM boundaries to run again while tools stay frozen and strictly matched. It is not deterministic and may incur network calls, token cost, and latency. Live evaluation means assessing a new model response against reviewed output and trajectory expectations; it is a testing practice using the hybrid API, not a separate replay mode. See hybrid replay.
The existing mode="live" re-executes matching LLM calls. Live tool bodies
now require explicit authorization by name with allow_live_tools={...} or
--allow-live-tool NAME. An authorized tool can send email, charge a card, or
change an external system; the allowlist does not sandbox it. See
live-tool authorization for migration guidance.
Stepfork is published on PyPI. Install the current alpha with:
# pip
pip install --pre stepfork

# uv
uv pip install --pre stepfork
The --pre flag is required while Stepfork is a pre-release. You can also
install from the tagged GitHub repository:
pip install "git+https://github.com/utsab345/stepfork.git@v0.1.0a6"Requires Python 3.11, 3.12, or 3.13. This installs the stepfork CLI and the
Python package. For contributors working from a checkout, use uv sync.
Optional adapters are installed on demand, for example
pip install "stepfork[openai]" or pip install "stepfork[langgraph]".
Fully offline, no API keys, nothing invented. Save the file below as
quickstart.py:
from stepfork import record, trace_tool


@trace_tool(name="order_status")
def order_status(order_id: str) -> dict:
    # Stand-in for your real shipping service. Offline and deterministic.
    return {"order_id": order_id, "status": "shipped", "carrier": "FedEx"}


def run_agent(order_id: str = "ORD-1001") -> dict:
    status = order_status(order_id)
    should_notify = status["status"] == "delivered"  # bug: notifies only on delivery
    return {
        "order_id": order_id,
        "should_notify": should_notify,
        "carrier": status["carrier"],
    }


def run_agent_fixed(order_id: str = "ORD-1001") -> dict:
    status = order_status(order_id)
    should_notify = status["status"] == "shipped"  # fix: notifies when it ships
    return {
        "order_id": order_id,
        "should_notify": should_notify,
        "carrier": status["carrier"],
    }


if __name__ == "__main__":
    with record("notify-agent", output="failure.sftrace") as session:
        result = run_agent()
        session.set_output(result)
    print(result)
The order has shipped, but the buggy agent only notifies on delivery, so it skips the notification. Record that failure:
python quickstart.py{'order_id': 'ORD-1001', 'should_notify': False, 'carrier': 'FedEx'}
Inspect and validate the trace:
stepfork inspect failure.sftrace
stepfork validate failure.sftrace --verify-integrity
Replay the buggy agent with dependencies frozen. The recorded response is substituted; the real tool body never runs:
stepfork replay failure.sftrace --entrypoint quickstart:run_agent --mode frozenStepfork Replay
Trace failure.sftrace
Agent notify-agent
Entrypoint quickstart:run_agent
Mode frozen
Dependency Calls
1. tool order_status (substituted)
Status: COMPLETED
Final result: {"carrier":"FedEx","order_id":"ORD-1001","should_notify":false}
Define the corrected behavior and export a regression test for both the buggy and the fixed implementation:
printf '{"order_id": "ORD-1001", "should_notify": true, "carrier": "FedEx"}' > expected.json

stepfork export failure.sftrace --pytest \
  --entrypoint quickstart:run_agent \
  --expect-output expected.json \
  --output test_notify_buggy.py --overwrite

stepfork export failure.sftrace --pytest \
  --entrypoint quickstart:run_agent_fixed \
  --expect-output expected.json \
  --output test_notify_fixed.py --overwrite
Run the tests. The buggy implementation fails; the fix passes. The exported tests use pytest, which is not a runtime dependency of Stepfork, so install it first if your environment does not already have it:
pip install pytest   # only needed to run the exported regression tests
python -m pytest -q test_notify_buggy.py   # 1 failed (behavior mismatch)
python -m pytest -q test_notify_fixed.py   # 1 passed
That regression test reproduces the exact failure you started with, and now pins the corrected behavior.
Six runnable demo agents ship in this repository (all fully offline, with a fake provider standing in for a real model):
examples/quickstart- a single-tool order-notification agent; the minimal starting point shown above.examples/booking_agent- a fake LLM provider paired with a flight-search tool; books the wrong flight.examples/refund_agent- a fake LLM provider paired with a refund-policy-check tool; denies an eligible refund.examples/openai_chat- the optional OpenAI adapter exercised through a fake OpenAI-shaped sync client; no API key or network call required.examples/langgraph_agent- a real LangGraphStateGraphtraced through the optional LangGraph adapter; makes a wrong refund decision.examples/model_decision- a LangGraph model-decision failure tested with hybrid replay and a deterministic fake provider.
git clone https://github.com/utsab345/stepfork.git
cd stepfork
uv sync
uv run python examples/quickstart/demo.py
uv run python examples/booking_agent/demo.py
uv run python examples/refund_agent/demo.py
uv run python examples/openai_chat/demo.py
uv run python examples/langgraph_agent/demo.py
uv run python examples/model_decision/demo.py
Each demo records a buggy run and exports a regression test that fails on the buggy entrypoint and passes on the fixed one. The model-decision example also shows the limit of frozen replay and a selected live LLM in hybrid replay. The demos print real results from real subprocesses; they never fabricate output.
A complete, offline-reproducible example of Stepfork in practice. A real Google
Gemini 2.5 Flash request (gemini-2.5-flash through the OpenAI SDK adapter)
correctly classified a synthetic production checkout incident as P0. A
deliberately introduced three-line Python postprocessing bug then downgraded
that to P1 and disabled escalation. Stepfork recorded the LLM interaction
and the instrumented tool calls, and a generated pytest regression test failed
against the buggy logic and passed after the fix - using the same recorded
trace.
Frozen replay made zero additional model requests and executed zero instrumented tool bodies.
Real Gemini response: P0
Buggy application:    P1, escalation=false
Regression test:      FAILED

Fixed application:    P0, escalation=true
Same regression test: PASSED

Additional LLM calls during frozen replay: 0
Start with the example
README or read the full
CASE_STUDY.md. The incident and
operational data are synthetic and the application bug was introduced on
purpose; only the model request was real. Stepfork does not know the correct
business outcome - it lives in expected.json, defined by a human.
| Command | Purpose |
|---|---|
stepfork validate [PATH] [--partial] [--verify-integrity] |
Check a .sftrace bundle structurally (and its integrity). |
stepfork inspect [PATH] [--json] [--events] [--errors-only] [--step N] |
Review a bundle locally. |
stepfork replay [PATH] --entrypoint MODULE:FUNCTION [--mode M] |
Rerun the entrypoint with dependencies answered from the trace. |
stepfork diff [BASELINE] [CANDIDATE] [--json] |
Compare the behavior of two runs. |
stepfork export [PATH] --pytest --entrypoint MODULE:FUNCTION [--expect-output JSON] [--expect-trajectory JSON] [--output FILE] [--overwrite] |
Generate an executable pytest regression test. |
The full reference (arguments, examples, expected output, and common errors) is in docs/cli.md.
from stepfork import ToolCall, Trace

trace = Trace(agent_name="demo-agent")

trace.add(ToolCall(name="search", input={"query": "Kathmandu flights"}))

trace.save("demo.sftrace")
loaded = Trace.load("demo.sftrace")
Validate traces:
stepfork validate demo.sftrace --partial
stepfork validate demo.sftrace
stepfork validate demo.sftrace --verify-integrity
The --partial flag is required here because the example intentionally saves
only a tool_call event. Strict execution validation expects a complete trace
with a run_start event.
The full documentation is published at
https://utsab345.github.io/stepfork/;
sources live in docs/.
- Getting started
- How recording works
- Replay
- Behavioral diff
- pytest export
- OpenAI Python SDK adapter
- LangGraph adapter
- CLI reference
- Trace format
- Security notes
- Architecture
- Integrations
- Development
- Release checklist
- PyPI publishing checklist
- Early adopter guide
- Latest release notes (v0.1.0a6)
- Changelog
Stepfork is experimental. The API, CLI, and .sftrace trace format may change
before v1.0.
- Alpha on PyPI.
pip install --pre stepforkinstalls the current pre-release; the API and trace format may still change. - Limited integrations. Optional adapters cover the OpenAI Python SDK
(synchronous and asynchronous, non-streaming
chat.completions.create) and LangGraph (synchronous and asynchronousBaseChatModelgeneration and function-based tools). OpenAI Agents, MCP, streaming, and other providers are planned work. See docs/integrations.md. - Replay is not a sandbox. Running an entrypoint under replay executes your own code with your own privileges. Trace data is never executed, but the entrypoint you name is.
- Only instrumented boundaries are frozen. Frozen replay substitutes calls
made through
@trace_tool,llm_request, andallm_request. Any external call your code makes outside those boundaries is not recorded and is not intercepted. - Redaction is best-effort. Pattern-based redaction can miss sensitive information embedded in unusual tool outputs or domain-specific payloads.
- Replay requires determinism. Dependencies that do not honor the recorded responses can make frozen replay diverge from the recording.
Full details, including the integrity model and how to handle untrusted bundles, are in docs/security.md.
- Portable
.sftrace - Trace save/load
- Structural validation
- Best-effort redaction
- Integrity verification
- Validate CLI
- Inspect CLI
- Runtime recording
- Frozen replay
- Behavioral diff
- pytest export
- PyPI publishing with trusted publishing (OIDC)
- Strict frozen-replay matching and divergence diagnostics
- OpenAI Python SDK adapter (
stepfork[openai]) - LangGraph adapter (
stepfork[langgraph]) - Offline examples for both adapters
- Example GitHub Actions regression workflow
- Failure minimization - Automatic delta debugging to find minimal traces (docs/minimize.md)
- Fork-at-step - Create new traces at specific execution points with optional overrides (docs/fork.md)
- Baselines (planned)
- OpenAI Agents
- MCP
- Reusable GitHub Action
- Local viewer
Contributions are welcome. Start with CONTRIBUTING.md and the code of conduct. Local development instructions live in docs/development.md. If you find a security issue, report it privately per SECURITY.md. Please do not include secrets, credentials, or sensitive trace data in issues, tests, examples, or commits.
Stepfork is licensed under the Apache License, Version 2.0.